bingbangboom/cleaned-asr-transcripts-hinglish
收藏资源简介:
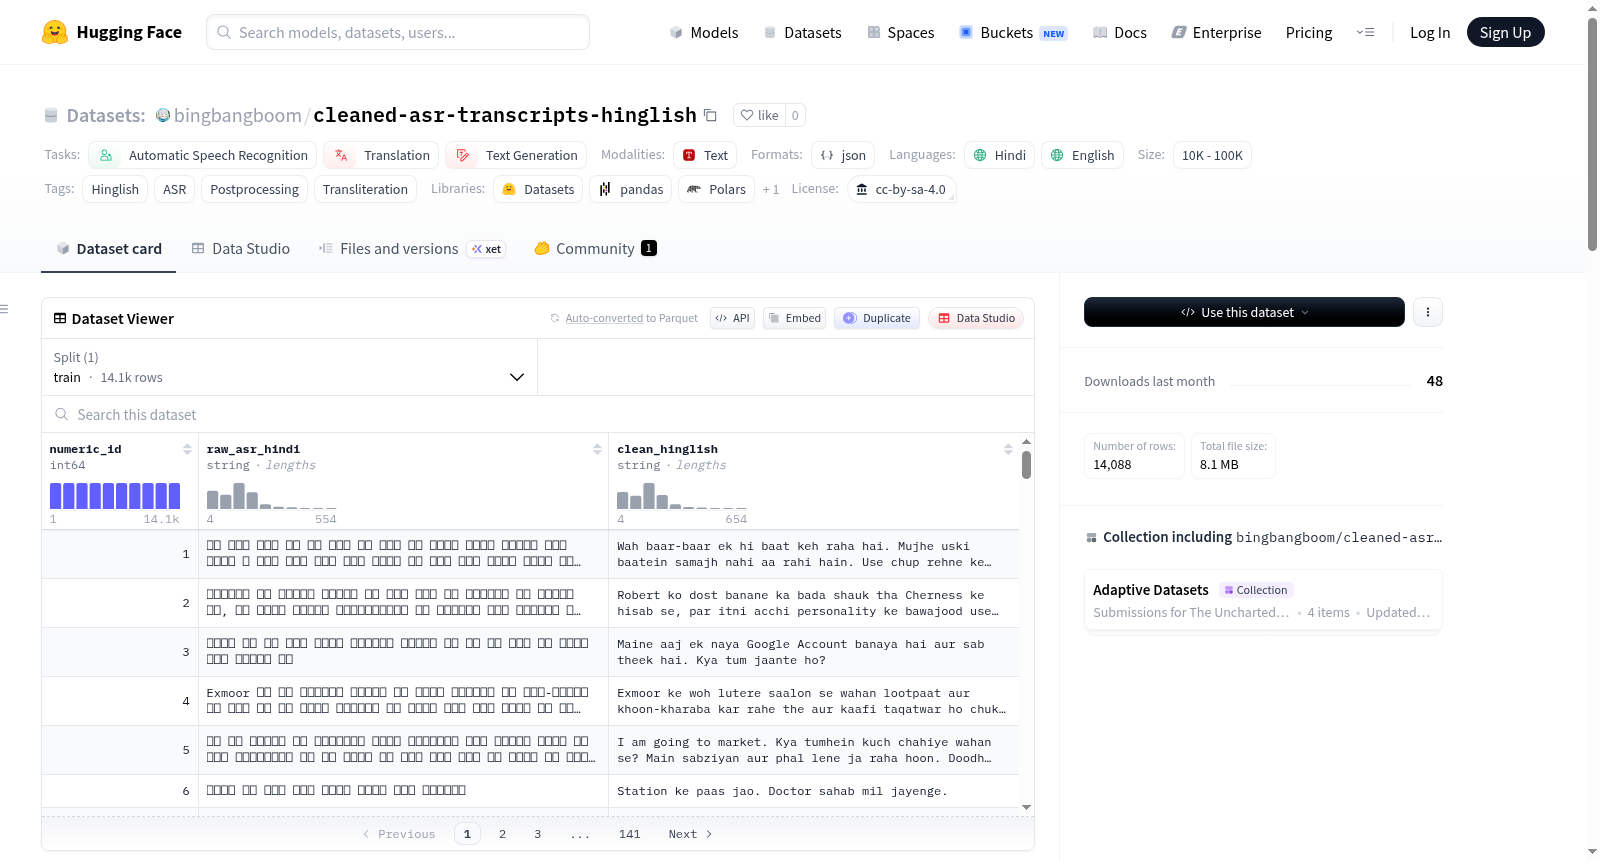
`bingbangboom/cleaned-asr-transcripts-hinglish` 是一个平行语料库,包含14k+对原始-合成印地语ASR(自动语音识别)转录及其干净、正确标点和转写的印地英语(罗马化印地语)对应文本。该数据集专门设计用于ASR后处理、转写模型和微调大型语言模型(LLMs)以理解和生成高质量的、会话式的印地英语。印地英语是印地语和英语的混合语言,是南亚数亿人在互联网和日常交流中的主要语言。数据集还包含了172种不同的ASR错误类型,覆盖了语音、拼写、分段、同音词、形态句法、不流畅和会话、代码转换、格式和标点、方言和语域以及模型幻觉等多个类别。每个实例都是一个包含三个字段的JSON对象:numeric_id、raw_asr_hindi和clean_hinglish。
`bingbangboom/cleaned-asr-transcripts-hinglish` is a parallel corpus containing **14k+** pairs of raw-synthetic Hindi ASR (Automatic Speech Recognition) transcripts mapped to their clean, properly punctuated, and transliterated Hinglish (Romanized Hindi) counterparts. This dataset is specifically designed for ASR post-processing, transliteration models, and fine-tuning Large Language Models (LLMs) to understand and generate high-quality, conversational Hinglish. Hinglish (a portmanteau of Hindi and English) is the dominant conversational language on the internet and in daily communication for hundreds of millions of people in South Asia. The dataset also includes **172 distinct ASR error types** mapped across several major linguistic, orthographic, and formatting categories. Each instance in the dataset is formatted as a JSON object with three fields: `numeric_id`, `raw_asr_hindi`, and `clean_hinglish`.