jilijeanlouis/babel-lid
收藏资源简介:
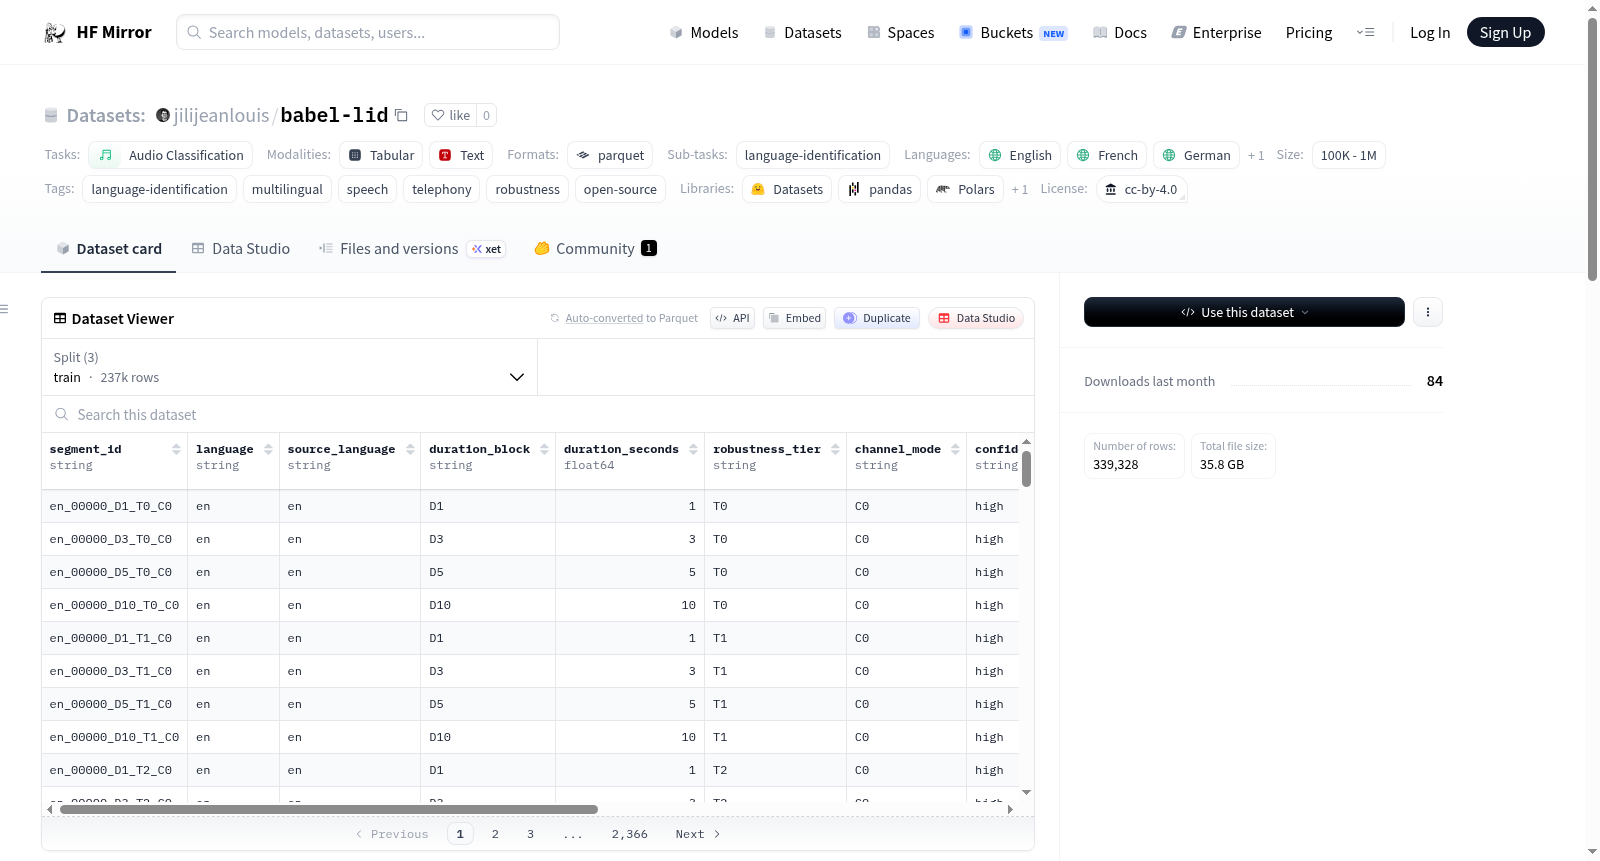
--- language: - en - fr - de - es license: cc-by-4.0 task_categories: - audio-classification task_ids: - language-identification pretty_name: Babel-LID Pilot size_categories: - 100K<n<1M tags: - language-identification - multilingual - speech - telephony - robustness - open-source dataset_info: features: - name: segment_id dtype: string - name: language dtype: string - name: source_language dtype: string - name: duration_block dtype: string - name: duration_seconds dtype: float64 - name: robustness_tier dtype: string - name: channel_mode dtype: string - name: confidence dtype: string - name: source_dataset dtype: string - name: source_id dtype: string - name: audio_path dtype: string - name: start_sample dtype: int64 - name: end_sample dtype: int64 splits: - name: train num_examples: 236544 - name: validation num_examples: 51936 - name: test num_examples: 50848 configs: - config_name: default data_files: - split: train path: data/train-*.parquet - split: validation path: data/validation-*.parquet - split: test path: data/test-*.parquet --- # Babel-LID (Pilot — Metadata Only) **Open-source multi-duration language identification dataset with acoustic robustness tiers.** Pilot release: 4 languages (en, fr, de, es), 339,328 metadata rows. Real pipeline applied end-to-end on Modal. > **Note**: This release contains only the metadata (parquets). The 84,816 augmented WAV files (4 tiers × 2 channels × ~10K source files) are stored on the Modal Volume `babel-lid-v2` and will be added in a subsequent release once the upload pipeline is optimized. ## Stats | Metric | Value | |--------|-------| | Languages | 4 (en, fr, de, es) | | Source audios | 10,825 (LibriSpeech + MLS) | | Verified annotations | 10,604 | | Augmented WAV files | 84,816 (stored on Modal) | | Metadata rows | 339,328 | | Train / Val / Test | 236,544 / 51,936 / 50,848 | ## Real Pipeline (all on Modal) 1. **Stage 1** — Download real speech from LibriSpeech (en) + MLS (fr, de, es) 2. **Stage 2** — Whisper large-v3 transcription verification (A10G GPU) 3. **Stage 3** — 3-model LID ensemble: Whisper + ECAPA-TDNN + MMS-LID-256 (A100 GPU) - 92% high-confidence (3/3 unanimous) - 5.6% medium-confidence (2/3) - 2.2% rejected 4. **Stage 3b** — Linguistic cross-verification via Whisper ASR confidence 5. **Stage 4** — Acoustic augmentation: 4 tiers × 2 channels = 8 variants per source 6. **Stage 5** — Duration block metadata: D1/D3/D5/D10 ## Augmentation Tiers | Tier | Augmentation | Details | |------|-------------|---------| | T0 | Clean | Original audio, 16kHz mono | | T1 | Additive noise | White noise at SNR 5–15 dB | | T2 | Reverb | Synthetic RIR, RT60 0.3–0.8s | | T3 | Multi-distortion | Reverb + noise SNR 0–10 dB | | C0 | Wideband | Full 16kHz bandwidth | | C1 | PSTN telephony | 300–3400 Hz bandpass → 8kHz → μ-law G.711 → 50Hz hum → 16kHz | ## License CC-BY 4.0