LombardoGraphia
收藏资源简介:
LombardoGraphia是由马萨里克大学构建的首个多正字法伦巴第语标注语料库,包含来自维基百科的11,186条文本样本,涵盖9种正字法变体。该数据集经过严格清洗和标注,包含训练集、验证集和测试集划分,并附有正字法系统与地理分布的元数据。数据采集过程涉及对原始维基内容的过滤与标准化处理,旨在解决低资源语言伦巴第语因缺乏统一书写标准导致的NLP资源开发难题,为语言识别、正字法归一化等任务提供基础设施。
LombardoGraphia is the first multi-orthographic annotated corpus of the Lombard language developed by Masaryk University. It contains 11,186 text samples sourced from Wikipedia, encompassing 9 orthographic variants. The corpus has undergone rigorous cleaning and annotation, with predefined splits for training, validation, and testing sets, accompanied by metadata regarding orthographic systems and their geographical distributions. The data collection process entails filtering and standardization of raw Wikipedia content. It is designed to address the challenges in developing NLP resources for the low-resource Lombard language caused by the lack of a unified writing standard, providing infrastructure for tasks such as language identification and orthographic normalization.
数据集概述
数据集基本信息
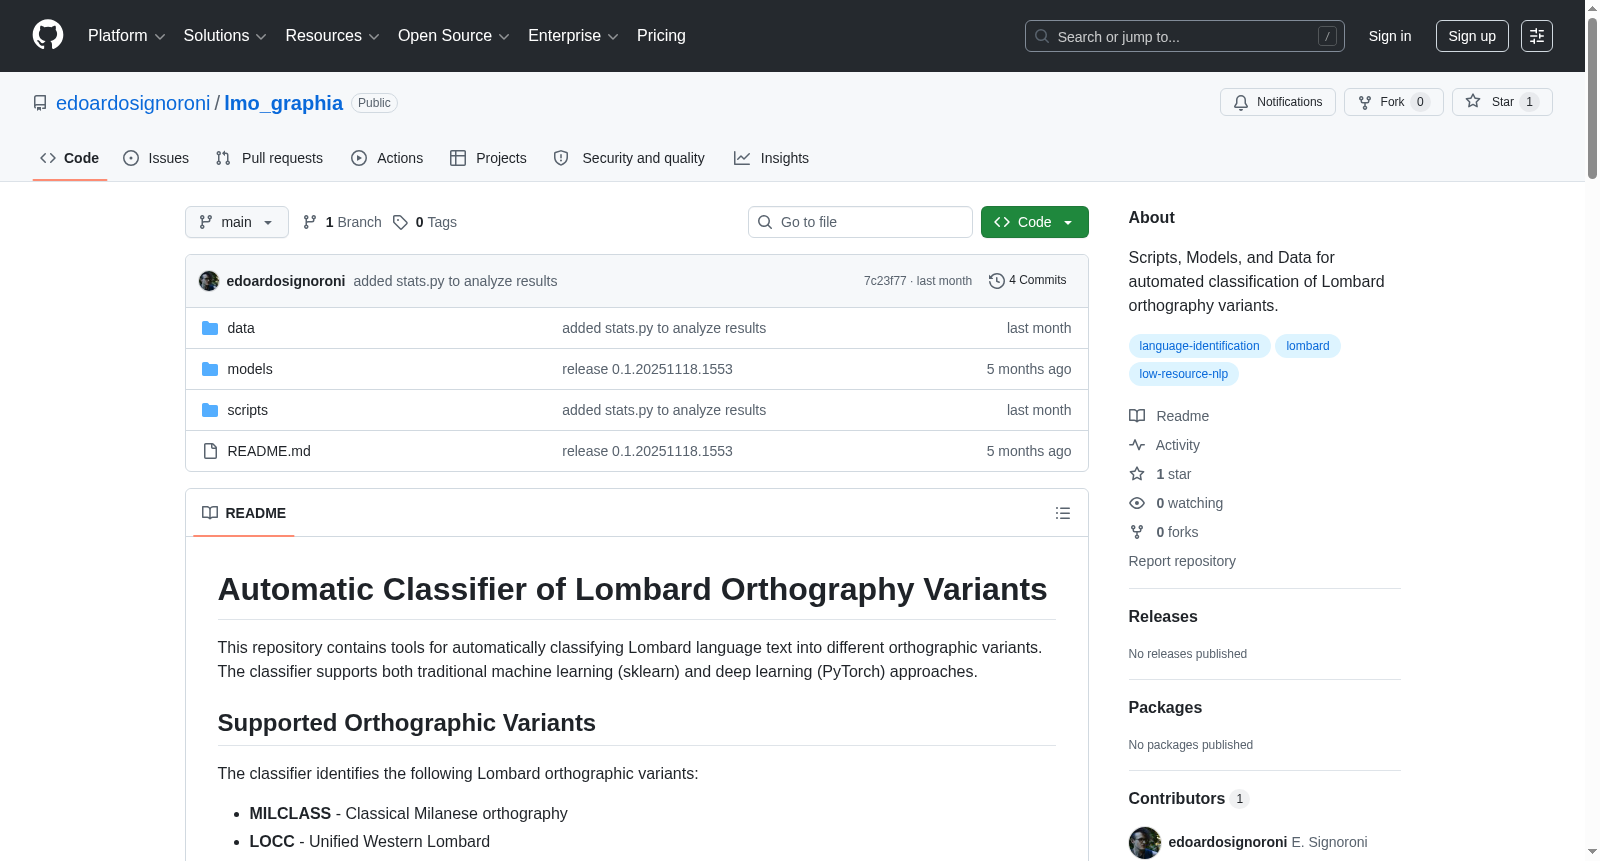
- 数据集名称: Automatic Classifier of Lombard Orthography Variants
- 数据集地址: https://github.com/edoardosignoroni/lmo_graphia
- 主要用途: 自动将伦巴第语文本分类为不同的正字法变体。
- 支持方法: 支持传统机器学习(sklearn)和深度学习(PyTorch)方法。
支持的正字法变体
该分类器识别以下伦巴第语正字法变体:
- MILCLASS - 古典米兰正字法
- LOCC - 统一西伦巴第语
- LORUNIF - 统一东伦巴第语
- SL - Scriver Lombard
- NOL - 新伦巴第正字法
- CRES - 克雷莫纳正字法
- BREMOD - 现代布雷西亚正字法
- BERGDUC - 贝加莫正字法
数据集结构与统计
存储库结构
ortho_classifier/ ├── README.md ├── data/ │ ├── gold/ # 标注训练数据 │ │ ├── train.jsonl # 8,950 个训练样本 │ │ ├── valid.jsonl # 1,118 个验证样本 │ │ └── test.jsonl # 1,118 个测试样本 │ └── no-tag/ # 自动标注数据 │ └── no-tag.jsonl # 94,520 个样本 ├── models/ # 预训练模型 └── scripts/ ├── classifiers.py # 核心分类器类定义 ├── train_classifier.py # 训练脚本 ├── apply_classifier.py # 分类脚本 └── usage.md # 参考文档
黄金标准数据集统计
数据划分
| 划分 | 样本数 |
|---|---|
| 训练集 | 8,950 |
| 验证集 | 1,118 |
| 测试集 | 1,118 |
| 总计 | 11,186 |
训练集标签分布
| 变体 | 数量 | 百分比 |
|---|---|---|
| MILCLASS | 3,606 | 40.3% |
| LOCC | 2,907 | 32.5% |
| LORUNIF | 1,901 | 21.2% |
| SL | 174 | 1.9% |
| NOL | 109 | 1.2% |
| CRES | 98 | 1.1% |
| BREMOD | 94 | 1.1% |
| BERGDUC | 59 | 0.7% |
| LSI | 2 | 0.0% |
| 总计 | 8,950 | 100% |
模型性能
性能指标以准确率(%)表示,涵盖了多种模型和特征组合。
最佳与最差性能摘要
| 指标 | MILCLASS | LOCC | LORUNIF | SL | NOL | CRES | BREMOD | BERGDUC | Overall | Avg Class |
|---|---|---|---|---|---|---|---|---|---|---|
| 最佳准确率 | 98.88 | 96.58 | 99.13 | 100.0 | 75.00 | 100.0 | 69.23 | 83.33 | 96.06 | 85.78 |
| 最差准确率 | 83.86 | 85.00 | 84.28 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 | 87.20 | 35.42 |
| 准确率范围 | 15.02 | 11.58 | 14.85 | 100.0 | 75.00 | 100.0 | 69.23 | 83.33 | 8.86 | 50.36 |
引用
如果使用此分类器,请引用:
Edoardo Signoroni and Pavel Rýchly, LombardoGraphia: Automatic Classification of Lombard Orthography Variants, Upcoming
许可信息
- 数据集许可: CC-BY-SA 4.0
- 软件许可: GPL-3.0
致谢
本工作得到了捷克共和国教育、青年和体育部的支持,项目编号:LM2023062 LINDAT/CLARIAH-CZ。 感谢伦巴第语维基百科的志愿者和贡献者创建数据并提供有益的讨论和信息。