UBC-NLP/NADI2026_subtask2_MixedASR
收藏资源简介:
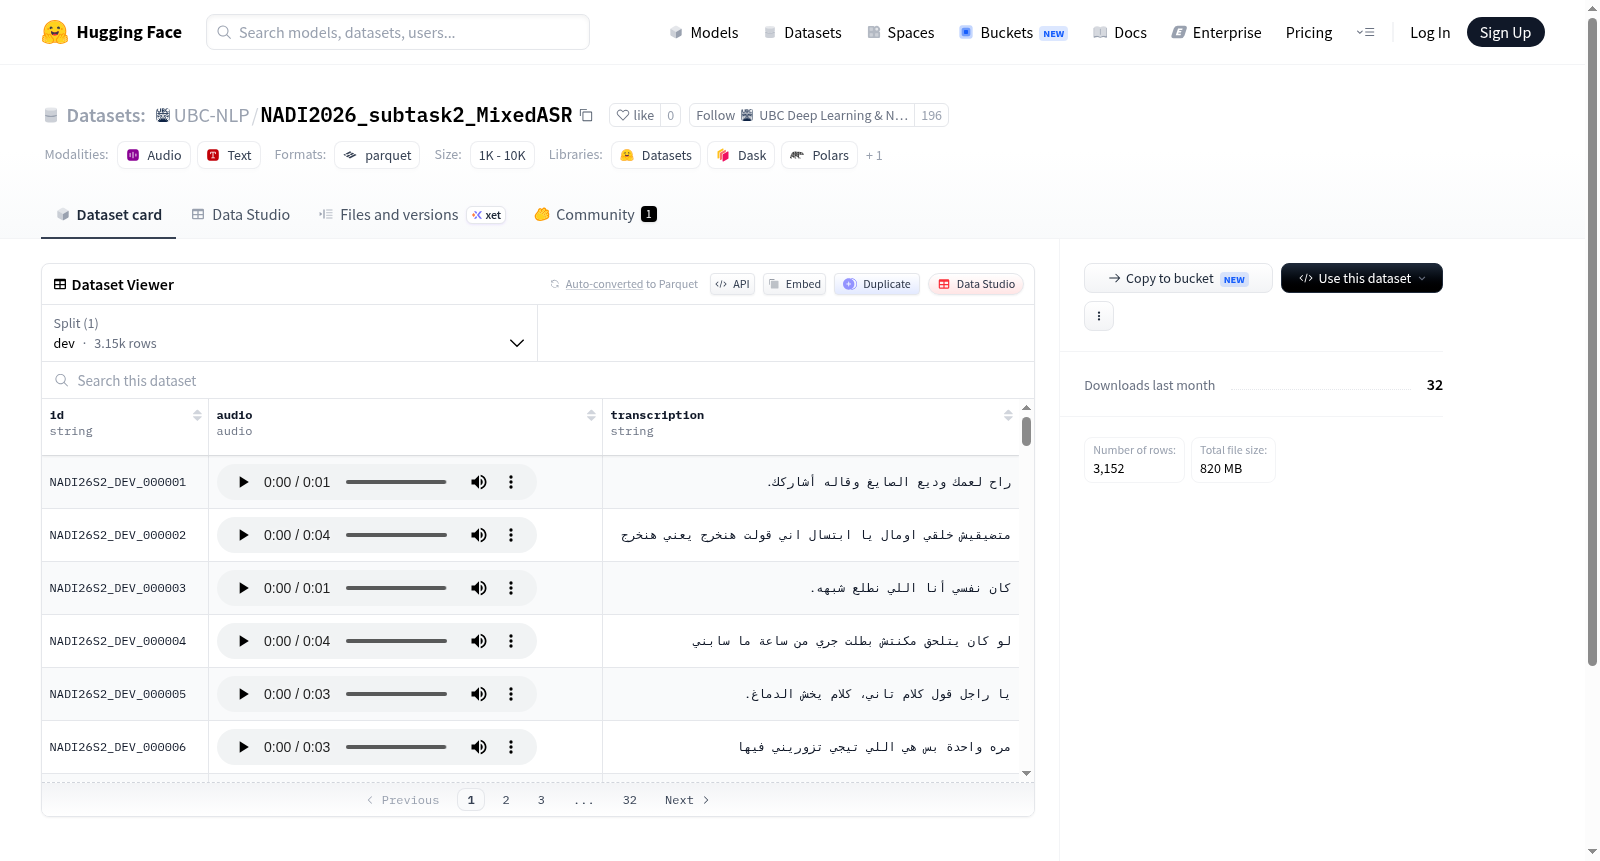
该数据集是NADI 2026竞赛的第二个子任务(MixedASR)的数据集,专注于混合自动语音识别任务。它包含音频文件及其对应的转录文本,音频采样率为16000 Hz。数据集分为开发集(dev),共有3152个示例,用于模型训练和评估。数据特征包括id(标识符)、audio(音频数据)和transcription(文本转录)。该数据集旨在支持语音识别技术的研究和应用,特别是在多语言或混合语音场景下。
This dataset is for the second subtask (MixedASR) of the NADI 2026 competition, focusing on mixed automatic speech recognition tasks. It includes audio files and their corresponding transcriptions, with an audio sampling rate of 16000 Hz. The dataset is split into a development set (dev), containing 3152 examples, for model training and evaluation. Features include id (identifier), audio (audio data), and transcription (text transcription). It is designed to support research and applications in speech recognition, particularly in multilingual or mixed speech scenarios.