FDM-gcodes
收藏资源简介:
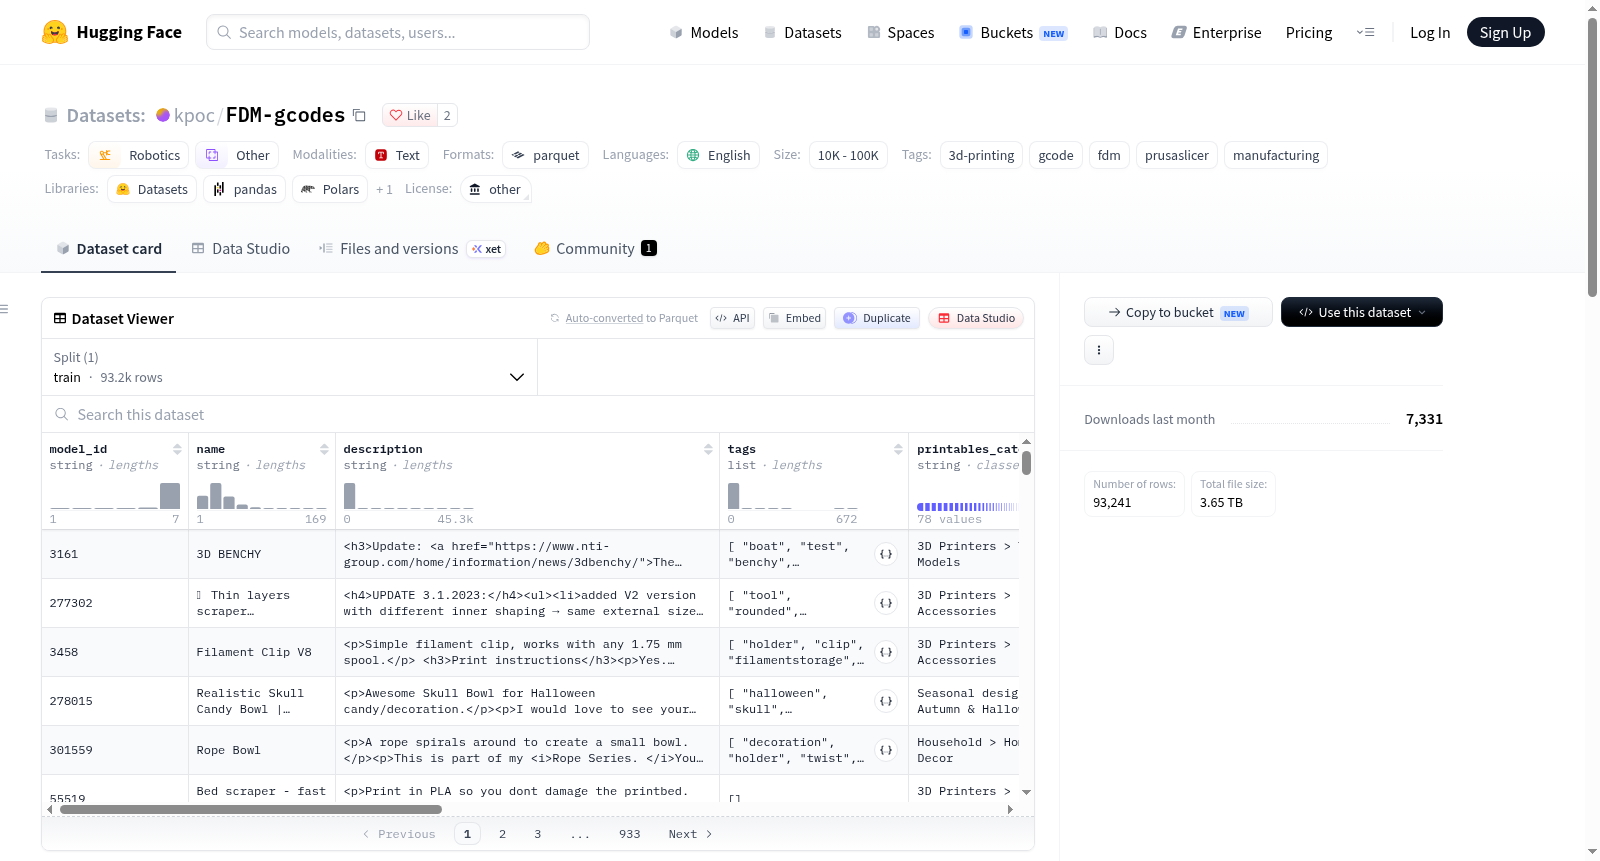
FDM G-Codes 数据集是一个大规模、高多样性的熔融沉积成型(FDM)G-code 数据集,由 kpoc/3d-models 数据集(源自 Printables)中的 STL 文件经 PrusaSlicer 迭代切片生成。每个原始 STL 文件默认生成 10 个变体,每个变体使用高度随机化的配置参数,包括打印机配置文件(涵盖 Generic FDM、Prusa、Creality、Voron、Anycubic、Bambu、Artillery 等)、喷嘴直径(0.25mm-0.8mm)、耗材类型(PLA、PETG、ABS、ASA、TPU)、层高、填充密度(0-100%)、填充图案、速度、支撑结构等。该数据集专为训练原始 3D 打印制造指令(G-code)的机器学习模型而设计,可用于 G-code 生成、打印失败预测、刀具路径语义分析、与打印机无关的切片分类等任务。数据采用 WebDataset 风格的 .tar 分片格式(每个约 8GB),支持高效流式读取。根目录包含一个 Parquet 元数据文件(metadata.parquet),每行对应一个原始 3D 模型,包含模型 ID、名称、描述、标签、类别、许可证、来源以及嵌套的 gcode 数组(每个变体包括源 STL 路径、G-code 路径、设置路径、打印机配置文件、喷嘴直径、耗材类型、层高、填充密度、是否启用支撑、随机种子)。tar 分片中按 model_id 组织文件:images/*.jpg(预览图像)、gcode/*.gcode(切片后的 G-code 文件)、gcode/*.settings.json(随机化设置)。G-code 文件继承其父 3D 模型的许可证,具体许可证信息在元数据的 license 列中。建议使用 WebDataset 或 Hugging Face 流式 API 进行训练。
The FDM G-Codes dataset is a large-scale, high-diversity Fused Deposition Modeling (FDM) G-code dataset, generated by iteratively slicing STL files from the kpoc/3d-models dataset (derived from Printables) using PrusaSlicer. Each original STL file is processed to produce 10 variants by default, each with highly randomized configuration parameters, including printer profiles (covering Generic FDM, Prusa, Creality, Voron, Anycubic, Bambu, Artillery, etc.), nozzle diameter (0.25mm-0.8mm), filament type (PLA, PETG, ABS, ASA, TPU), layer height, infill density (0-100%), infill pattern, speed, support structure, etc. This dataset is specifically designed for training machine learning models on raw 3D printing manufacturing instructions (G-code), and can be used for tasks such as G-code generation, print failure prediction, toolpath semantic analysis, and printer-agnostic slice classification. The data is stored in WebDataset-style .tar shard format (each approximately 8GB), supporting efficient streaming reads. The root directory contains a Parquet metadata file (metadata.parquet), where each row corresponds to an original 3D model, including model ID, name, description, tags, category, license, source, and a nested gcode array (each variant includes source STL path, G-code path, settings path, printer profile, nozzle diameter, filament type, layer height, infill density, support enabled flag, random seed). Within the tar shards, files are organized by model_id: images/*.jpg (preview images), gcode/*.gcode (sliced G-code files), gcode/*.settings.json (randomized settings). G-code files inherit the license of their parent 3D model, with specific license information in the license column of the metadata. It is recommended to use WebDataset or Hugging Face streaming API for training.
数据集概述
FDM G-Codes Dataset 是一个大规模、高度多样化的熔融沉积建模(FDM)G代码数据集,由 kpoc/3d-models 数据集(源自 Printables)生成,专门用于训练机器学习模型处理原始 3D 打印制造指令(G代码)。该数据集适用于 G代码生成、打印失败预测、刀具路径语义分析以及与打印机无关的切片分类等任务。
数据集生成方式
- 对源数据集中的每个原始 STL 文件使用 PrusaSlicer 进行迭代切片,生成了多个变体(每个 STL 默认为 10 个)。
- 每个变体都使用高度随机化的配置配置文件,对以下参数进行随机化处理:
- 打印机配置:以通用 FDM 设置为主,同时涵盖 Prusa、Creality (Ender)、Voron、Anycubic、Bambu 和 Artillery 的混合几何形状/打印床尺寸。
- 喷嘴直径:范围从 0.25mm 到 0.8mm。
- 耗材类型:为 PLA、PETG、ABS、ASA 和 TPU 提供合理的温度和床层配置文件。
- 打印设置:随机化层高、外围层数、实心层数、填充密度(0-100%)、填充图案(网格、螺旋、蜂窝、立方体等)、速度和支撑结构。
- 这种随机化过程迫使下游机器学习模型学习 G代码的底层语义,而不是过度拟合特定打印机的标准预设。
数据结构
数据集使用 WebDataset 风格的 .tar 分片(通常每个约 8GB)进行格式化,以支持数百万文件的高效流式传输。
1. Parquet 元数据 (metadata.parquet)
根元数据文件包含每个原始 3D 模型的一行数据。它保留了所有原始的 Printables 元数据(名称、描述、标签、类别、许可证),并包含一个嵌套的 gcode 数组,详细描述了该模型的每个切片变体:
json { "source_stl_path": "...", "gcode_path": "...", "settings_path": "...", "printer_profile": "generic_fdm_0.4", "nozzle_diameter_mm": 0.4, "filament_type": "PETG", "layer_height_mm": 0.213, "fill_density_pct": 15, "supports_enabled": true, "seed": 12345678 }
2. Tar 分片 (data/gdata_*.tar)
在 tar 归档文件中,文件按原始 model_id 分组:
<model_id>/images/*.jpg:来自 Printables 的原始预览图像。<model_id>/gcode/*.gcode:包含原始刀具路径的完整切片 G代码文件。<model_id>/gcode/*.settings.json:一个人类可读的 JSON 文件,存储用于生成相应 G代码的随机化设置。
使用建议
由于数据集规模巨大,在训练前完全下载可能对大多数环境不现实。强烈建议使用 WebDataset 或 Hugging Face 的流式 API 在训练过程中动态流式传输 tar 文件。
许可证与归属
.gcode 文件继承其父级 3D 模型的许可证。请参阅元数据中的 license 列,了解每个模型关联的特定 Creative Commons / 开源许可证。所有模型最初均来源于 Printables。