DeepPavlov/clarqa_ru
收藏资源简介:
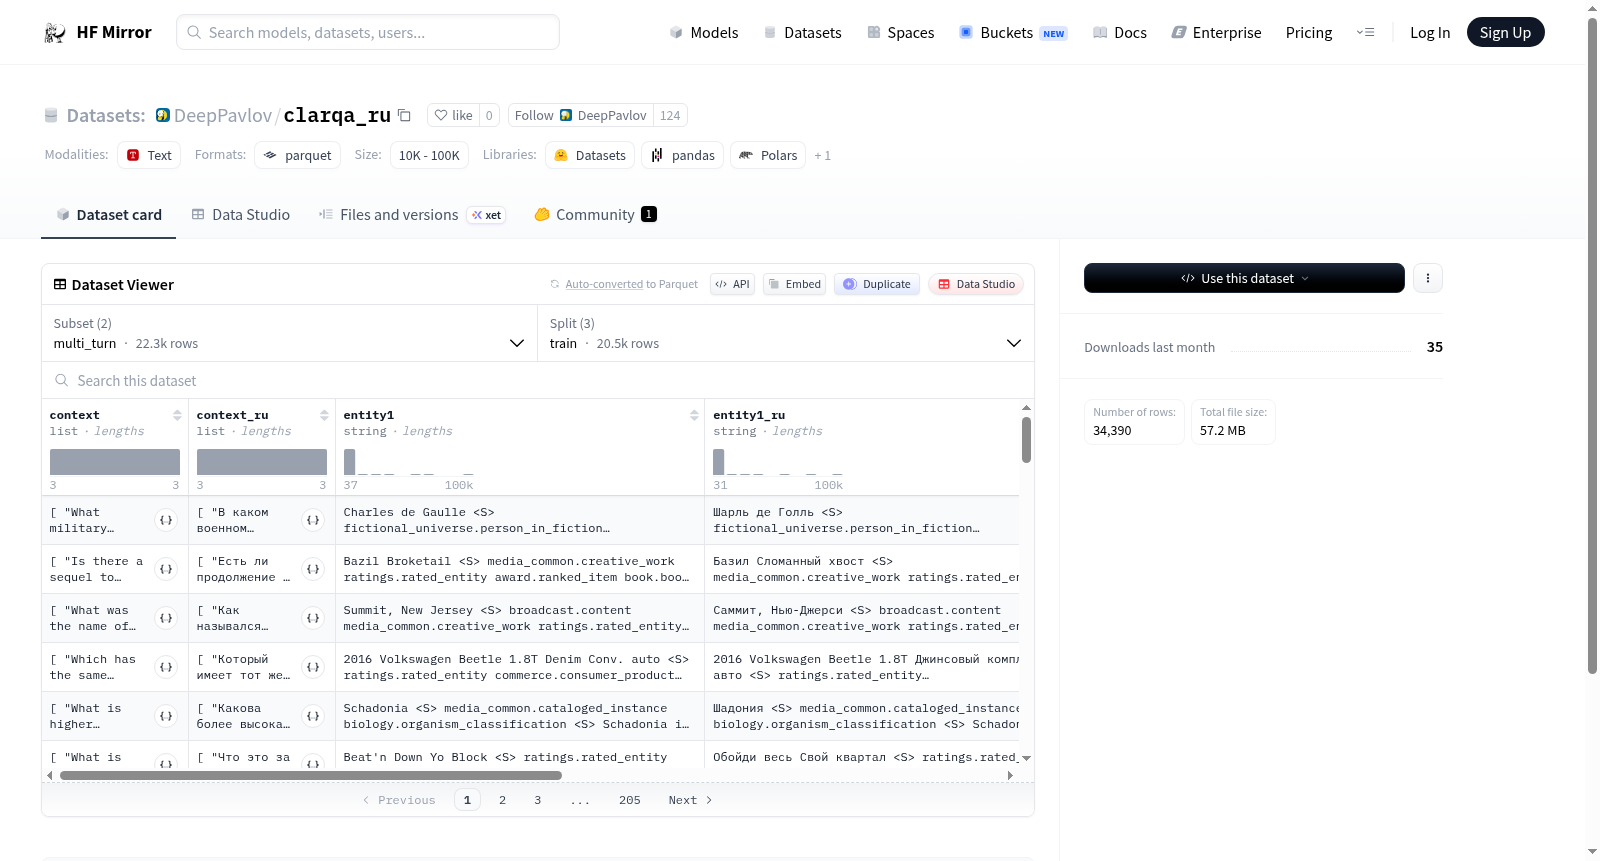
这是一个多语言数据集,包含英语和俄语文本,主要用于对话或文本分类任务,涉及实体关系分析。数据集提供两种配置:multi_turn(多轮对话)和single_turn(单轮对话)。在multi_turn配置中,context字段为字符串序列,表示对话上下文;在single_turn配置中,context字段为单个字符串。每个配置都包含实体字段(entity1和entity2)及其俄语版本(entity1_ru和entity2_ru),以及标签字段(label)用于分类或标注。数据集分为训练集、开发集和测试集,具体规模如下:multi_turn配置有20,462个训练样本、973个开发样本和828个测试样本;single_turn配置有10,099个训练样本、853个开发样本和1,175个测试样本。该数据集可能适用于自然语言处理任务,如对话系统、实体识别或关系抽取。
This is a multilingual dataset containing English and Russian texts, primarily designed for dialogue or text classification tasks involving entity relationship analysis. The dataset offers two configurations: multi_turn (for multi-turn dialogues) and single_turn (for single-turn dialogues). In the multi_turn configuration, the context field is a sequence of strings representing dialogue context, while in the single_turn configuration, it is a single string. Each configuration includes entity fields (entity1 and entity2) and their Russian versions (entity1_ru and entity2_ru), along with a label field for classification or annotation. The dataset is divided into training, development, and test sets, with specific scales: the multi_turn configuration has 20,462 training samples, 973 development samples, and 828 test samples; the single_turn configuration has 10,099 training samples, 853 development samples, and 1,175 test samples. This dataset is likely suitable for natural language processing tasks such as dialogue systems, entity recognition, or relation extraction.