Complete_Data_Source_100K_HOURS
收藏资源简介:
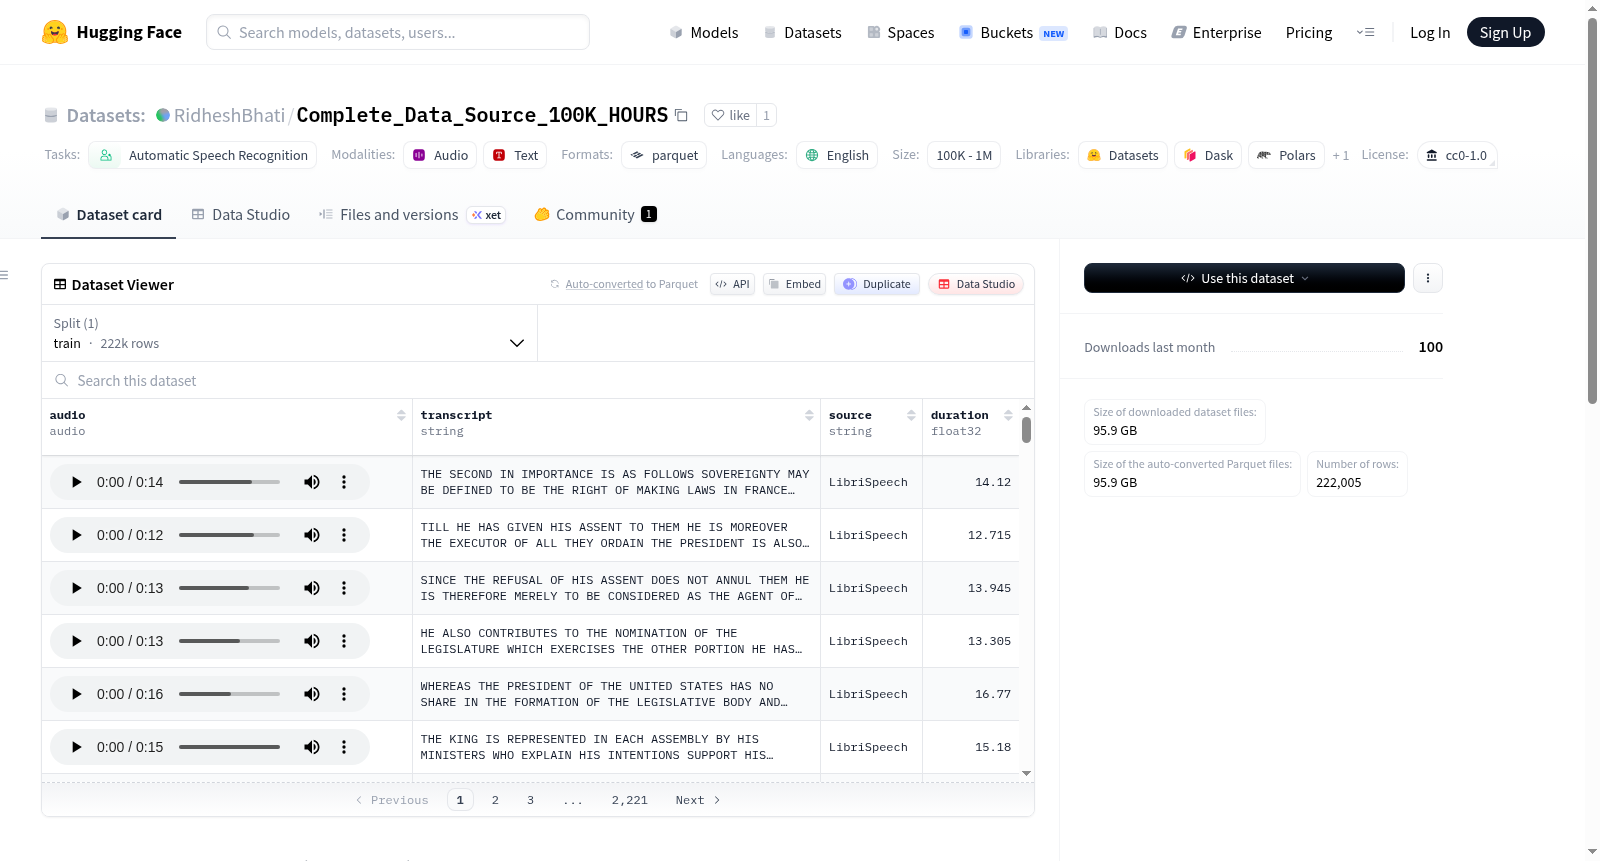
Complete English ASR Dataset (100K Hours) 是一个大规模英语自动语音识别(ASR)数据集,由多个公共来源的数据编译而成,经过去重和统一处理,整合为一个单一的资源库。数据集采用 cc0-1.0 许可证,适用于自动语音识别任务,语言为英语,规模在10万到100万小时之间。数据集包含以下字段:音频(WAV 16 kHz格式,可在数据集查看器中播放)、文本转录(字符串格式)、原始数据集名称(字符串格式)以及音频时长(以秒为单位的浮点数)。数据来源包括 LibriSpeech、MLS_japanese_asr、Peoples_Speech、MLS_English_parler、YouTube_English、Ghana_English_ASR、LoquaciousSet 和 England_Phoneme_Dataset 等多个公开数据集。
Complete English ASR Dataset (100K Hours) is a large-scale English automatic speech recognition (ASR) dataset compiled from multiple public data sources, deduplicated and uniformly processed into a single unified repository. Released under the CC0-1.0 license, this dataset is intended for automatic speech recognition tasks, supports English language, and has a size ranging from 100,000 to 1,000,000 hours. The dataset includes the following fields: Audio (WAV format at 16 kHz, playable in the dataset viewer), Text Transcription (string format), Original Dataset Name (string format), and Audio Duration (floating-point number in seconds). Its data sources include multiple public datasets such as LibriSpeech, MLS_japanese_asr, Peoples_Speech, MLS_English_parler, YouTube_English, Ghana_English_ASR, LoquaciousSet, and England_Phoneme_Dataset.
Complete English ASR Dataset (100K Hours) 数据集概述
数据集基本信息
- 数据集名称:Complete English ASR Dataset (100K Hours)
- 许可证:cc0-1.0
- 主要任务类别:自动语音识别 (Automatic-Speech-Recognition)
- 语言:英语 (en)
- 数据规模:100K < n < 1M (小时数)
- 配置名称:default
数据内容与结构
- 数据格式:Parquet 文件
- 数据分割:训练集 (train)
- 特征列:
audio:音频 (Audio, WAV 16 kHz),可在数据集查看器中播放的波形。transcript:字符串 (string),文本转录。source:字符串 (string),原始数据集名称。duration:浮点数 (float32),音频时长(秒)。
数据来源
该数据集是从多个公共来源编译而成的大型英语ASR数据集,经过去重并统一到一个存储库中。具体来源包括:
- LibriSpeech
- MLS_japanese_asr
- Peoples_Speech
- MLS_English_parler
- YouTube_English
- Ghana_English_ASR
- LoquaciousSet
- England_Phoneme_Dataset