Shaer-AI/shaer-eval-raw-fanar-diwan-prefix-300-split
收藏资源简介:
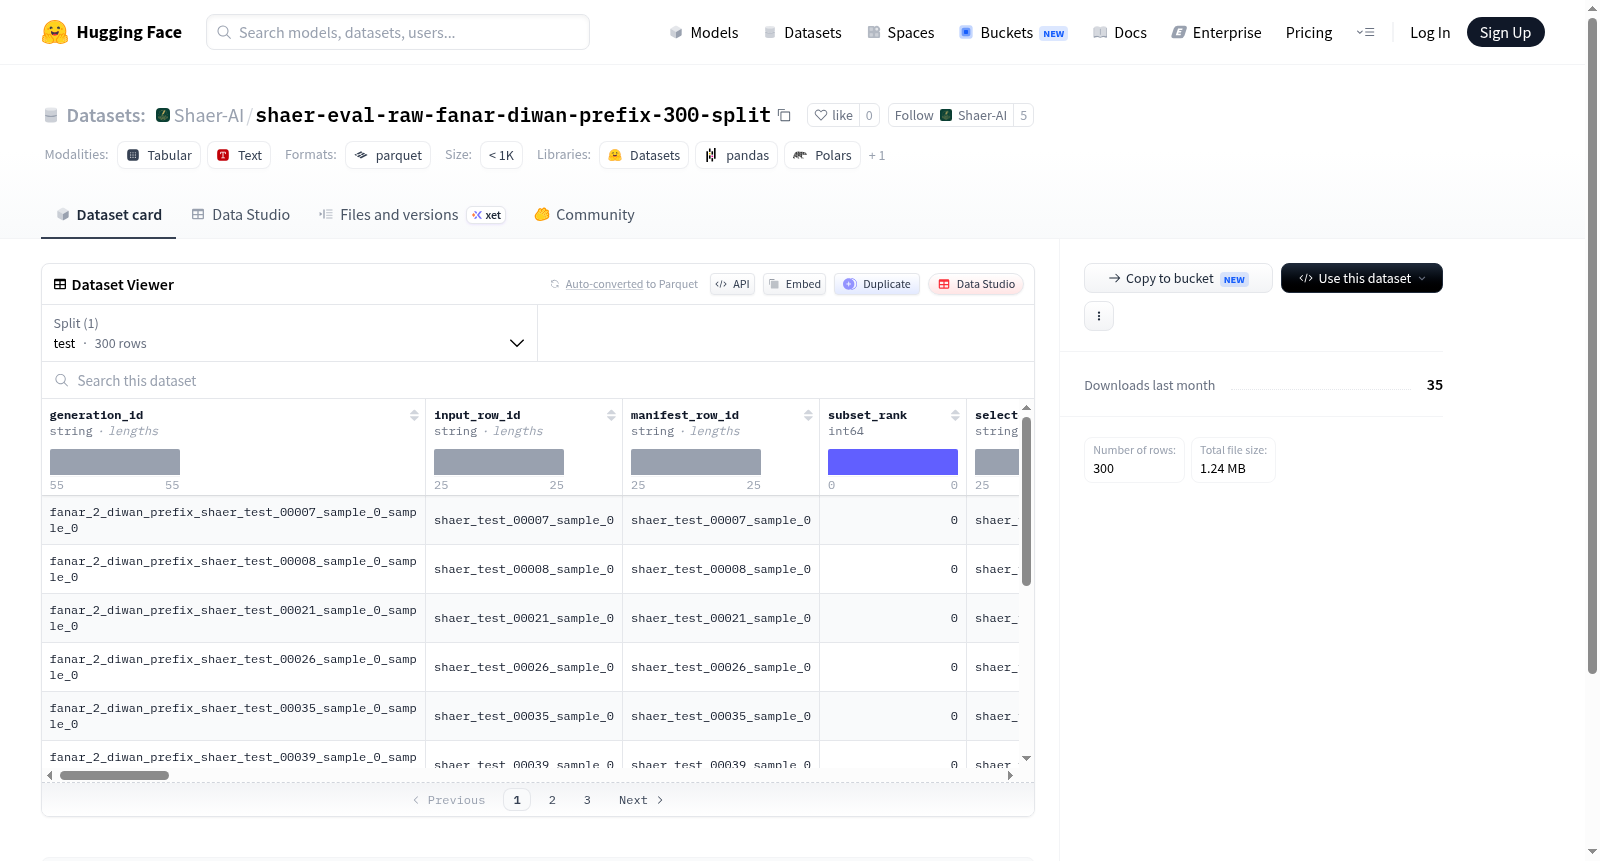
该数据集是一个用于诗歌生成评估的数据集,包含多个模型的生成文本及其评估指标。数据集特征包括生成ID、模型信息(如模型名称、模型角色)、诗歌相关属性(如基础韵律、形式、韵律标签)、请求参数(如请求的字节数、行数)、参考文本、生成的文本、健康状态、解码配置、创建时间、以及多个评估分数(如计数依从性、韵律评估状态、流畅性分数、连贯性分数、诗意性分数、描述依从性分数)。数据集旨在评估不同模型在生成诗歌时的表现,重点关注文本的韵律依从性、诗意性和整体质量。数据分割为测试集,包含300个示例。
This dataset is designed for evaluating poetry generation, containing generated texts from multiple models along with their evaluation metrics. The features include generation ID, model information (such as model name, model role), poetry-related attributes (like base meter, form, meter label), request parameters (such as requested bytes, number of lines), reference text, generated text, health status, decode configuration, creation time, and various evaluation scores (e.g., count adherence, meter evaluation status, fluency score, coherence score, poeticness score, description adherence score). The dataset aims to assess the performance of different models in generating poetry, with a focus on meter adherence, poeticness, and overall text quality. The data is split into a test set containing 300 examples.