ByteDance-Seed/Multi-SWE-bench
收藏资源简介:
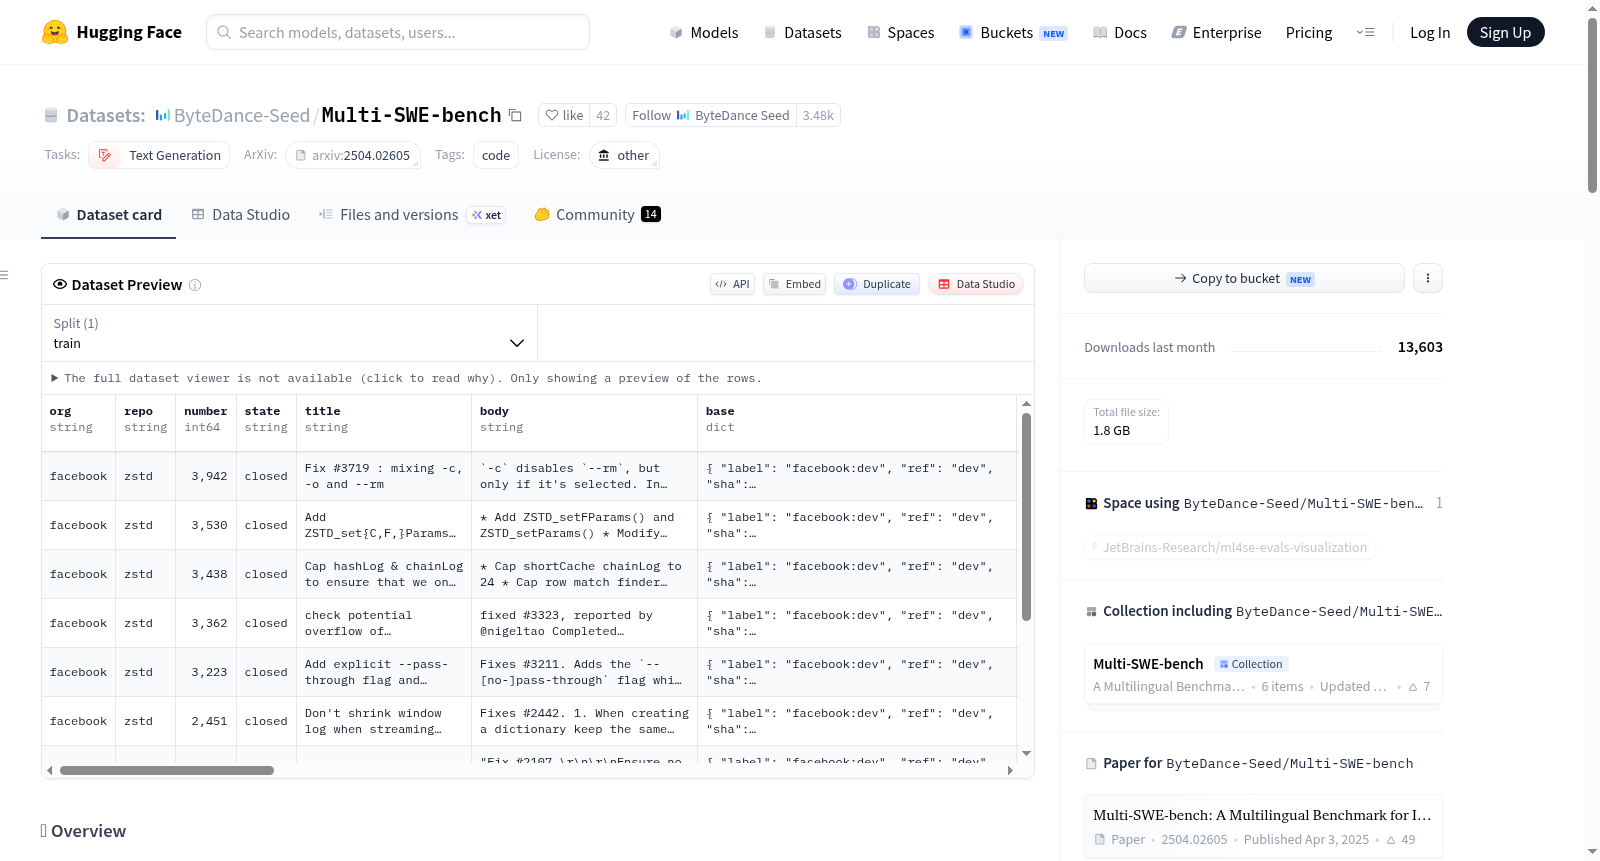
--- license: other task_categories: - text-generation tags: - code --- ## 👋 Overview This repository contains the Multi-SWE-bench dataset, introduced in [Multi-SWE-bench: A Multilingual Benchmark for Issue Resolving](https://huggingface.co/papers/2504.02605), to address the lack of multilingual benchmarks for evaluating LLMs in real-world code issue resolution. Unlike existing Python-centric benchmarks (e.g., SWE-bench), this framework spans 7 languages (Java, TypeScript, JavaScript, Go, Rust, C, and C++) with 1,632 high-quality instances, curated from 2,456 candidates by 68 expert annotators for reliability. The leaderboard can be found at: https://multi-swe-bench.github.io ## ⚙️ Usage ```bash # Make sure git-lfs is installed (https://git-lfs.com) git lfs install git clone https://huggingface.co/datasets/ByteDance-Seed/Multi-SWE-bench ``` ## 🧩 Data Instances Structure An example of a Multi-SWE-bench datum is as follows: ``` org: (str) - Organization name identifier from Github. repo: (str) - Repository name identifier from Github. number: (int) - The PR number. state: (str) - The PR state. title: (str) - The PR title. body: (str) - The PR body. base: (dict) - The target branch information of the PR resolved_issues: (list) - A json list of strings that represent issues that resolved by PR application. fix_patch: (str) - A fix-file patch that was contributed by the solution PR. test_patch: (str) - A test-file patch that was contributed by the solution PR. fixed_tests: (dict) - A json dict of strings that represent tests that should be fixed after the PR application. p2p_tests: (dict) - The tests that should pass before and after the PR application. f2p_tests: (dict) - The tests resolved by the PR and tied to the issue resolution. s2p_tests: (dict) - The tests that should skip before the PR application, and pass after the PR application. n2p_tests: (dict) - The tests that did not exist before the PR application and tests that should be passed after the PR application. run_result: (dict) - Overall run results, including number of tests passed, number of tests failed, etc. test_patch_result: (dict) - The result after the test patch was applied. fix_patch_result: (dict) - The result after all the patches were applied. instance_id: (str) - A formatted instance identifier, usually as org__repo_PR-number. ``` ## 📚 Citation ``` @misc{zan2025multiswebench, title={Multi-SWE-bench: A Multilingual Benchmark for Issue Resolving}, author={Daoguang Zan and Zhirong Huang and Wei Liu and Hanwu Chen and Linhao Zhang and Shulin Xin and Lu Chen and Qi Liu and Xiaojian Zhong and Aoyan Li and Siyao Liu and Yongsheng Xiao and Liangqiang Chen and Yuyu Zhang and Jing Su and Tianyu Liu and Rui Long and Kai Shen and Liang Xiang}, year={2025}, eprint={2504.02605}, archivePrefix={arXiv}, primaryClass={cs.SE}, url={https://arxiv.org/abs/2504.02605}, } ``` ## 📜 License The dataset is licensed under CC0, subject to any intellectual property rights in the dataset owned by Bytedance. The data is adapted from the listed open source projects; your use of that data must comply with their respective licenses. | Language | Organization/Repository | Repository Link | Data Link | | :------- | :------------------------------ | :----------------------------------------------------------- | ------------------------------------------------------------ | | C | facebook/zstd | [repo_link](https://github.com/facebook/zstd) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/c/facebook__zstd_dataset.jsonl) | | C | jqlang/jq | [repo_link](https://github.com/jqlang/jq) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/c/jqlang__jq_dataset.jsonl) | | C | ponylang/ponyc | [repo_link](https://github.com/ponylang/ponyc) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/c/ponylang__ponyc_dataset.jsonl) | | C++ | catchorg/Catch2 | [repo_link](https://github.com/catchorg/Catch2) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/cpp/catchorg__Catch2_dataset.jsonl) | | C++ | fmtlib/fmt | [repo_link](https://github.com/fmtlib/fmt) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/cpp/fmtlib__fmt_dataset.jsonl) | | C++ | nlohmann/json | [repo_link](https://github.com/nlohmann/json) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/cpp/nlohmann__json_dataset.jsonl) | | C++ | simdjson/simdjson | [repo_link](https://github.com/simdjson/simdjson) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/cpp/simdjson__simdjson_dataset.jsonl) | | C++ | yhirose/cpp-httplib | [repo_link](https://github.com/yhirose/cpp-httplib) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/cpp/yhirose__cpp-httplib_dataset.jsonl) | | Go | cli/cli | [repo_link](https://github.com/cli/cli) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/go/cli__cli_dataset.jsonl) | | Go | grpc/grpc-go | [repo_link](https://github.com/grpc/grpc-go) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/go/grpc__grpc-go_dataset.jsonl) | | Go | zeromicro/go-zero | [repo_link](https://github.com/zeromicro/go-zero) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/go/zeromicro__go-zero_dataset.jsonl) | | Java | alibaba/fastjson2 | [repo_link](https://github.com/alibaba/fastjson2) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/java/alibaba__fastjson2_dataset.jsonl) | | Java | elastic/logstash | [repo_link](https://github.com/elastic/logstash) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/java/elastic__logstash_dataset.jsonl) | | Java | mockito/mockito | [repo_link](https://github.com/mockito/mockito) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/java/mockito__mockito_dataset.jsonl) | | JS | anuraghazra/github-readme-stats | [repo_link](https://github.com/anuraghazra/github-readme-stats) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/js/anuraghazra__github-readme-stats_dataset.jsonl) | | JS | axios/axios | [repo_link](https://github.com/axios/axios) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/js/axios__axios_dataset.jsonl) | | JS | expressjs/express | [repo_link](https://github.com/expressjs/express) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/js/expressjs__express_dataset.jsonl) | | JS | iamkun/dayjs | [repo_link](https://github.com/iamkun/dayjs) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/js/iamkun__dayjs_dataset.jsonl) | | JS | Kong/insomnia | [repo_link](https://github.com/Kong/insomnia) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/js/Kong__insomnia_dataset.jsonl) | | JS | sveltejs/svelte | [repo_link](https://github.com/sveltejs/svelte) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/js/sveltejs__svelte_dataset.jsonl) | | Rust | BurntSushi/ripgrep | [repo_link](https://github.com/BurntSushi/ripgrep) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/BurntSushi__ripgrep_dataset.jsonl) | | Rust | clap-rs/clap | [repo_link](https://github.com/clap-rs/clap) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/clap-rs__clap_dataset.jsonl) | | Rust | nushell/nushell | [repo_link](https://github.com/nushell/nushell) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/nushell__nushell_dataset.jsonl) | | Rust | serde-rs/serde | [repo_link](https://github.com/serde-rs/serde) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/serde-rs__serde_dataset.jsonl) | | Rust | sharkdp/bat | [repo_link](https://github.com/sharkdp/bat) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/sharkdp__bat_dataset.jsonl) | | Rust | sharkdp/fd | [repo_link](https://github.com/sharkdp/fd) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/sharkdp__fd_dataset.jsonl) | | Rust | rayon-rs/rayon | [repo_link](https://github.com/rayon-rs/rayon) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/rayon-rs__rayon_dataset.jsonl) | | Rust | tokio-rs/bytes | [repo_link](https://github.com/tokio-rs/bytes) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/tokio-rs__bytes_dataset.jsonl) | | Rust | tokio-rs/tokio | [repo_link](https://github.com/tokio-rs/tokio) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/tokio-rs__tokio_dataset.jsonl) | | Rust | tokio-rs/tracing | [repo_link](https://github.com/tokio-rs/tracing) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/rust/tokio-rs__tracing_dataset.jsonl) | | TS | darkreader/darkreader | [repo_link](https://github.com/darkreader/darkreader) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/ts/darkreader__darkreader_dataset.jsonl) | | TS | mui/material-ui | [repo_link](https://github.com/mui/material-ui) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/ts/mui__material-ui_dataset.jsonl) | | TS | vuejs/core | [repo_link](https://github.com/vuejs/core) | [data_link](https://huggingface.co/datasets/bytedance-research/Multi-SWE-Bench/blob/main/ts/vuejs__core_dataset.jsonl) |
Multi-SWE-bench is a multilingual benchmark dataset designed to evaluate the performance of Large Language Models (LLMs) in real-world code issue resolution. The dataset spans across 7 programming languages: Java, TypeScript, JavaScript, Go, Rust, C, and C++, and includes 1,632 high-quality instances curated from 2,456 candidates by 68 expert annotators for reliability.