GEditBench-v2
收藏资源简介:
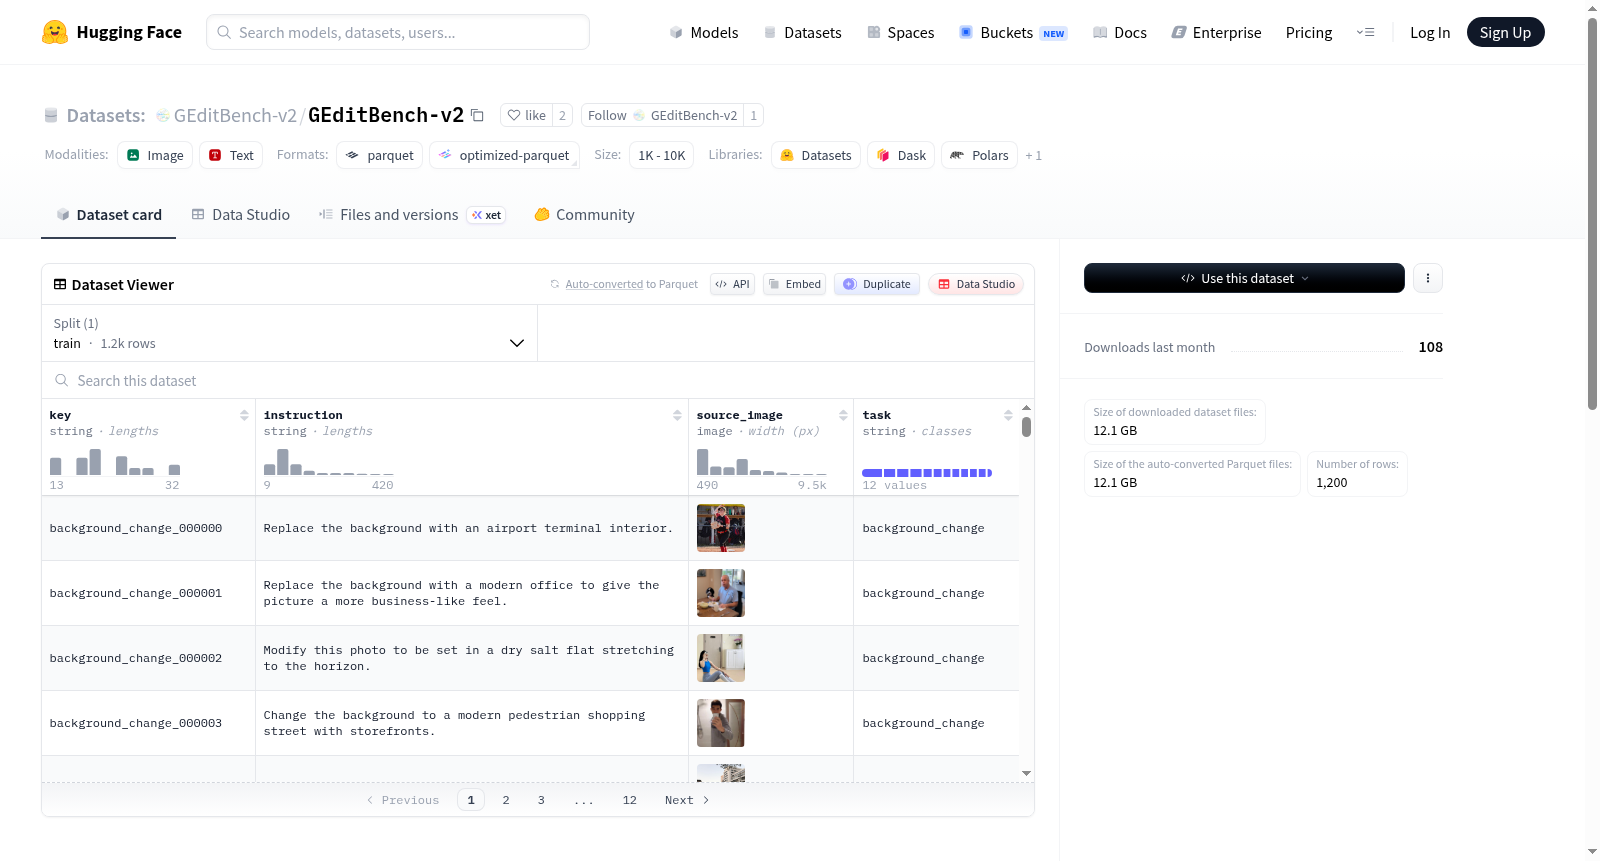
GEditBench v2 是一个全面的通用图像编辑基准数据集,包含 1,200 个真实世界用户查询,涵盖 23 种任务,并专门设有一个开放集类别,用于处理超出预定义任务范围的无约束、分布外编辑指令。数据集包含以下字段:'key'(键)、'instruction'(指令)、'source_image'(源图像)和 'task'(任务)。数据集分为一个训练集,包含 1,200 个样本,总大小为 11,886,569,896 字节,下载大小为 12,050,701,080 字节。该数据集适用于通用图像编辑任务的研究和评估。
GEditBench v2 is a comprehensive general-purpose image editing benchmark dataset containing 1,200 real-world user queries spanning 23 tasks, and it specifically features an open-set category for handling unconstrained, out-of-distribution editing instructions beyond predefined task scopes. The dataset includes the following fields: 'key', 'instruction', 'source_image', and 'task'. The dataset is split into a training set with 1,200 samples, with a total size of 11,886,569,896 bytes and a download size of 12,050,701,080 bytes. This dataset is suitable for research and evaluation of general image editing tasks.
GEditBench v2 数据集概述
数据集基本信息
- 数据集名称:GEditBench v2: A Human-Aligned Benchmark for General Image Editing
- 发布平台:Hugging Face
- 数据集地址:https://huggingface.co/datasets/GEditBench-v2/GEditBench-v2
数据集描述
GEditBench v2 是一个全面的人工对齐通用图像编辑基准。它包含 1,200 个真实世界的用户查询,涵盖 23 个任务,并专门设有一个 开放集类别,用于处理预定义任务之外的、无约束的、分布外的编辑指令。
数据集结构
特征(Features)
key:字符串类型。instruction:字符串类型。source_image:图像类型。task:字符串类型。
数据划分(Splits)
- 训练集(train)
- 样本数量:1200
- 数据集大小:11886569896 字节
- 下载大小:12050701080 字节
相关资源
- 项目主页:https://zhangqijiang07.github.io/gedit2_web/
- GitHub 仓库:https://github.com/ZhangqiJiang07/GEditBench_v2
- 相关数据集:VCReward Bench (https://huggingface.co/datasets/GEditBench-v2/VCReward-Bench)
- 相关模型:PVC Judge (https://huggingface.co/GEditBench-v2/PVC-Judge)