stas/openwebtext-10k
收藏资源简介:
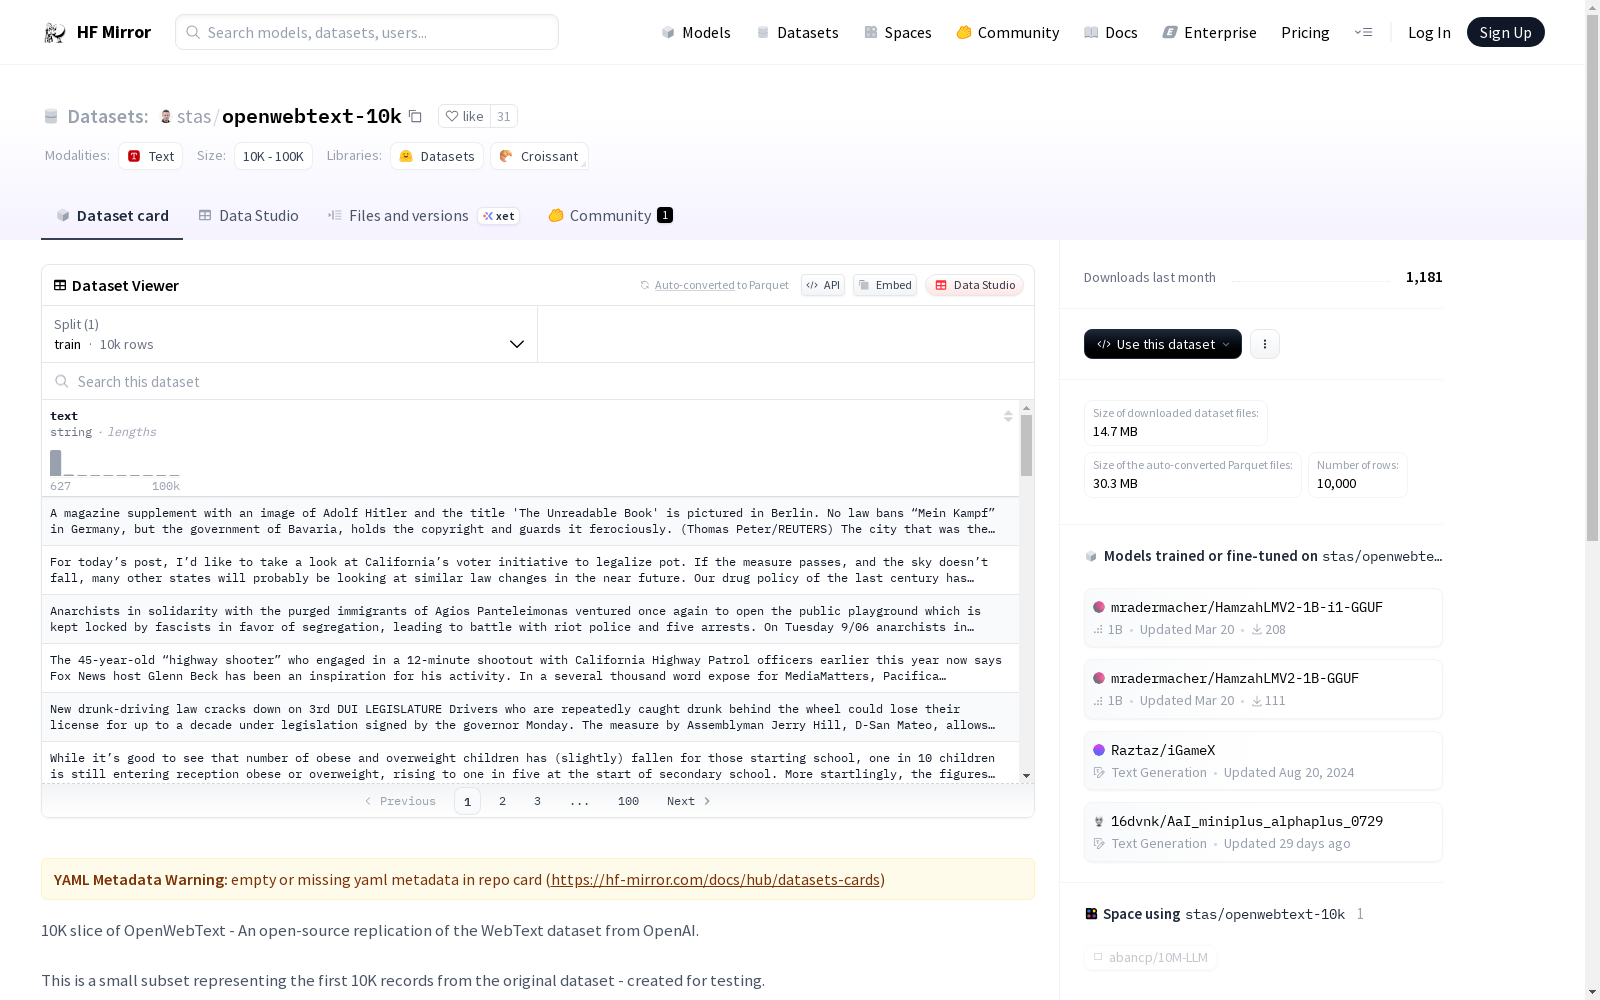
这是OpenWebText数据集的一个子集,名为stas/openwebtext-10k,它是OpenAI的WebText数据集的开源复制版本。该子集包含原始数据集的前10,000条记录,主要用于测试目的。数据集包含一个名为train的部分,具有text特征,共10,000行。压缩大小约为15MB,未压缩大小为50MB。
This is a subset of the OpenWebText dataset, named stas/openwebtext-10k, which is an open-source replica of OpenAI's WebText dataset. This subset contains the first 10,000 records of the original dataset, primarily intended for testing purposes. The dataset includes a split named "train", which features a "text" field, with a total of 10,000 rows. Its compressed size is approximately 15 MB, while the uncompressed size is 50 MB.
数据集概述
基本信息
- 名称: OpenWebText-10K
- 描述: 这是OpenAI的WebText数据集的一个开源复制品的小型子集,包含前10,000条记录,主要用于测试。
- 记录数: 10,000
- 数据结构: 单个特征
text - 数据大小:
- 压缩后: ~15MB
- 未压缩: 50MB
使用方法
-
加载数据集: 使用
datasets库加载数据集,命令如下: python from datasets import load_dataset ds = load_dataset(stas/openwebtext-10k) -
转换为JSONL格式: 使用以下代码将数据集转换为JSONL格式: python from datasets import load_dataset dataset_name = "stas/openwebtext-10k" name = dataset_name.split(/)[-1] ds = load_dataset(dataset_name, split=train) ds.to_json(f"{name}.jsonl", orient="records", lines=True)