Finnish-NLP/finepdfs-dclm-fineweb-edu-fi
收藏资源简介:
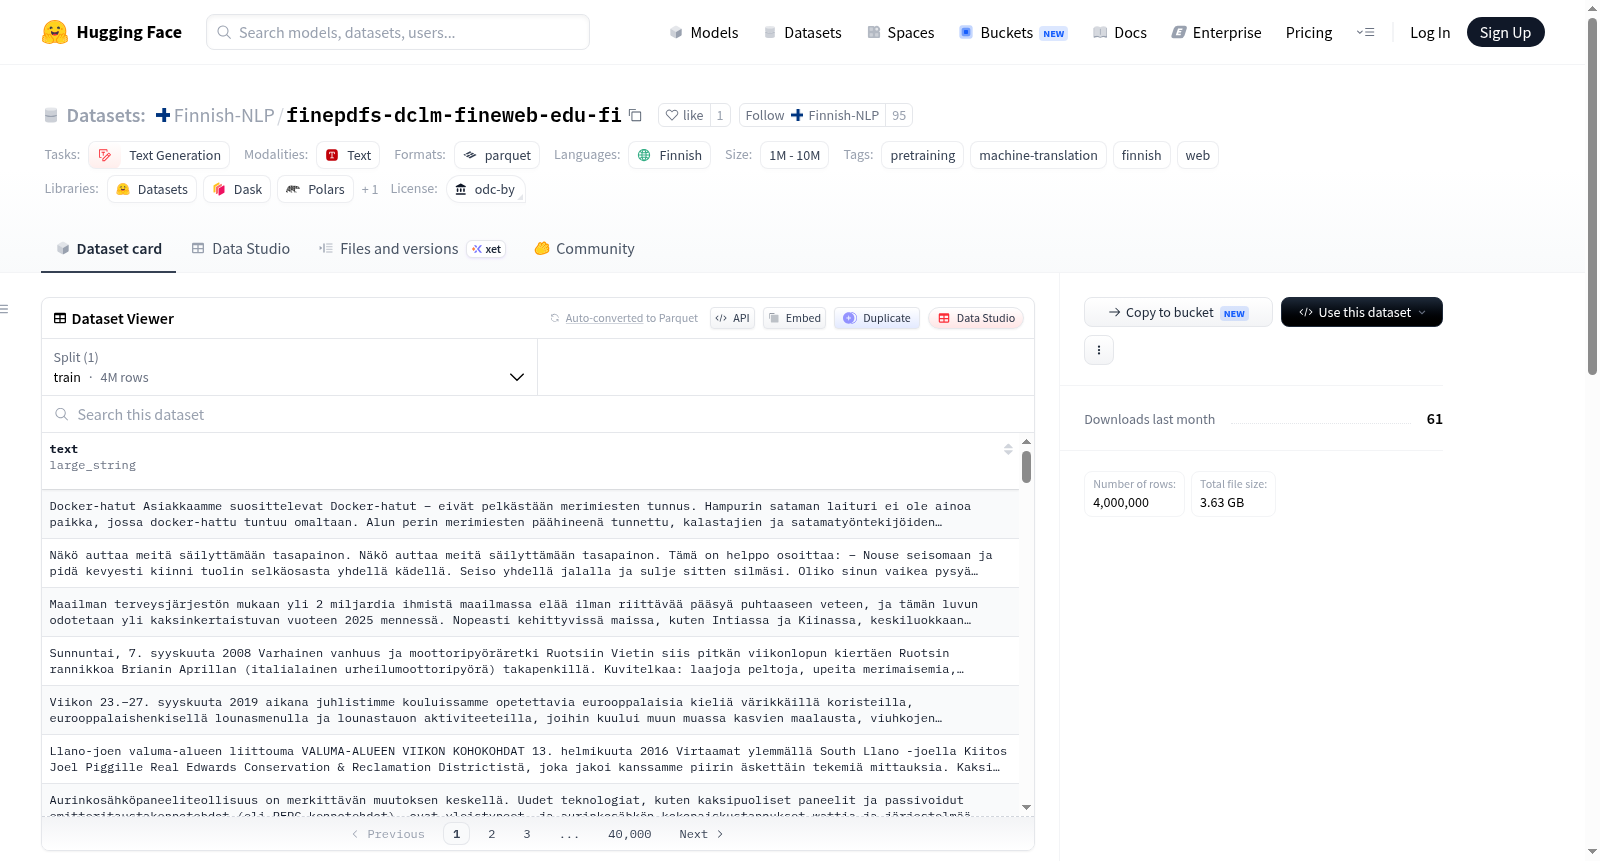
这是一个芬兰语机器翻译的预训练混合数据集,从英文来源FinePDFs、DCLM和FineWeb-Edu中抽取文档(长度约900个词符),专为芬兰语大语言模型的持续预训练而设计。使用基于Gemma的27B翻译模型(translategemma-27b)进行翻译,包含约4,000,000个文档,每个文档以纯文本形式存储,每行一个文档。原始数据以TFDS-style ArrayRecord格式存储,已转换为Parquet格式,便于通过Hugging Face datasets库加载。数据集语言为芬兰语(fi),许可证为odc-by,任务类别为文本生成,标签包括预训练、机器翻译、芬兰语和网络。注意事项包括可能存在机器翻译伪影和网络噪声,且内容继承上游来源的许可,需在再分发前验证。
A Finnish machine-translated pretraining mixture dataset drawn from English sources including FinePDFs, DCLM, and FineWeb-Edu (documents up to ~900 tokens), produced as continued-pretraining data for Finnish LLMs. Translated using the Gemma-based 27B translation model (translategemma-27b), with approximately 4,000,000 documents stored as plain text, one document per row. Originally in TFDS-style ArrayRecord format, converted to Parquet for easy loading with Hugging Face datasets. The dataset is in Finnish (fi), licensed under odc-by, with task categories for text-generation and tags including pretraining, machine-translation, Finnish, and web. Caveats include potential machine translation artifacts and web noise, with content inheriting upstream source licenses; verify licensing before redistribution.