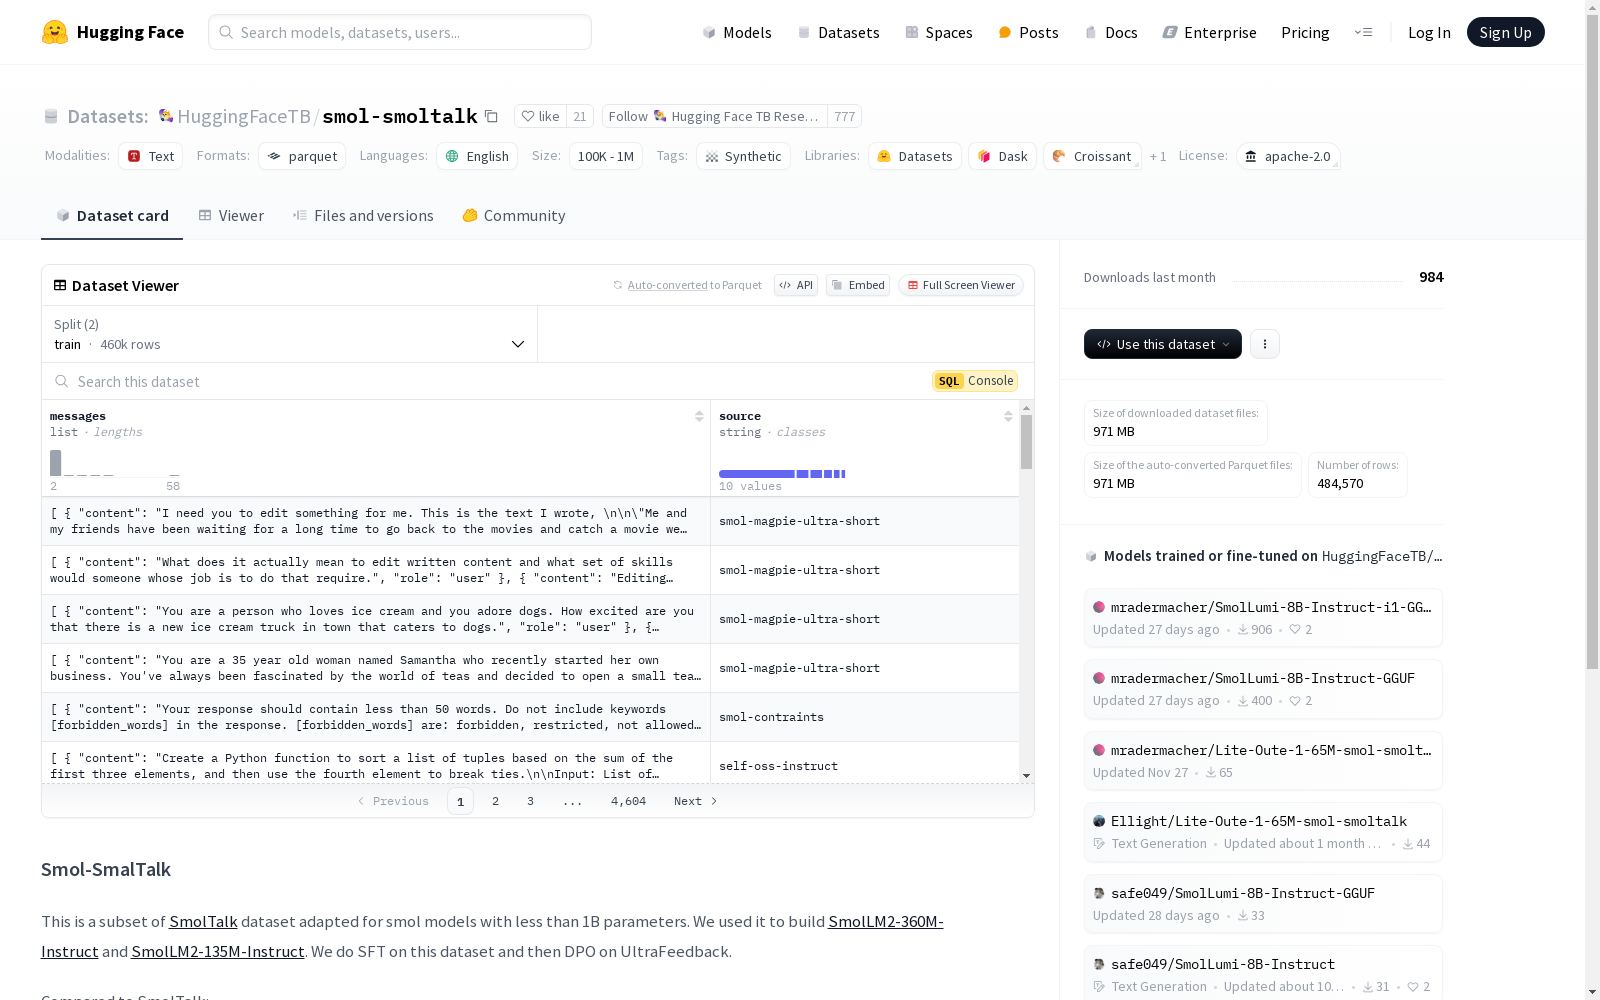
smol-smoltalk
收藏资源简介:
Smol-SmolTalk数据集是SmolTalk数据集的一个子集,专门为参数少于1B的小模型设计。该数据集用于构建SmolLM2-360M-Instruct和SmolLM2-135M-Instruct模型。与SmolTalk相比,Smol-SmolTalk的对话更短,包含的任务特定数据更少(如不包含函数调用和较少的重写和总结示例),并且不包含任何高级数学数据集。数据集包含两个主要特征:messages和source。messages是一个列表,包含content和role两个子特征,分别表示消息内容和角色。source表示数据来源。数据集分为训练集和测试集,训练集包含460341个样本,测试集包含24229个样本。
The Smol-SmolTalk dataset is a subset of the SmolTalk dataset, specifically tailored for small-sized models with parameter counts below 1B. It is utilized to construct the SmolLM2-360M-Instruct and SmolLM2-135M-Instruct models. Compared to the original SmolTalk dataset, Smol-SmolTalk contains shorter dialogues, fewer task-specific data entries (e.g., no function call content and fewer rewriting and summarization examples), and excludes any advanced mathematics-related datasets. The dataset includes two core features: `messages` and `source`. The `messages` field is a list containing two sub-features: `content` and `role`, which respectively denote the message content and the speaker role. The `source` field indicates the origin of the data. The dataset is split into training and test subsets, with 460,341 samples in the training set and 24,229 samples in the test set.
Smol-SmolTalk 数据集概述
基本信息
- 许可证: Apache 2.0
- 语言: 英语
- 标签: 合成数据
- 数据集名称: Smol-SmolTalk
- 数据集大小: 100K < n < 1M
数据集结构
特征
- messages:
- content: 字符串类型
- role: 字符串类型
- source: 字符串类型
数据分割
- train:
- 样本数量: 460341
- 字节数: 1811694118.6259818
- test:
- 样本数量: 24229
- 字节数: 95354393.3740182
文件大小
- 下载大小: 970652749 字节
- 数据集大小: 1907048512.0 字节
配置
- config_name: default
- 数据文件:
- train: data/train-*
- test: data/test-*
- 数据文件:
数据集描述
- 该数据集是 SmolTalk 数据集的一个子集,适用于参数少于 1B 的模型。
- 用于构建 SmolLM2-360M-Instruct 和 SmolLM2-135M-Instruct。
- 与 SmolTalk 相比:
- 对话更短。
- 包含的任务特定数据较少(例如,没有函数调用和较少的重写和总结示例)。
- 不包含任何高级数学数据集。
加载数据集示例
python from datasets import load_dataset
ds = load_dataset("HuggingFaceTB/smol-smoltalk", split="train")