INSAIT-Institute/ProofRank
收藏资源简介:
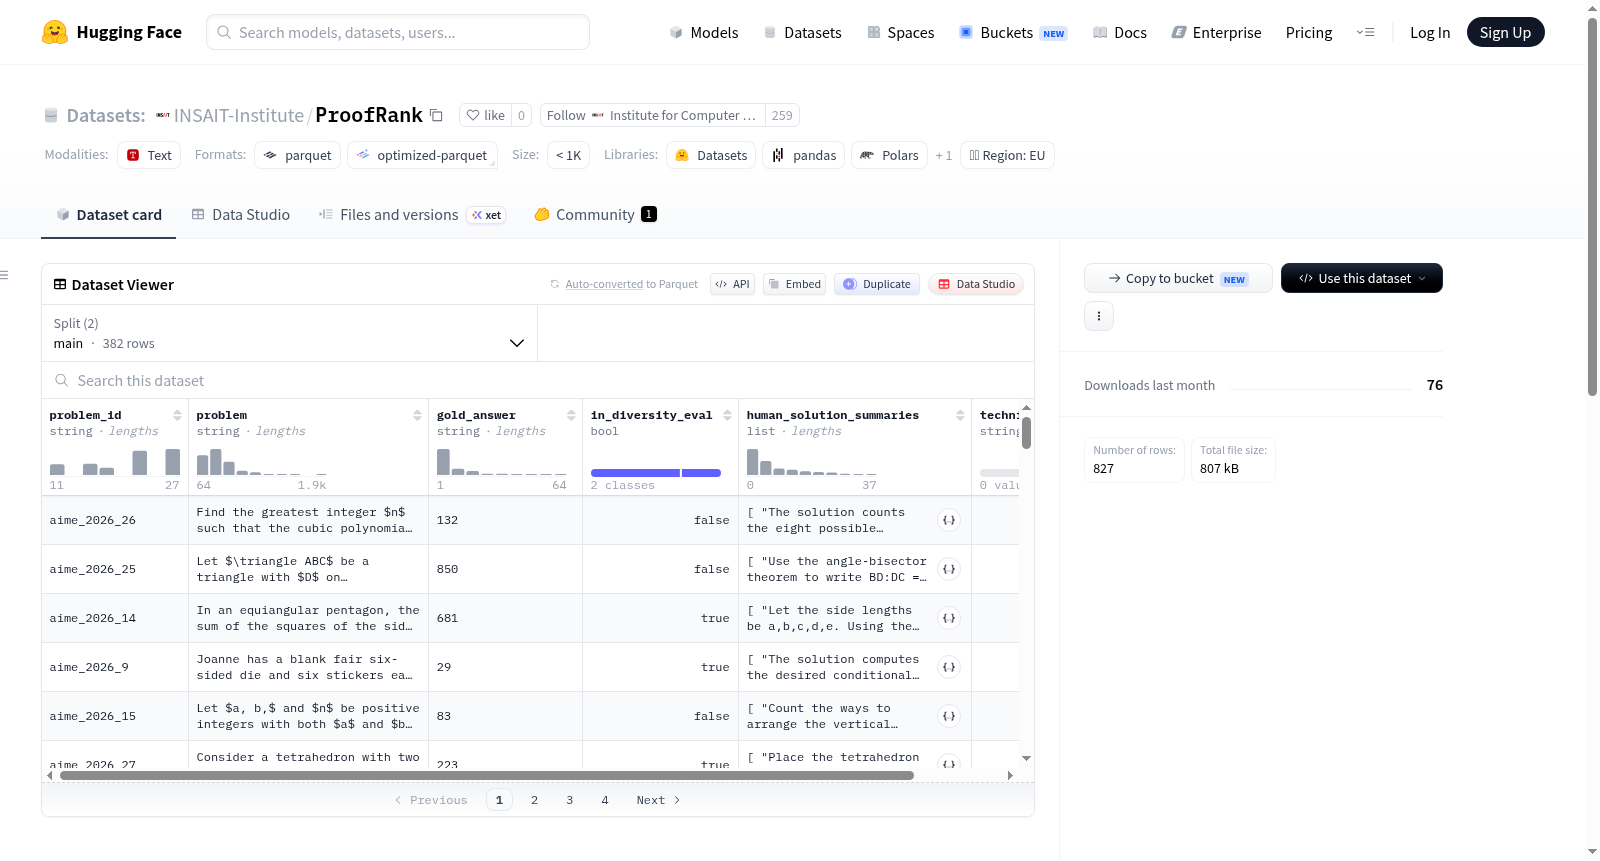
--- dataset_info: features: - name: problem_id dtype: string - name: problem dtype: string - name: gold_answer dtype: string - name: in_diversity_eval dtype: bool - name: human_solution_summaries list: string - name: technique dtype: string splits: - name: main num_bytes: 1472173 num_examples: 382 - name: adaptivity num_bytes: 205869 num_examples: 445 download_size: 802720 dataset_size: 1678042 configs: - config_name: default data_files: - split: main path: data/main-* - split: adaptivity path: data/adaptivity-* --- # ProofRank: Evaluating LLM Proof Quality beyond Correctness This dataset contains a collection of final-answer mathematical problems used for the ProofRank evaluation benchmark. It combines high-school level competition problems from MathArena (AIME, HMMT, Apex) and IMO-AnswerBench to evaluate large language models on proof quality metrics beyond basic correctness. ## Included Splits The dataset is divided into two main splits: - `main`: Contains **382** base problems used to evaluate the proof-level metrics (conciseness, computational ease, cognitive simplicity) and problem-level diversity. - `adaptivity`: Contains **445** problem-technique pairs used to evaluate a model's capacity to solve a problem using a specifically requested method. ## Schema | Column | Type | Description | | :--- | :--- | :--- | | `problem_id` | string | Unique identifier for the problem. Use this as the stable row key. | | `problem` | string | The mathematical problem statement. | | `gold_answer` | string | The ground-truth final answer used for correctness verification. | | `in_diversity_eval` | boolean | Indicates whether the problem is to be used in measuring the diversity metric. | | `human_solution_summaries` | list of strings | Summaries of human-written solutions used for LLM-based method clustering. | | `technique` | string, nullable | The specific mathematical technique a model is requested to use. Populated in the `adaptivity` split. |
This dataset is designed for problem-solving and evaluation, comprising 382 main examples and 445 adaptivity examples. Each example includes the following fields: problem_id (problem identifier), problem (problem description), gold_answer (standard answer), in_diversity_eval (boolean indicating if used for diversity evaluation), human_solution_summaries (list of human solution summaries), and technique (solving technique). The dataset is intended to support natural language processing tasks such as answer generation, solution summarization, and diversity evaluation, suitable for research and development contexts.