592人中国普通话与方言数字类语音数据_朗读(手机)
收藏资源简介:
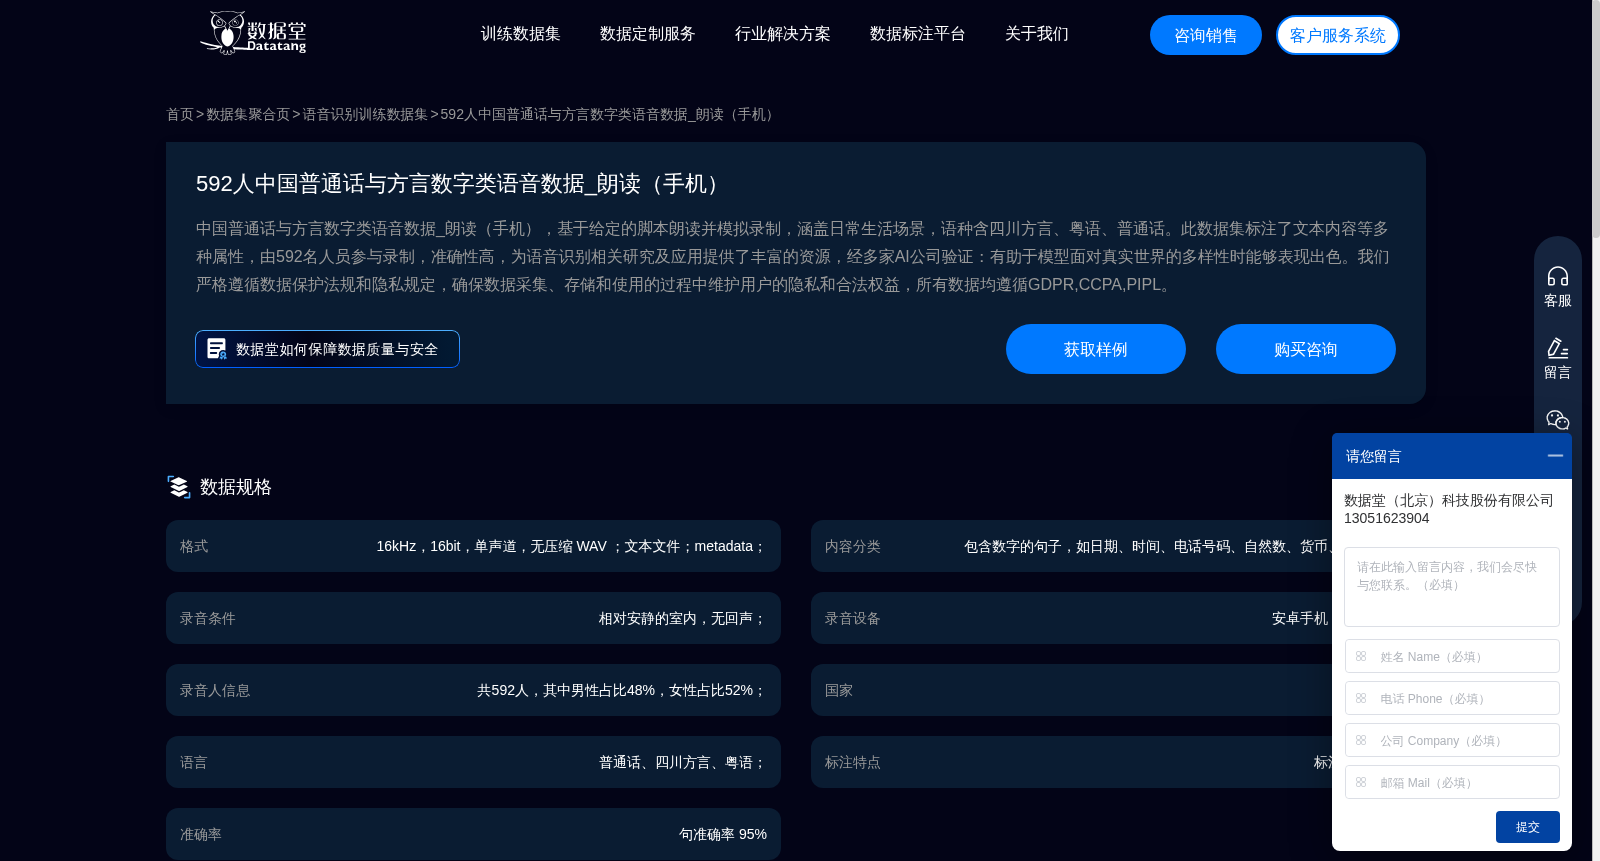
中国普通话与方言数字类语音数据_朗读(手机),基于给定的脚本朗读并模拟录制,涵盖日常生活场景,语种含四川方言、粤语、普通话。此数据集标注了文本内容等多种属性,由592 名人员参与录制,准确性高,为语音识别相关研究及应用提供了丰富的资源,经多家AI公司验证:有助于模型面对真实世界的多样性时能够表现出色。我们严格遵循数据保护法规和隐私规定,确保数据采集、存储和使用的过程中维护用户的隐私和合法权益,所有数据均遵循GDPR, CCPA, PIPL。
Mandarin and Chinese Dialect Digital Speech Dataset (Reading Aloud, Mobile-recorded). The dataset is collected through script-based reading aloud and simulated recording, covering daily life scenarios, and includes three language varieties: Sichuan dialect, Cantonese, and Standard Mandarin. This dataset is annotated with multiple attributes including text content, recorded by 592 participants, and features high accuracy. It provides abundant resources for speech recognition-related research and applications. Verified by multiple AI companies, it helps models achieve excellent performance when dealing with real-world variability. We strictly comply with data protection regulations and privacy rules, ensuring that user privacy and legitimate rights and interests are safeguarded throughout the entire process of data collection, storage and utilization. All data adheres to the requirements of GDPR, CCPA and PIPL.