dotan1111/MSA-nuc-4-seq
收藏资源简介:
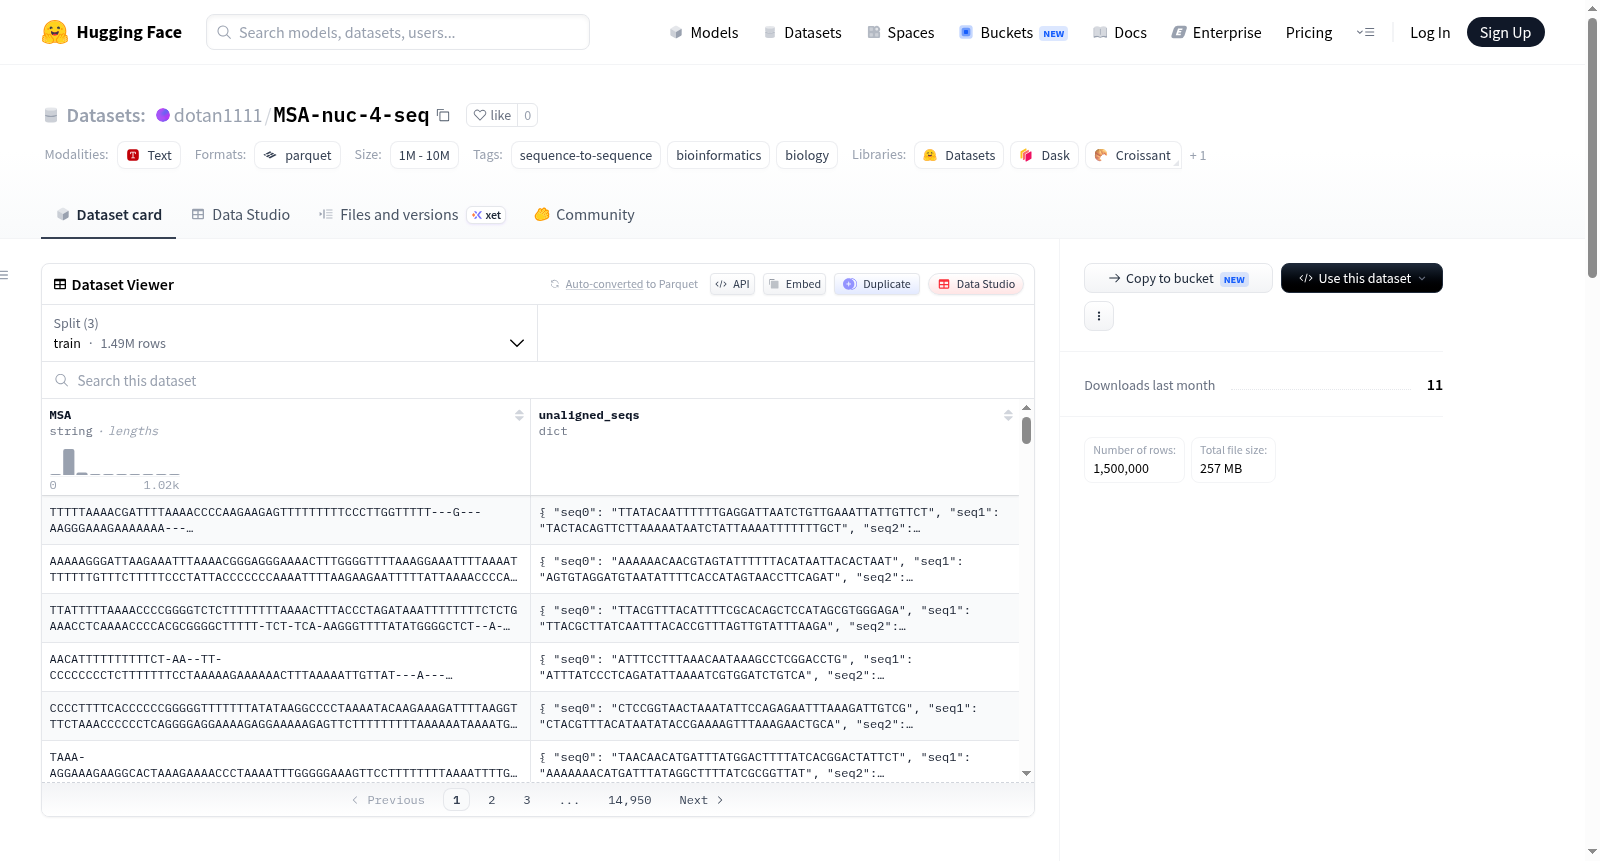
该数据集包含由SpartaABC生成的数百万个真实对齐序列,用于训练、验证和测试BetaAlign模型。数据集包括蛋白质和DNA的多序列对齐(MSA),每个数据集包含十个序列。生成这些数据时,使用了随机生成的系统发育树和特定的替代模型参数。蛋白质数据集使用WAG+G模型生成,DNA数据集使用GTR+G模型生成。每个随机树的枝长从均匀分布中抽取,序列生成时考虑了插入和删除率以及Zipfian分布参数。
This dataset contains millions of authentic aligned sequences generated by SpartaABC, which are utilized for training, validation, and testing of the BetaAlign model. The dataset includes multiple sequence alignments (MSA) for proteins and DNA, with each MSA containing ten sequences. During the generation of these sequences, randomly generated phylogenetic trees and specific substitution model parameters were adopted. The protein MSAs were generated using the WAG+G substitution model, while the DNA MSAs were generated using the GTR+G substitution model. Branch lengths of each random phylogenetic tree were drawn from a uniform distribution, and insertion and deletion rates as well as Zipfian distribution parameters were considered during the sequence generation process.
多序列比对作为序列到序列学习问题
数据
- 数据生成工具:使用SpartaABC(Loewenthal et al., 2021)生成数百万个真实比对。
- 输入参数:
- 根系进化树,包括拓扑结构和分支长度。
- 替换模型(氨基酸或核苷酸)。
- 根序列长度。
- 插入和删除模型参数,包括插入率(R_I)、删除率(R_D)、插入Zipfian分布参数(A_I)和删除Zipfian分布参数(A_D)。
- 树生成:随机进化树拓扑结构使用ETE版本3.0(Huerta-Cepas et al., 2016)生成,默认参数。
- 数据集:
- 生成1,495,000个蛋白质多序列比对(MSA),用于训练、验证和测试数据。
- 生成相同数量的DNA MSA。
- 每个随机树的分支长度从均匀分布*(0.5,1.0)*中抽取。
- 序列使用SpartaABC生成,参数为R_I,R_D in (0.0,0.05),A_I, A_D in (1.01,2.0)。
- 根长度在范围*[32,44]*内均匀采样。
- 蛋白质数据集使用WAG+G模型生成,DNA数据集使用GTR+G模型生成。
- 示例:
- 示例比对:{"MSA": "AAAC-GGG", "unaligned_seqs": {"seq0": "AAG", "seq1": "ACGG"}}