european-gender-drama-bge-embeddings
收藏资源简介:
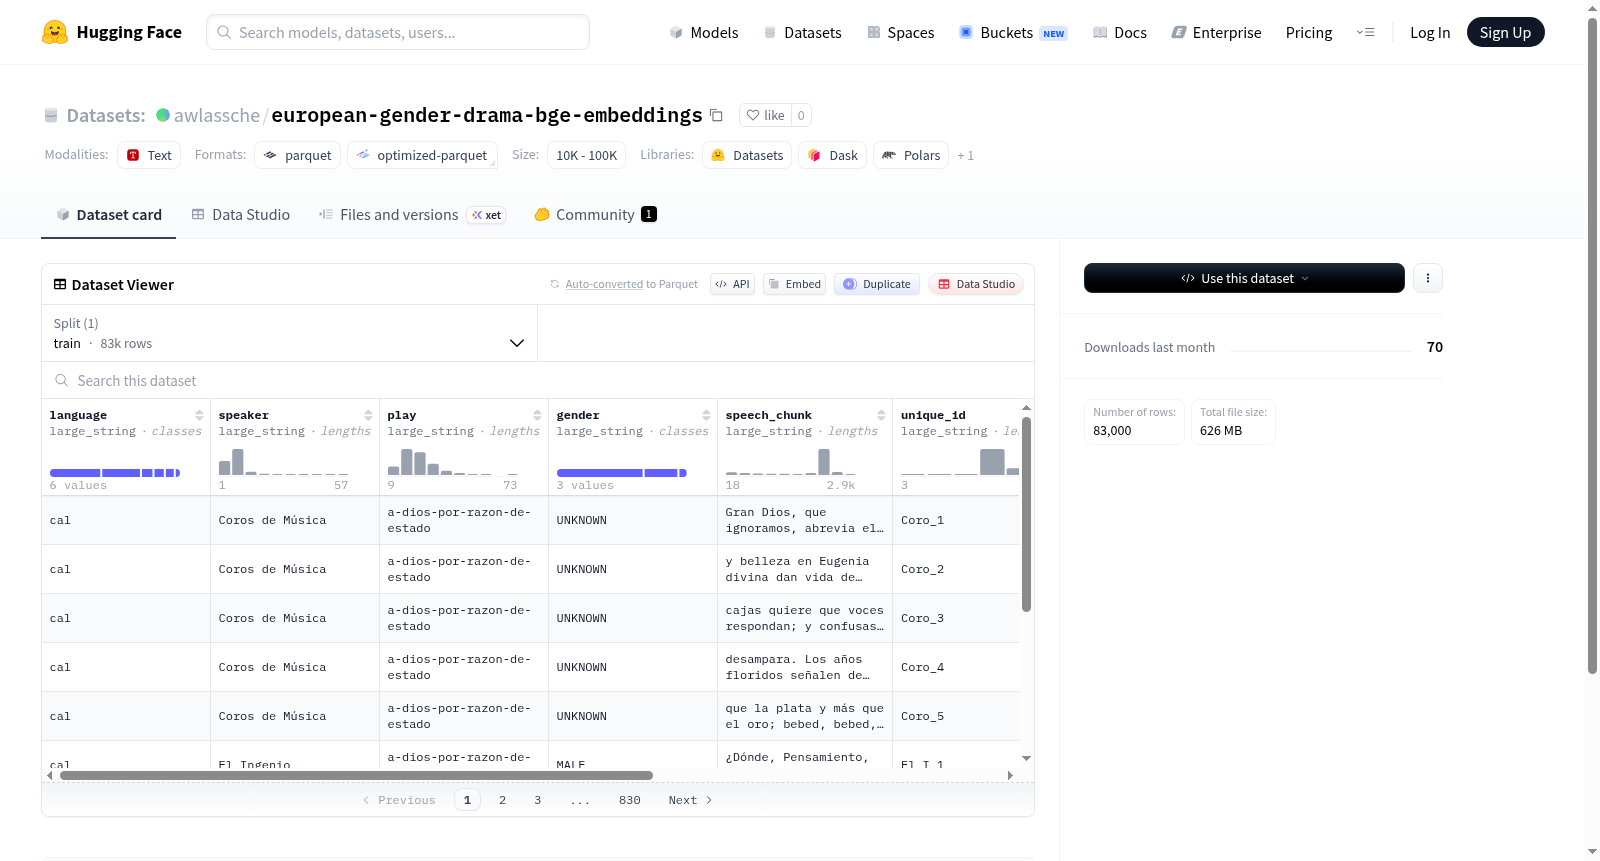
该数据集是一个包含多语言戏剧语音文本片段的结构化数据集,主要用于语音处理、自然语言处理和多模态分析相关研究。数据集共包含83,000个训练样本,总大小约844MB。每个样本包含以下特征字段:语言(language)、说话人(speaker)、所属戏剧/剧本(play)、说话人性别(gender)、语音片段文本内容(speech_chunk)、唯一标识符(unique_id)、预计算的嵌入向量(embedding)以及年份(year)。其中嵌入向量字段为浮点数列表格式,可能用于表示语音或文本的语义特征。数据集适用于说话人识别、情感分析、戏剧语言风格研究、跨语言语音文本分析等任务场景。
This dataset is a structured collection of multilingual drama speech text segments, primarily used for speech processing, natural language processing, and multimodal analysis research. It contains 83,000 training samples with a total size of approximately 844MB. Each sample includes the following feature fields: language, speaker, play (drama/script), gender, speech_chunk (text content of the speech segment), unique_id, embedding (pre-computed vector), and year. The embedding field is in a list of floating-point numbers format, likely representing semantic features of speech or text. The dataset is suitable for tasks such as speaker recognition, emotion analysis, drama language style research, and cross-lingual speech-text analysis.