eval-penfever_stageD-thinkbudget-80-8B_DCAgent2_swebench-verified-random-100-folders-traces
收藏资源简介:
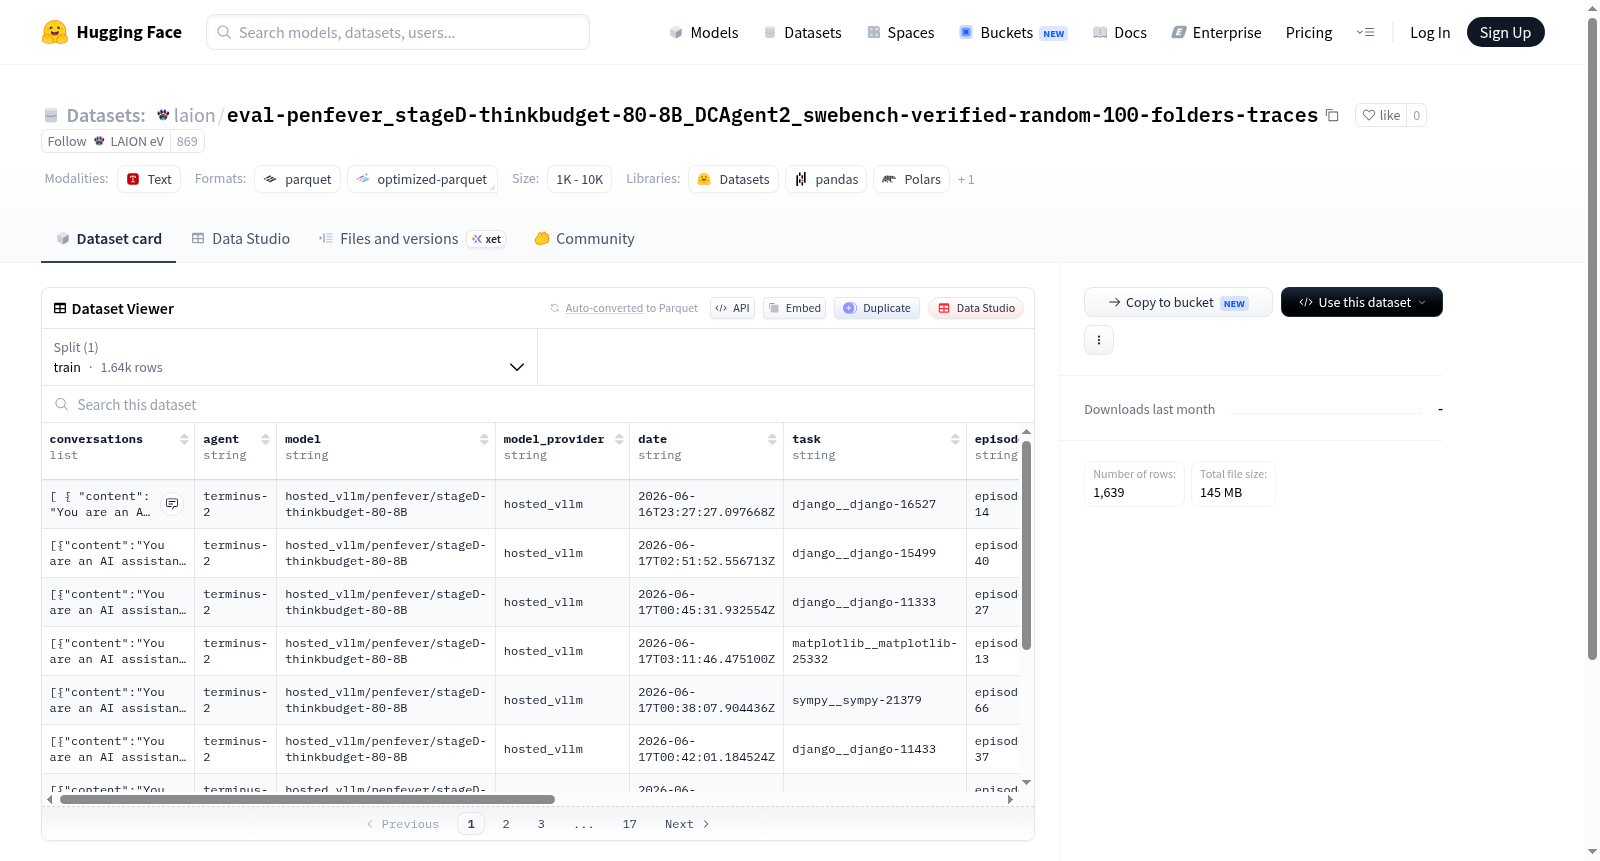
该数据集是一个结构化对话数据集,包含1639个训练样本,总大小约为254MB。数据特征包括:conversations字段,以列表形式存储对话内容,每个条目包含content(内容)和role(角色)字符串;其他字段如agent(代理)、model(模型)、model_provider(模型提供商)、date(日期)、task(任务)、episode(剧集)、run_id(运行ID)、trial_name(试验名称)、result(结果)、verifier_output(验证器输出)和trace_source(追踪来源),均为字符串类型,提供了对话的元数据和执行上下文。数据集适用于对话系统分析、多轮交互建模、代理行为评估或任务导向对话研究等场景,通过结构化字段支持对模型性能、任务执行结果和对话轨迹的深入分析。
This dataset is a structured dialogue dataset containing 1639 training samples with a total size of approximately 254MB. The data features include: a conversations field that stores dialogue content in a list format, with each entry containing content and role strings; other fields such as agent, model, model_provider, date, task, episode, run_id, trial_name, result, verifier_output, and trace_source are all string types, providing metadata and execution context for the dialogues. The dataset is suitable for scenarios such as dialogue system analysis, multi-turn interaction modeling, agent behavior evaluation, or task-oriented dialogue research, and supports in-depth analysis of model performance, task execution results, and dialogue trajectories through structured fields.
数据集概述
| 项目 | 内容 |
|---|---|
| 数据集名称 | eval-penfever_stageD-thinkbudget-80-8B_DCAgent2_swebench-verified-random-100-folders-traces |
| 链接地址 | https://huggingface.co/datasets/laion/eval-penfever_stageD-thinkbudget-80-8B_DCAgent2_swebench-verified-random-100-folders-traces |
| 数据集大小 | 约 253.98 MB(数据集总字节数) |
| 下载大小 | 约 145.05 MB |
| 配置 | 默认配置(default) |
| 数据分割 | 仅训练集(train),共 1,639 条样本 |
数据特征
该数据集包含以下字段:
- conversations(对话列表):每个对话包含:
content:对话内容(字符串)role:角色(字符串)
- agent(代理,字符串)
- model(模型,字符串)
- model_provider(模型提供方,字符串)
- date(日期,字符串)
- task(任务,字符串)
- episode(轮次,字符串)
- run_id(运行ID,字符串)
- trial_name(试验名称,字符串)
- result(结果,字符串)
- verifier_output(验证器输出,字符串)
- trace_source(追踪来源,字符串)
数据文件
- 训练集数据文件位于
data/train-*(通配符匹配多个文件)。