IIfSLM-v1
收藏资源简介:
IIfSLM(Small Language Models智力指数)v1是一个专为评估0.5B至3B参数范围内小型语言模型设计的抗污染基准测试套件。该数据集包含三个子集:gsm8krefn、humanevalrefn和arcchalrefn,分别源自OpenAI的GSM8K(数学应用题)、OpenAI的HumanEval(函数代码生成)和AllenAI的ARC-Challenge(科学选择题)。每个子集均对原始问题进行了重新表述(refined),但保留了原始答案和验证方法。具体而言,gsm8krefn包含重新措辞的数学文字题,答案格式为数字;humanevalrefn包含重新表述的函数文档字符串,正确性通过实际执行模型生成的代码并对照原始测试套件进行验证;arcchalrefn包含重新表述的多选题科学问题,正确性通过精确匹配标准答案判定。数据集的命名约定中“refn”代表“refined”,表明是对原始基准的优化版本。使用该数据集时需注意,报告分数对生成时的token预算(max_new_tokens)非常敏感,不同预算下的结果可能不可直接比较。数据集以Hugging Face Datasets格式提供,每个子集均有一个测试集(split='test'),可通过指定配置名称加载。许可证为CC-BY-4.0,但原始数据集保留各自的许可要求(如MIT、CC-BY-SA-4.0),其中arcchalrefn由于衍生自CC-BY-SA-4.0,需遵守相同许可协议。
IIfSLM (Small Language Models Intelligence Index) v1 is a contamination-resistant benchmark suite designed to evaluate small language models in the range of 0.5B to 3B parameters. It contains three subsets: gsm8krefn, humanevalrefn, and arcchalrefn, derived from OpenAIs GSM8K (math word problems), OpenAIs HumanEval (function code generation), and AllenAIs ARC-Challenge (science multiple-choice questions), respectively. Each subset features rephrased (refined) versions of the original questions while preserving the original answers and verification methods. Specifically, gsm8krefn includes reworded math word problems with numeric answers; humanevalrefn includes rephrased function docstrings, where correctness is evaluated by executing the generated code against the original test suite; arcchalrefn includes rephrased multiple-choice science questions, with correctness determined by exact match to the standard answers. The refn in the naming convention stands for refined, indicating optimized versions of the original benchmarks. Users should note that reported scores are sensitive to the token budget (max_new_tokens) during generation, and results under different budgets may not be directly comparable. The dataset is provided in Hugging Face Datasets format, with each subset having a test set (split=test) accessible by specifying the configuration name. It is licensed under CC-BY-4.0, but original datasets retain their respective licenses (e.g., MIT, CC-BY-SA-4.0), and arcchalrefn, being derived from CC-BY-SA-4.0, must comply with the same license.
IIfSLM - 小型语言模型智能指数 v1
数据集概述
IIfSLM(Intelligence Index for Small Language Models)是一个用于评估0.5B至3B参数范围内小型语言模型的基准测试套件,具备抗污染特性,旨在为社区提供标准化的模型评估平台。
数据集配置
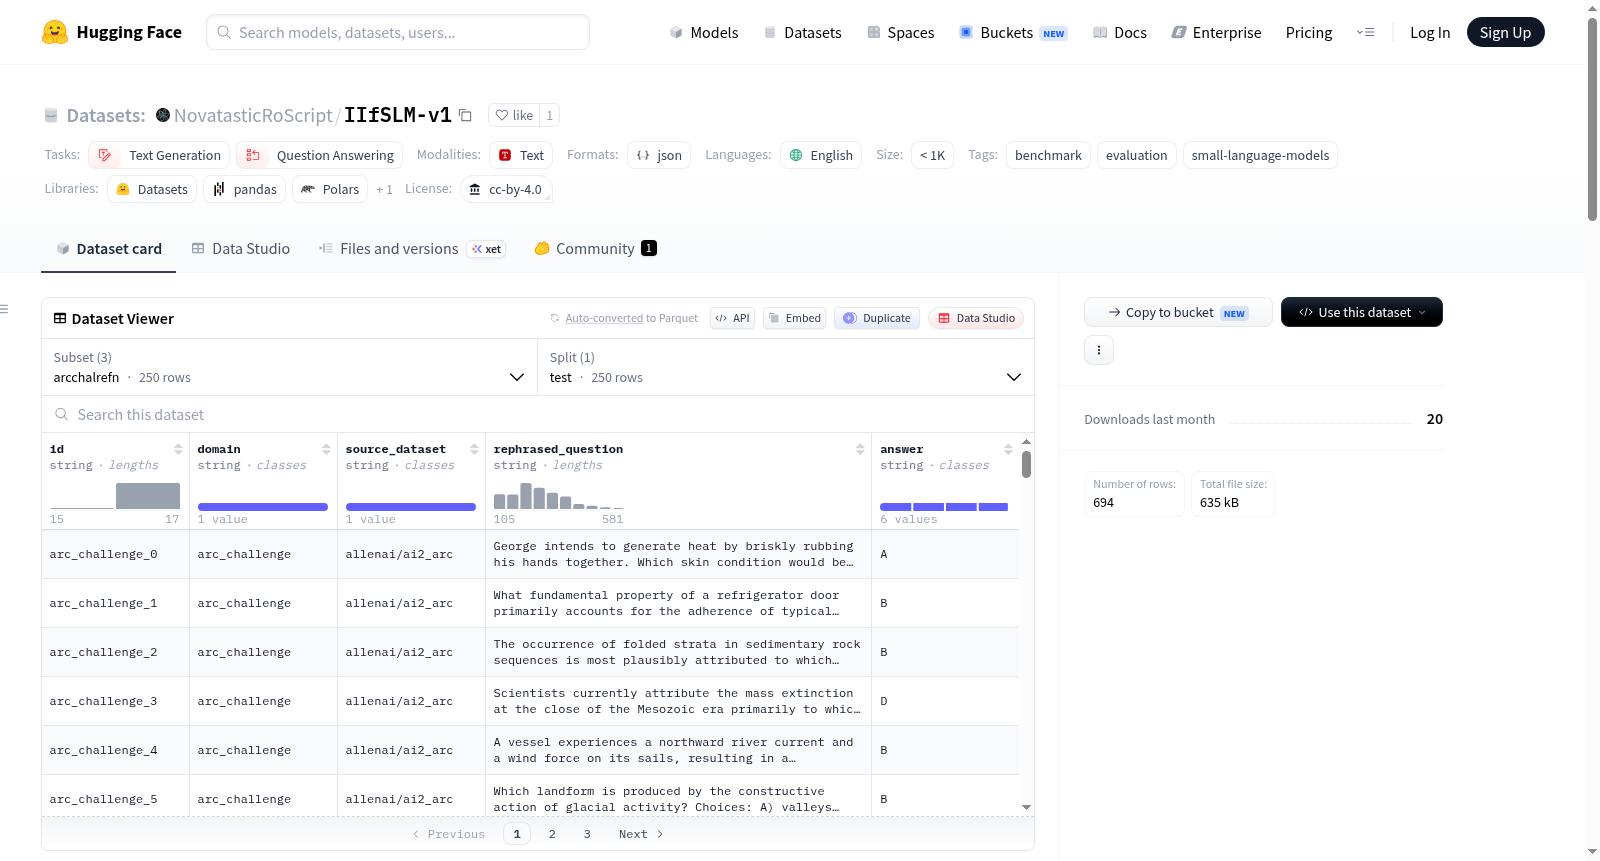
数据集包含三个子配置,均提供测试集(split: test),所有配置的原始问题均经过改写(refined),但保留原始已验证的答案:
| 配置名称 | 来源数据集 | 原始许可 | 内容格式 |
|---|---|---|---|
gsm8krefn |
openai/gsm8k | MIT | 改写后的数学文字题,需输出数值答案 |
humanevalrefn |
openai/openai_humaneval | MIT | 改写后的函数文档字符串,通过执行代码验证正确性 |
arcchalrefn |
allenai/ai2_arc | CC-BY-SA-4.0 | 改写后的科学选择题,需与标注选项精确匹配 |
评估方法说明
- 生成预算影响:评测分数对生成令牌预算高度敏感。在初步评估中,将
max_new_tokens从512提升至900,同一组299道gsm8krefn问题的准确率提升了20个百分点,原因是减少了答案截断。复现分数时必须匹配条目中注明的令牌预算。 - humanevalrefn验证:正确性通过实际执行模型代码并对照原测试套件验证,而非简单的字符串匹配。
- arcchalrefn验证:正确性通过与标注选项的精确匹配判定。
使用方式
可通过load_dataset函数加载各配置的测试集,例如:
python
from datasets import load_dataset
gsm8k = load_dataset("NovatasticRoScript/IIfSLM-v1", "gsm8krefn", split="test") humaneval = load_dataset("NovatasticRoScript/IIfSLM-v1", "humanevalrefn", split="test") arc = load_dataset("NovatasticRoScript/IIfSLM-v1", "arcchalrefn", split="test")
排行榜
社区成员可通过"Community"讨论区提交模型得分及平均值(需附证明),官方仅接受0.5B至3B参数范围的小型模型。当前排行榜首位为Atomight-V2.5-1.7B(1.7B参数),其gsm8krefn得分为86.96%,其余指标仍在评估中。
许可信息
- 本数据集许可:CC-BY-4.0
- 注意事项:底层来源数据集保留各自原始许可及归属要求(见上述表格),本仓库的改写问题属于衍生作品,不替代原始许可条款。尤其
arcchalrefn衍生自CC-BY-SA-4.0许可的来源,需遵守相同的分享要求。