20260817-comprehension_V3
收藏资源简介:
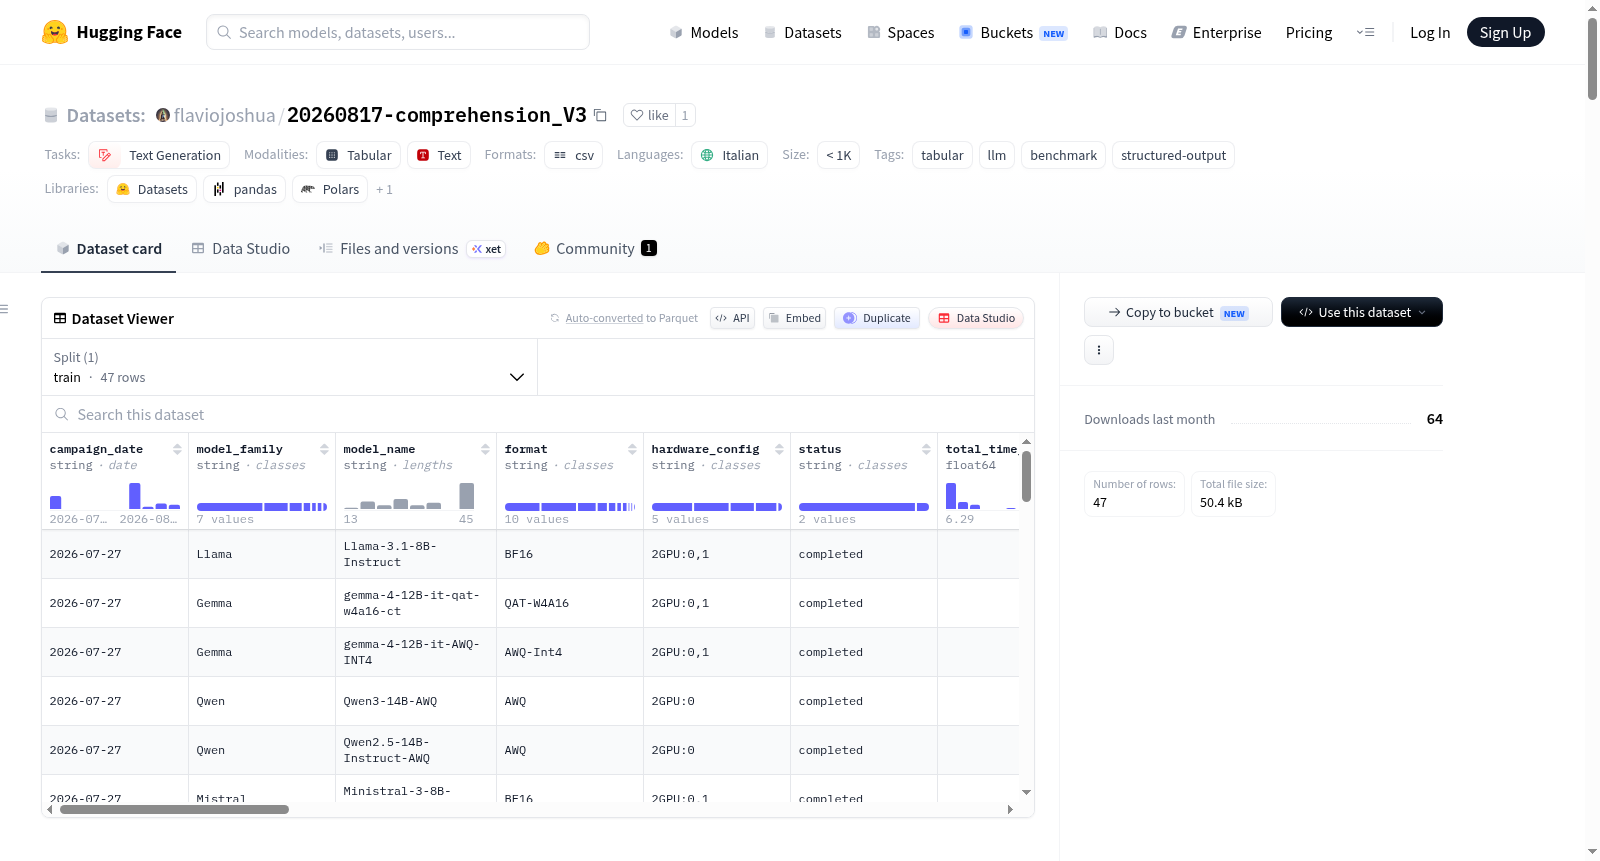
该数据集为model_comparison_Table.csv,是一个用于语言模型(LLM)推理和V3理解基准测试的表格数据集。数据集包含43行(截至2026年8月18日),每行对应一次特定模型、权重格式、入口点、测试数据集、执行环境和日志源的独立运行。数据集的目的是构建一个可复现的操作基准,用于选择能够正确响应结构化V3案例的推理配置,而非训练模型或发布绝对排名。数据内容基于V3数据集,该数据集分离三个评估轴:轴A(JSON可解析性)、轴B(模式、类型、基数与约束)和轴C(决策正确性)。轴C分数范围为0-100,由自动评判器(Auto-Judge)根据加权规则计算,具体包括五个关键项(verdetto、aliquota、importo、riferimenti、motivazione),总分最高135分,最终转换为百分比。数据集还包含操作性能指标(如延迟、令牌数、吞吐量)和错误计数。文件包含25列,涵盖身份与可复现性(如campaign_date、model_family、model_name、format、entrypoint_script、test_dataset_id、hardware_config、source_log)、状态与时间(如status、total_time_sec、generation_time_sec_total、generated_tokens、avg_generation_tok_sec、judge_time_sec_total、generated_tokens_judge)、错误与质量(如total_error_count、auto-judge-AsseC、OpenAI-Judge-AsseC、delta_AsseC、finish_reason、notes)。数据集主要适用于文本生成任务,语言为意大利语,规模小于1000行。使用时需注意:auto-judge-AsseC是自动评判结果,非人工审核;远程推理的吞吐量(tok/s)包含网络延迟,不可与本地GPU直接比较;不同硬件配置(如本地、云、远程提供商)的对比需控制变量并进行重复运行。
This dataset is model_comparison_Table.csv, a tabular dataset for benchmarking language model (LLM) inference and V3 understanding. It contains 43 rows (as of August 18, 2026), each corresponding to an independent run of a specific model, weight format, entry point, test dataset, execution environment, and log source. The purpose is to build a reproducible operational benchmark for selecting inference configurations that correctly respond to structured V3 cases, rather than training models or publishing absolute rankings. The data is based on the V3 dataset, which separates three evaluation axes: Axis A (JSON parseability), Axis B (schema, type, cardinality, and constraints), and Axis C (decision correctness). Axis C scores range from 0 to 100, computed by an Auto-Judge using weighted rules, including five key items (verdetto, aliquota, importo, riferimenti, motivazione) with a maximum total of 135 points, then converted to a percentage. The dataset also includes operational performance metrics (e.g., latency, token count, throughput) and error counts. The file contains 25 columns covering identity and reproducibility (e.g., campaign_date, model_family, model_name, format, entrypoint_script, test_dataset_id, hardware_config, source_log), status and time (e.g., status, total_time_sec, generation_time_sec_total, generated_tokens, avg_generation_tok_sec, judge_time_sec_total, generated_tokens_judge), and errors and quality (e.g., total_error_count, auto-judge-AsseC, OpenAI-Judge-AsseC, delta_AsseC, finish_reason, notes). The dataset is primarily applicable to text generation tasks, with language in Italian, and has a size of less than 1000 rows. Usage notes: auto-judge-AsseC is an automated judgment result, not manually reviewed; throughput (tok/s) for remote inference includes network latency and should not be directly compared with local GPU; comparisons across different hardware configurations (e.g., local, cloud, remote providers) require controlled variables and repeated runs.
数据集概述
数据集名称:LLM Inference and V3 Comprehension Benchmarks
数据集标识:flaviojoshua/20260817-comprehension_V3
语言:意大利语 (it)
任务类别:文本生成 (text-generation)
数据规模:少于 1,000 行 (n<1K),当前 CSV 包含 43 行
标签:tabular, llm, benchmark, structured-output
数据内容与结构
该数据集以表格形式 (model_comparison_Table.csv) 记录大语言模型在V3 管理/规范案例理解基准上的推理与评估结果。每一行代表一次独立的模型运行(run),包含:
- 模型与配置:模型家族、模型名称、权重格式(如 BF16、GPTQ-Int4、AWQ 等)、入口脚本。
- 数据集与输入:测试数据集标识(
DS_INST_V3_INPUT_3或V3-split-case3)、实际输入文件列表。 - 运行环境:硬件配置(本地 GPU、云 A100、远程推理提供商)及执行方式(on-premise、cloud、remote provider)。
- 性能与状态:端到端耗时、生成时间、token 数、吞吐量、错误计数、完成原因。
- 质量评估:
auto-judge-AsseC(自动评判的 Asse C 分数,0-100)、OpenAI-Judge-AsseC(外部 OpenAI 评判,当前全为 NA)、二者差值delta_AsseC。
数据集共有 25 列,分为身份与可复现性、状态与时间/token、错误与质量/终止三个维度。CSV 文件可直接在 Hugging Face Dataset Viewer 中查看和筛选。
评估框架:V3 三轴体系
数据集的核心是 V3 理解评估,分离三个不同的质量属性:
| 轴 | 验证内容 | 说明 |
|---|---|---|
| Asse A | JSON 可解析性 | 输出是否为合法的 JSON |
| Asse B | 结构合规性 | Schema、类型、基数、约束是否符合要求 |
| Asse C | 决策正确性(merito) | 对管理/规范案例的实质判断是否正确 |
Asse C 分数由自动评判器(Auto-Judge)按照 V3 评分规则生成,范围 0-100。阈值划分:
- < 60%:理解不可接受 (
comprensione_non_accettabile) - 60% - 80%:需要人工监督
- ≥ 80%:达到项目理解阈值
Asse C 评分细节:每个问题满分 10 分,由 5 个评分键组成(verdetto、aliquota、importo、riferimenti、motivazione),各键权重不同。总分通过加权公式计算:Asse_C_pct = Σ(peso_domanda × punti_domanda) / Σ(peso_domanda × 10) × 100。当前数据集所有问题权重之和为 13.5,理论上限为 135 分。
运行环境分类
数据集中包含三种推理执行方式,通过 hardware_config 列区分:
| 硬件配置 | 执行位置 | 备注 |
|---|---|---|
2GPU:0、2GPU:0,1、2GPU:0,1,CPU |
本地(on-premise) | 本地工作站,使用 RTX 5060 Ti 16GB / RTX 3060 12GB |
V100 |
本地(on-premise) | Tesla V100-SXM2-32GB,FP16 加载 |
A100:0 |
云(cloud) | Studio Lightning AI,A100-SXM4-80GB |
Inference Provider + Together |
远程(remote) | 通过 Hugging Face Inference Providers 路由到 Together 执行,本地不加载模型权重 |
重要限制:远程运行(如 Together)的速度(tok/s)包含网络、队列和服务器端服务时间,不等同于本地 GPU 吞吐量,不可直接与本地/云 GPU 数据比较。
数据适用性与限制
- 目的:构建可复现的操作性基准,用于选择能正确响应 V3 结构化案例的推理配置,而非训练模型或发布模型排名。
- 当前状态:所有行的
OpenAI-Judge-AsseC均为NA,表示尚无 OpenAI 外部评判结果。delta_AsseC也因此为NA。 - 单次运行对比的局限:数据集不用于证明量化、GPU 或提供商间的因果差异,需通过受控重复实验(相同数据集、参数、模型版本、固定外部评判器)才能得出结论。
- 历史数据清理:V1/V2 的 21 行数据已移除,因为它们不计算 Asse C,与 V3 行不具可比性。当前文件仅有 V3 数据集行(43 行)。
- 缺失值处理:
NA表示无法从日志中可靠重建的测量,不等于零。
扩展建议
README 明确建议未来数据收集应增加以下字段,以提高可复现性:
run_id、run_timestamp_utc(唯一标识运行)dataset_version、dataset_revision(明确 V1/V2/V3 版本)model_revision(固定模型 checkpoint)temperature、top_p、max_new_tokens、seed(生成参数)inference_provider、execution_location、hardware_model(细化运行环境)source_log_sha256(链接不可变日志)
这些字段当前未在数据集中,但作为未来版本的建议项被记录。
相关文件
- 输入文件:
input_ids/README_input-3-Explanation.md(详细说明五个 V3 输入文件) - 评分规则:
input_ids/risposte-3-istruzioni.md(定义 Auto-Judge 的评分键) - 模型文档:
models_hf/GPT_OSS/Inference_Provider/README.md(记录 Together 提供商配置)