OFA-Sys/OccuQuest
收藏资源简介:
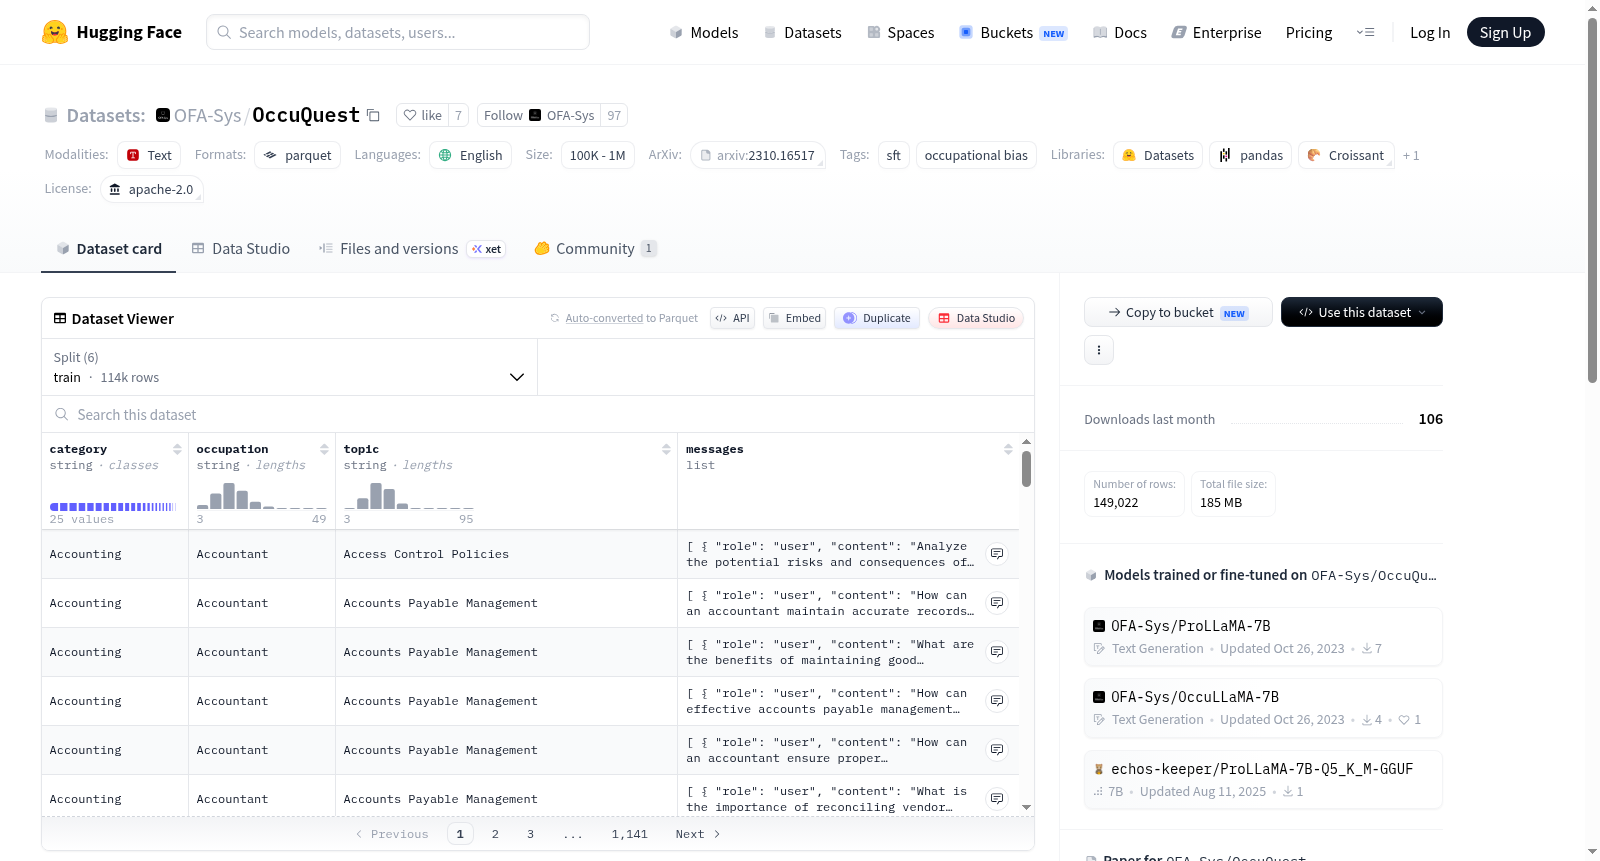
OccuQuest是一个旨在减少大型语言模型中职业偏见的数据集,包含超过110,000个提示-完成对和30,000多个对话,覆盖26个职业类别中的1,000多种职业。该数据集通过系统地请求ChatGPT,基于职业、责任、主题和问题层次化组织查询,确保全面覆盖职业专业查询。与常用的数据集(如Dolly、ShareGPT和WizardLM)相比,OccuQuest在职业分布上更为均衡。此外,数据集还包括三个测试集,用于全面评估模型性能。通过微调LLaMA模型,得到的OccuLLaMA在专业问题上显著优于现有的LLaMA变体。数据集和模型均已公开发布。
OccuQuest is a dataset aimed at mitigating occupational bias in large language models. It contains over 110,000 prompt-completion pairs and more than 30,000 dialogues, covering over 1,000 occupations across 26 occupational categories. The dataset systematically queries ChatGPT by hierarchically structuring queries based on occupation, responsibilities, topics and question levels, ensuring comprehensive coverage of professional occupational inquiries. Compared with commonly used datasets such as Dolly, ShareGPT and WizardLM, OccuQuest features a more balanced occupational distribution. In addition, the dataset includes three test sets for thorough evaluation of model performance. After fine-tuning the LLaMA model, the resulting OccuLLaMA significantly outperforms existing LLaMA variants on professional questions. Both the dataset and the model have been publicly released.
数据集概述
名称: OccuQuest: Mitigating Occupational Bias for Inclusive Large Language Models
目的: 该数据集旨在减轻职业偏见,促进大型语言模型的包容性。