sudoku
收藏资源简介:
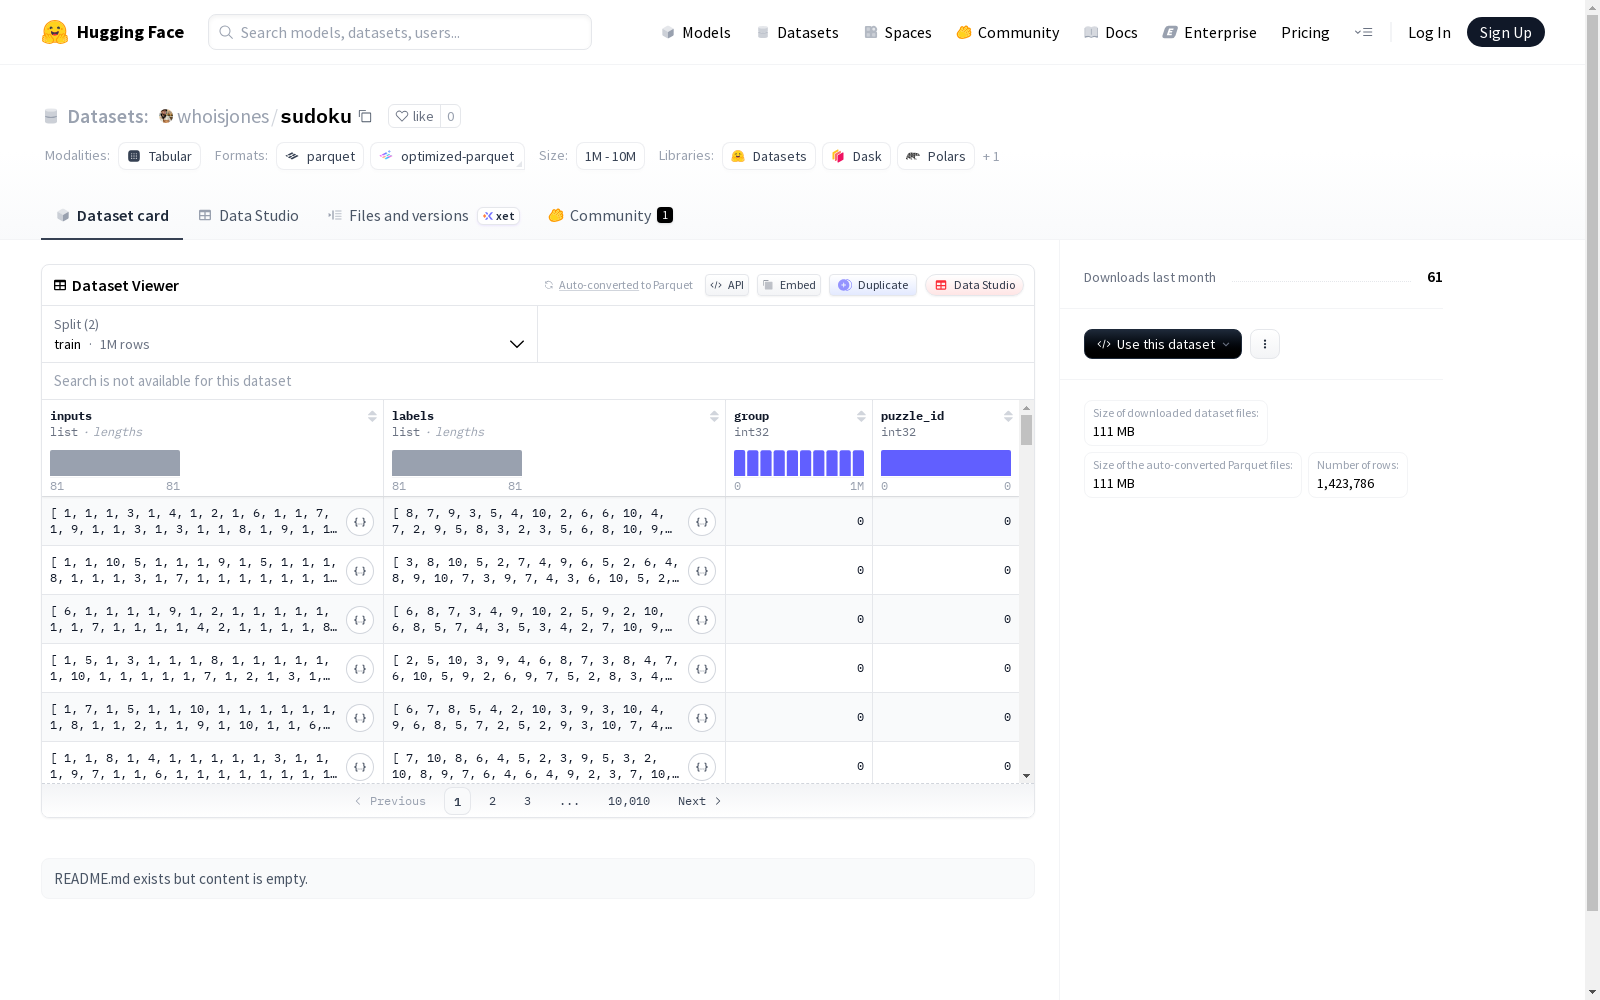
该数据集包含结构化特征数据,主要用于序列处理或分类任务。数据特征包括:inputs(int64列表)、labels(int64列表)、group(int32整数组标识)和puzzle_id(int32唯一标识)。数据集划分为训练集(1,001,000个样本)和测试集(422,786个样本),总大小约1.87GB。数据文件按split分组存储,训练集路径为data/train-*,测试集路径为data/test-*。该数据结构适用于需要序列输入输出映射的任务,如序列标注、多分类预测等场景。
This dataset contains structured feature data, primarily designed for sequence processing or classification tasks. The data features include: inputs (int64 list), labels (int64 list), group (int32 integer array identifier), and puzzle_id (int32 unique identifier). The dataset is split into a training set (1,001,000 samples) and a test set (422,786 samples), with a total size of approximately 1.87 GB. The data files are stored grouped by split: the training set files are located at data/train-*, and the test set files are at data/test-*. This data structure is suitable for tasks requiring sequence input-output mapping, such as sequence labeling, multi-class prediction, and other similar scenarios.