PleIAs/Czech-PD
收藏资源简介:
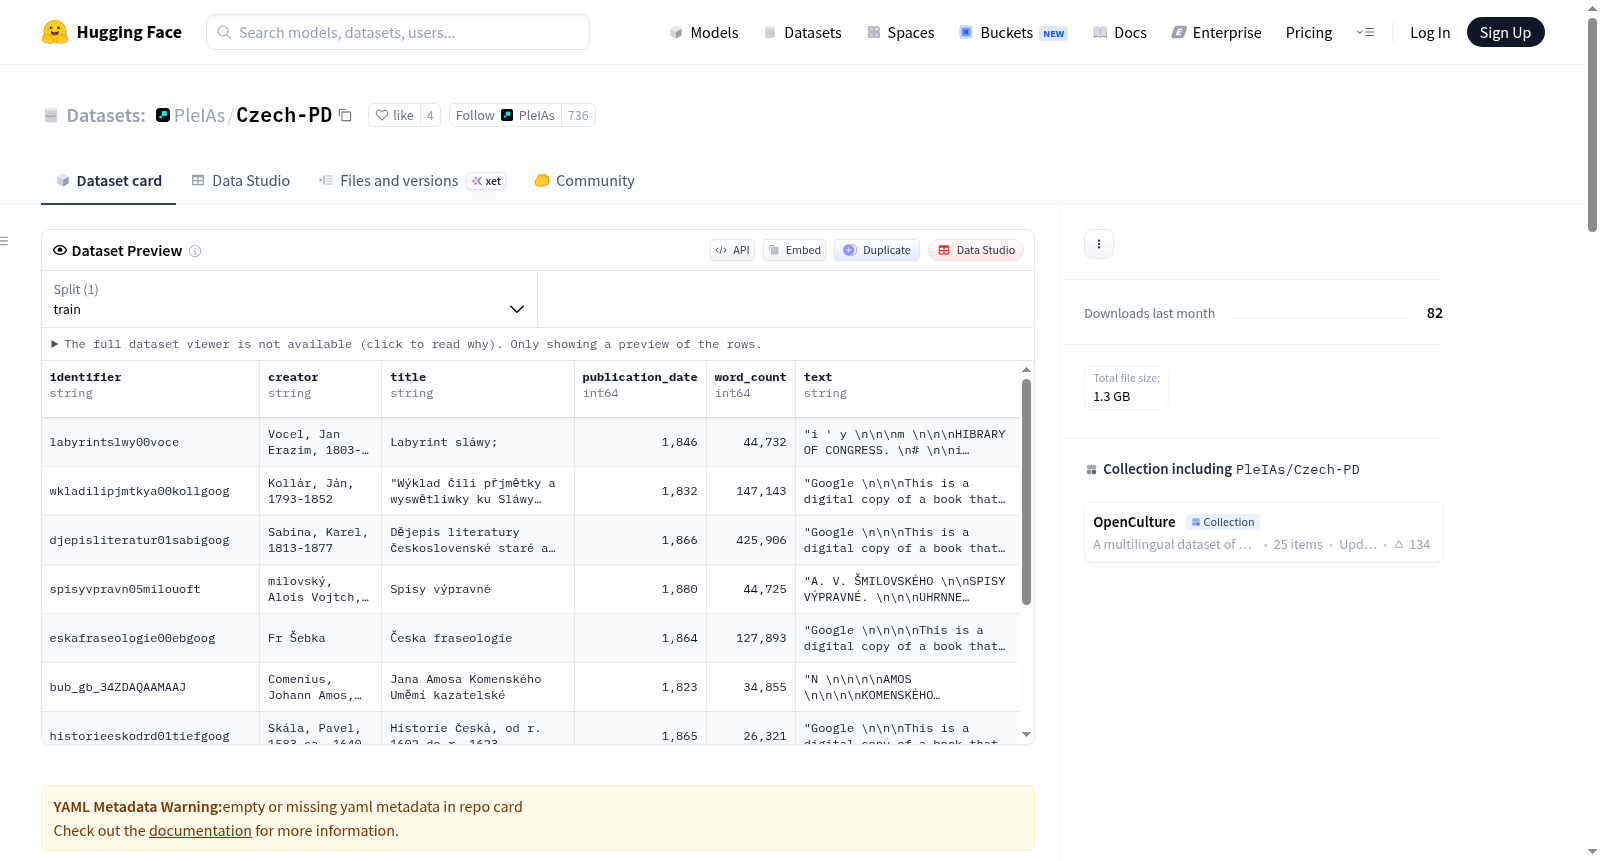
Czech-Public Domain(捷克公共领域)是一个大规模的捷克语文献集合,旨在汇集所有属于公共领域的捷克专著和期刊。截至2024年3月,它是最大的捷克语开放语料库。该集合包含1585个独立标题,总计259,435,959个单词,来源于多个资源,如Internet Archive和欧洲各国图书馆及文化遗产机构。每个parquet文件包含随机选择的2000本书的全文。数据集的构建遵循欧盟公共领域作品的标准,特别是针对作者去世超过70年的作品。数据集目前仅包含1884年之前出版的文献,未来计划扩展到19世纪末和20世纪初的出版物。数据集的主要用途是扩展开放作品的可获得性,用于大型语言模型的训练,并且可以无限制地重新发布以支持研究的可重复性。数据集完全属于公共领域,不受版权限制。未来工作包括扩展数据集、修正OCR错误以及改进文本结构。
Czech-Public Domain is a large-scale Czech language literary collection aimed at aggregating all Czech monographs and periodicals that fall into the public domain. As of March 2024, it is the largest Czech-language open corpus. The collection includes 1585 individual titles, totaling 259,435,959 words, sourced from multiple resources such as the Internet Archive, national libraries and cultural heritage institutions across Europe. Each parquet file contains the full texts of 2000 randomly selected books. The dataset is constructed in compliance with the standards for public domain works set by the European Union, particularly for works whose authors have been deceased for over 70 years. Currently, the dataset only includes literature published prior to 1884, with future plans to expand coverage to publications from the late 19th and early 20th centuries. Its core applications include expanding the availability of open works, training large language models (LLMs), and enabling unrestricted republication to support research reproducibility. The entire dataset is fully in the public domain and free of copyright restrictions. Future work will include expanding the dataset, correcting OCR errors, and improving text structures.
数据集概述
数据集名称
Czech-Public Domain 或 Czech-PD
数据集描述
该数据集旨在聚合所有捷克公共领域的专著和期刊,是截至2024年3月最大的捷克开放语料库。包含1585个独立标题,总计259,435,959字,来源于多个资源,包括Internet Archive和多个欧洲国家图书馆及文化遗产机构。每个parquet文件包含随机选择的2,000本书的全文。
数据集组成
数据集的组成遵循欧盟及Berne国家对公共领域作品的标准,即作者去世超过70年的出版物。截至2024年3月,为简化权利验证,仅保留1884年前的出版物。未来将扩展至19世纪末和20世纪初的出版物。
数据集用途
主要用于大型语言模型的训练,文本可无限制地用于模型训练和再发布,以促进可重复性。
许可证
整个数据集在全球范围内属于公共领域,意味着每个个体或集体版权持有者的遗产权利已过期。
未来工作
- 扩展数据集至19世纪末和20世纪初的作品,并进一步增强来自欧洲文化遗产数据存储库的未开发收藏。
- 修正文本中的计算机生成错误,所有文本通过光学字符识别(OCR)软件自动转录。
- 增强原始文本的结构/编辑呈现,以适应大规模分析或模型训练。