synthetic_speech_da
收藏资源简介:
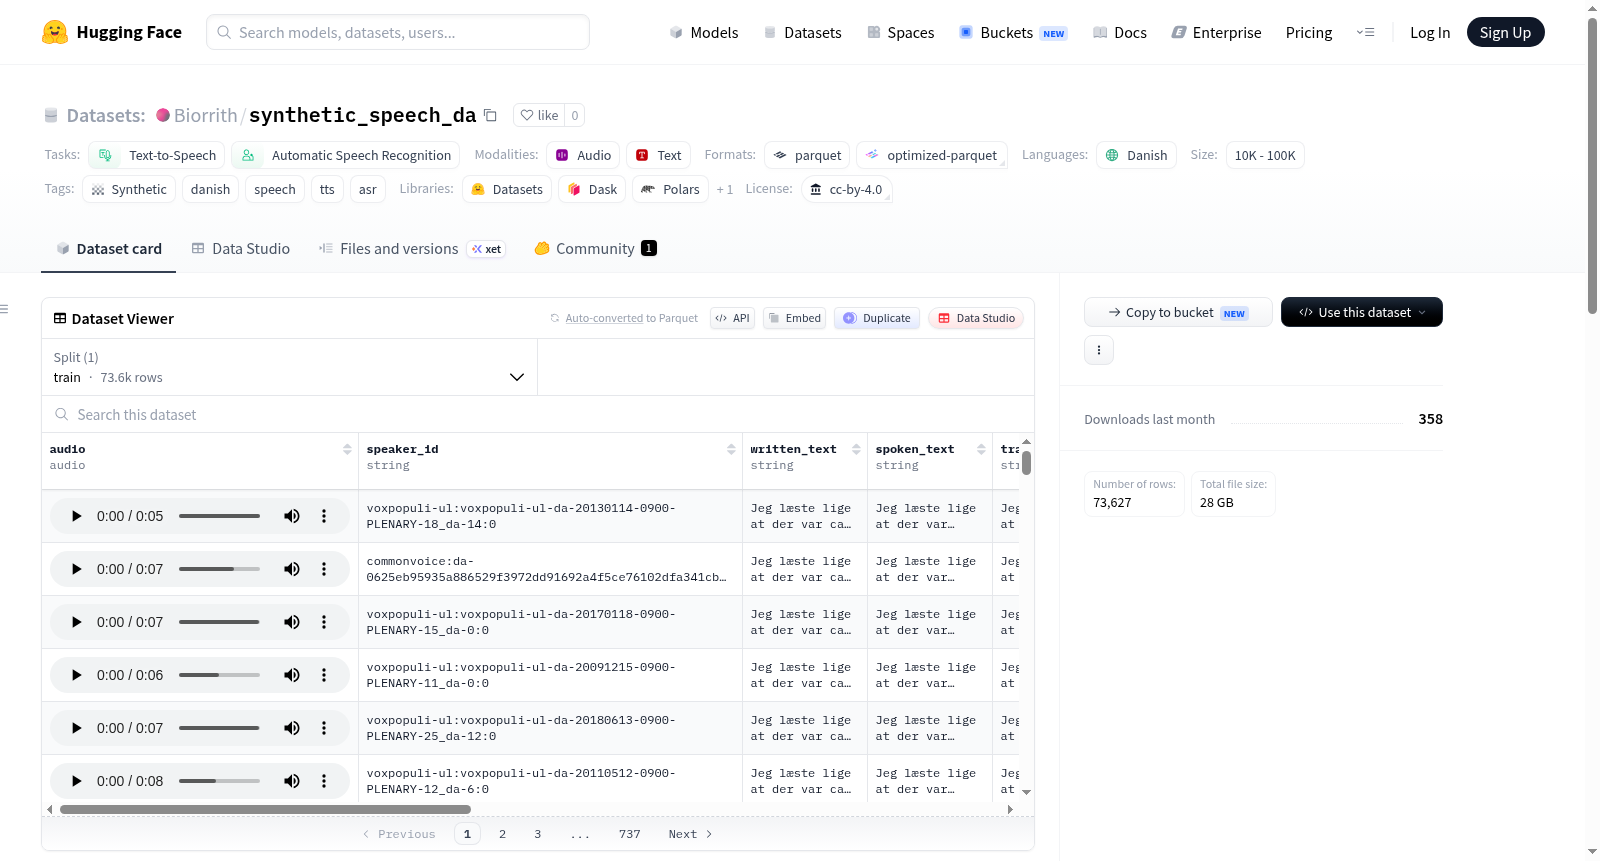
Synthetic Danish Speech 是一个丹麦语合成语音数据集,专门为文本转语音(TTS)和自动语音识别(ASR)任务的预训练提供基准数据。数据集包含69,868个合成语音片段,总时长为320.6小时。所有音频通过丹麦TTS微调模型克隆经过许可审核的参考声音生成,并经过ASR模型的严格质量验证,确保字符错误率(CER)不超过0.10、通过语音活动检测和时长检查、无循环重复和严重削波失真。数据集按参考声音来源细分:voxpopuli-ul贡献310.1小时,yodas贡献7.2小时,commonvoice贡献1.9小时,fleurs贡献1.4小时,所有参考声音均为丹麦语。数据集包含13个字段,如音频(24kHz单声道FLAC格式)、说话人ID、书面文本(非规范化)、口语文本(规范化)、转录和转录形式、文本特征标签(JSON格式)、声音来源、许可证、语言、时长、CER和WER、TTS模型和生成参数、样本哈希。适用于丹麦语TTS模型训练、ASR模型预训练、多说话人语音合成研究和合成语音质量评估。音频为合成生成,参考声音来自允许语音合成的许可来源,数据集在CC-BY-4.0许可证下发布。转录文本是源语料库的原始文本,非人工转录。
Synthetic Danish Speech is a Danish synthetic speech dataset specifically designed to provide benchmark data for pre-training in text-to-speech (TTS) and automatic speech recognition (ASR) tasks. The dataset contains 69,868 synthetic speech segments with a total duration of 320.6 hours. All audio is generated by cloning licensed reference voices using a Danish TTS fine-tuned model and undergoes rigorous quality validation via an ASR model, ensuring a character error rate (CER) not exceeding 0.10, passing voice activity detection and duration checks, and having no loop repetitions or severe clipping distortion. The dataset is subdivided by reference voice source: voxpopuli-ul contributes 310.1 hours, yodas 7.2 hours, commonvoice 1.9 hours, and fleurs 1.4 hours, all reference voices are in Danish. It includes 13 fields, such as audio (24kHz mono FLAC format), speaker ID, written text (non-normalized), spoken text (normalized), transcript and transcript form, text feature labels (JSON format), voice source, license, language, duration, CER and WER, TTS model and generation parameters, and sample hash. It is suitable for Danish TTS model training, ASR model pre-training, multi-speaker speech synthesis research, and synthetic speech quality evaluation. The audio is synthetically generated, with reference voices sourced from licensed origins permitting speech synthesis, and the dataset is released under the CC-BY-4.0 license. The transcript text is the original text from the source corpus, not manually transcribed.
数据集概述:Synthetic Danish Speech
数据集名称:Synthetic Danish Speech
标识符:Biorrith/synthetic_speech_da
许可证:CC-BY-4.0
语言:丹麦语(da)
任务类别:文本转语音(TTS)、自动语音识别(ASR)
数据集规模
- 音频片段总数:73,627 条
- 总语音时长:339.5 小时
- 各参考语音来源时长分布:
- VoxPopuli (ul):328.3 小时
- YODAS:7.8 小时
- Common Voice:2.0 小时
- FLEURS:1.4 小时
- 参考语音语言:全部为丹麦语(da),共 339.5 小时
数据生成与质量控制
- 所有语音为合成语音,由丹麦语 TTS 微调模型(
coral-chatterbox)生成,克隆了经许可证审核的参考语音。 - 使用 ASR 模型
syvai/hviske-v5.3进行质量验证。 - 通过全部质量门控的片段才被收录:
- 字符错误率(CER)≤ 0.10(相对口语文本)
- 通过了 VAD(语音活动检测)与时长校验
- 无循环重复或严重截断
数据列说明
| 列名 | 说明 |
|---|---|
audio |
24 kHz 单声道 FLAC 格式音频 |
speaker_id |
克隆参考语音的身份标识(可用于按说话人划分数据) |
written_text |
非归一化文本(保留数字/缩写,如 121、kg) |
spoken_text |
归一化文本(数字/缩写已拼写),为实际输入 TTS 并被朗读的内容,用于计算 CER/WER |
transcript / transcript_form |
数据集标注:80% 为书面形式,20% 为口语形式;transcript_form 记录具体形式 |
features |
JSON 标签(数字/缩写/专有名词/疑问/感叹) |
voice_source、voice_license、lang |
克隆参考语音的来源、许可证、语言 |
duration_s、cer、wer |
音频时长及验证分数 |
tts_model、gen_params |
合成模型 ID 及生成参数(JSON) |
sample_hash |
由 (spoken_text, voice, params) 生成的稳定唯一标识 |
许可证与归属
- 参考语音仅从获准用于语音合成的来源选取。
- 需归因的来源(CC-BY):
- FLEURS (
google/fleurs,da_dk) — CC-BY-4.0 - YODAS (
espnet/yodas-granary) — CC-BY-3.0
- FLEURS (
- 无需归因的来源(CC0 / 公共领域):
- VoxPopuli 未标注数据、Common Voice 17、LibriVox
- 整体数据集以 CC-BY-4.0 许可证发布。
- 转录文本来源于原始语料文本,非人工对合成音频的转写。