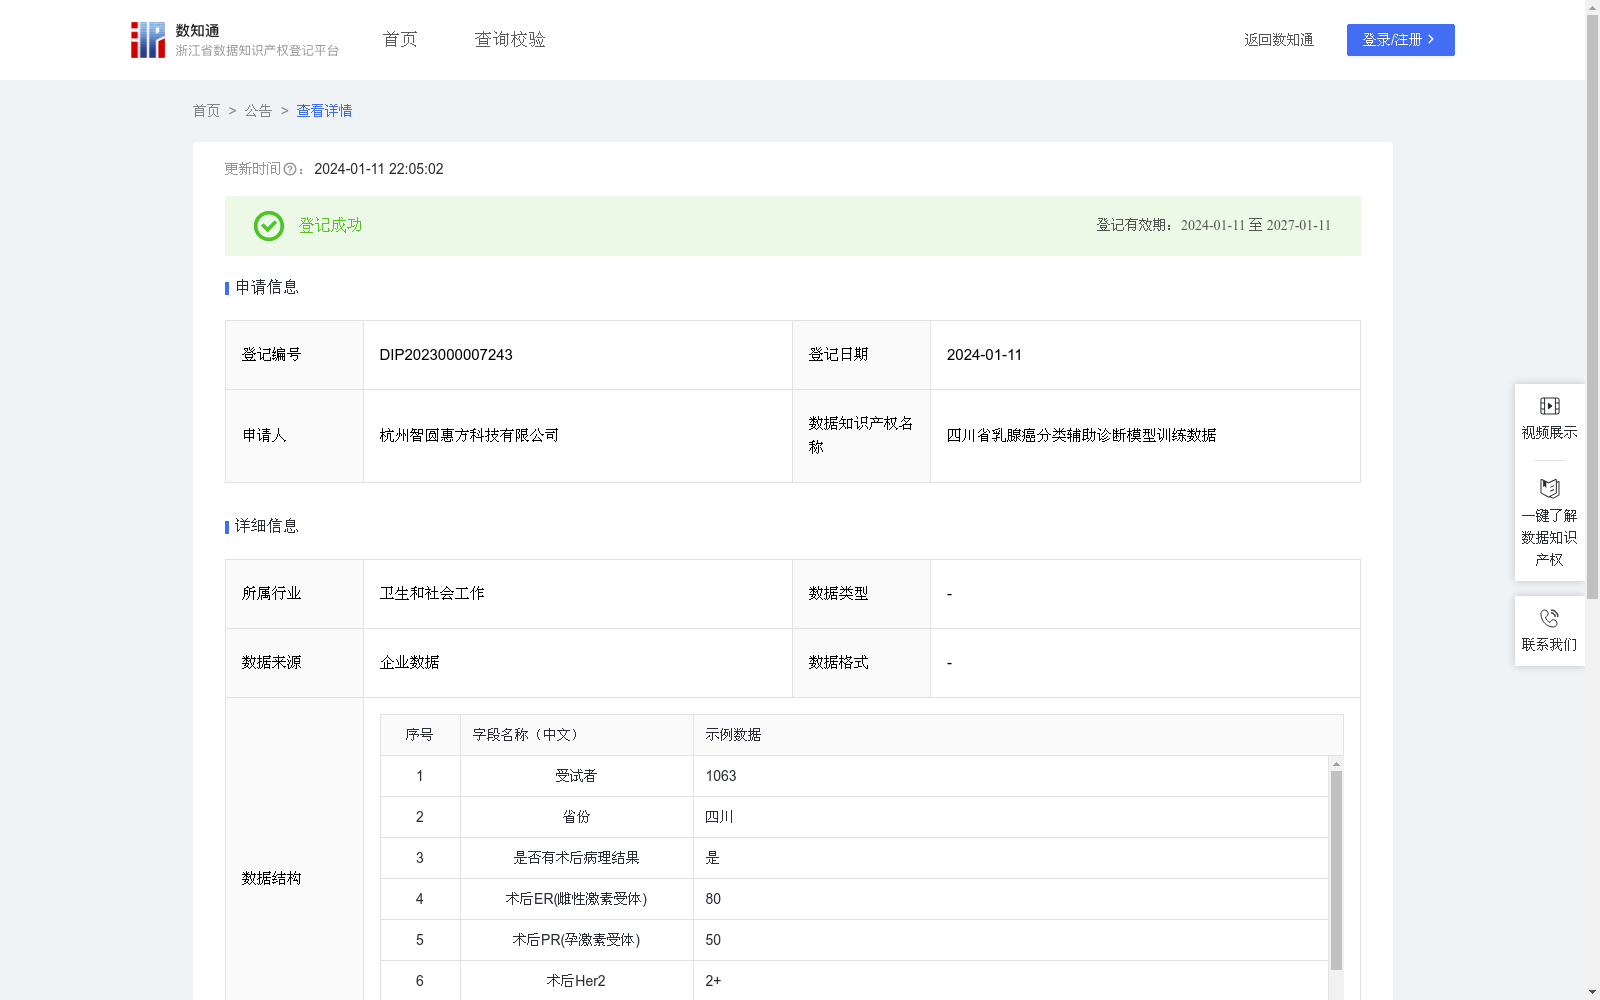
四川省乳腺癌分类辅助诊断模型训练数据
收藏资源简介:
通过对样本的数据处理和数据加工,提供给辅助诊断人工智能模型进行训练,帮助人工智能模型更好地理解四川省样本场景下将乳腺癌分型,提取特征,发现规律,最终提高诊断人工智能模型的准确性、鲁棒性和泛化能力。1数据采集:通过正式合作协议,从医疗机构取得匿名化的样本临床数据,包括是否有术后病理结果、术后ER(雌性激素受体)、术后PR(孕激素受体)、术后Her2情况、术后Fish情况,同时还要获取系统内术后Her2阴性阳性分型标记;2数据处理:对数据进行检查核对,确保所有数据去标志化,处于完全匿名化状态且不可还原的状态,将没有病理结果的数据去除,对异常数据进行清洗去除,对部分缺失数据进行生成式补充;3数据加工:基于原始数据和算法规则,生成乳腺癌分类标记,具体判规则为:如果ER满足阳性,同时PR满足阳性,同时HER-2满足阴性,则标记为Luminal型,反之则标记为其他类型。
This dataset is processed and curated from sample data for training auxiliary diagnostic AI models. The goal is to enable the AI models to better perform breast cancer subtyping in the sample scenarios of Sichuan Province, extract features, and uncover underlying patterns, thereby ultimately improving the accuracy, robustness, and generalization ability of the diagnostic AI models. 1. Data Collection: Via formal cooperative agreements, anonymized clinical sample data is acquired from medical institutions, including postoperative pathological results, postoperative ER (Estrogen Receptor) status, postoperative PR (Progesterone Receptor) status, postoperative Her2 status, postoperative FISH results, as well as the in-system post-operative Her2 negative/positive subtyping labels. 2. Data Processing: Data inspection and verification are conducted to ensure all data is de-identified, fully anonymized and irreversibly non-recoverable. Data without pathological results are removed, abnormal data is cleaned and eliminated, and generative supplementation is performed for partially missing data. 3. Data Curation: Breast cancer classification labels are generated based on the original data and algorithmic rules. The specific judgment criteria are as follows: If ER is positive, PR is positive, and HER-2 is negative, the sample is labeled as Luminal subtype; otherwise, it is labeled as other subtypes.