
glaiveai/RAG-v1
收藏官方服务:
资源简介:
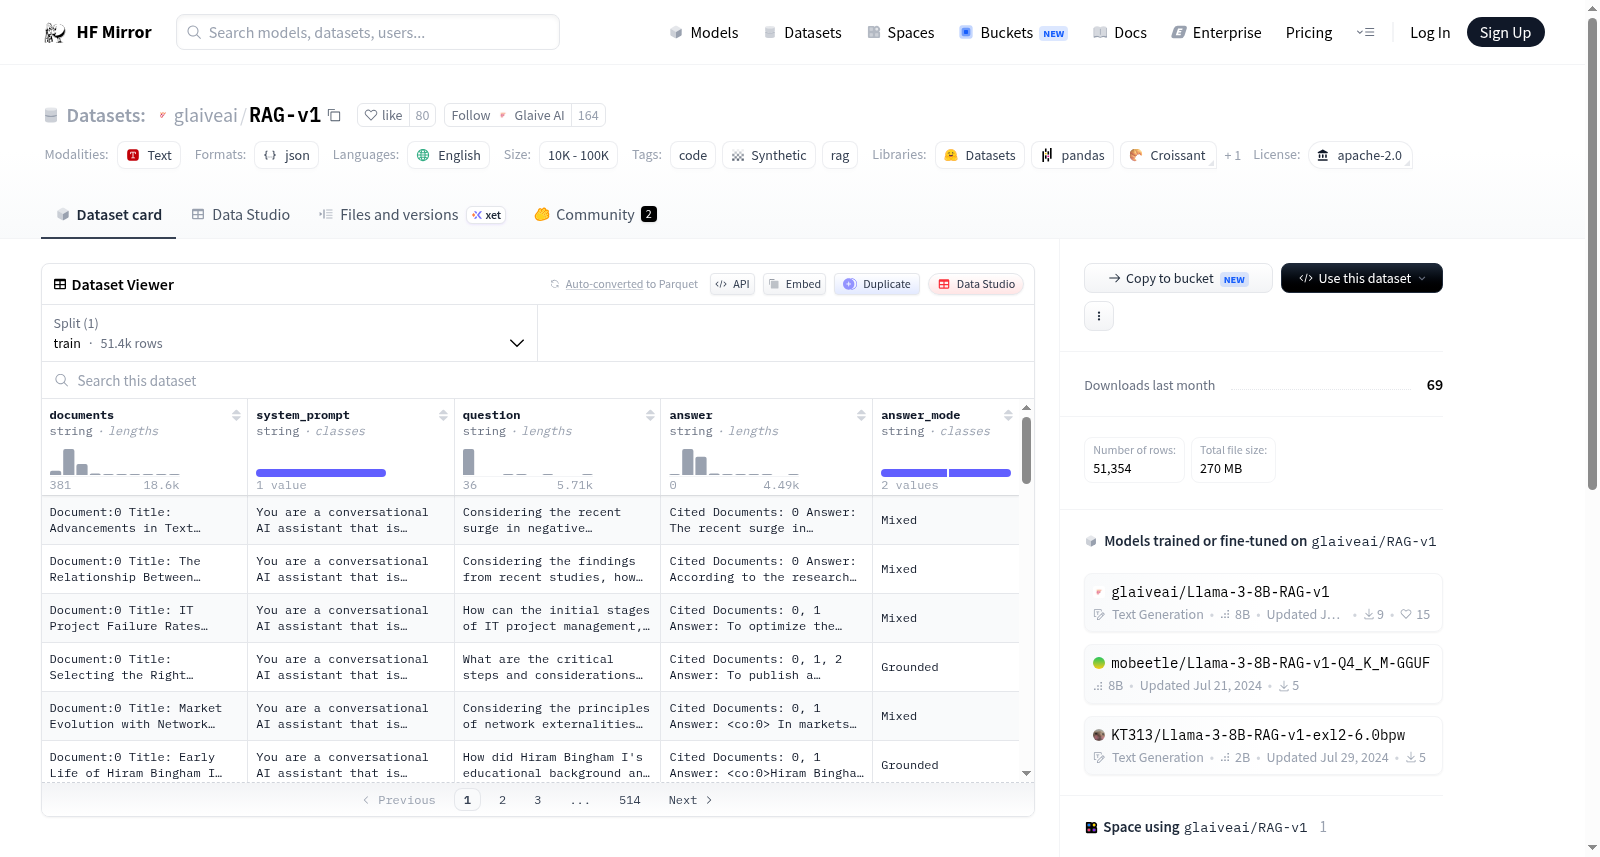
Glaive-RAG-v1是一个包含约50,000个样本的数据集,使用Glaive平台构建,用于微调模型以适应RAG(检索增强生成)应用场景。每个样本包括上下文文档列表、问题、回答模式和回答。回答模式定义了模型是否应仅输出基于文档的回答,还是应结合其内部信息。回答中引用了文档,并使用特定标签标记引用。
Glaive-RAG-v1 is a dataset with ~50k samples built using the Glaive platform, for finetuning models for RAG use cases. Each row has a list of documents for context, a question, an answer mode, and an answer. The answer mode defines if the model should output only grounded responses or if it should combine its internal information as well. The answers include cited documents at the beginning and also <co: 1></co> tags in the text to mark citations.
提供机构:
glaiveai原始信息汇总
Glaive-RAG-v1 数据集概述
基本信息
- 许可证: Apache-2.0
- 数据规模: 10K < n < 100K
- 标签:
- code
- synthetic
- rag
- 语言: 英语 (en)
数据集描述
- 样本数量: 约50,000个
- 构建平台: Glaive
- 应用场景: 用于微调模型以适应RAG(Retrieval-Augmented Generation)用例
数据结构
- 每行数据包含:
- 上下文文档列表
- 问题
- 回答模式
- 答案
- 回答模式: 定义模型是否应仅输出基于上下文的回答,或结合内部信息生成回答
- 答案格式:
- 开头包含引用的文档
- 文本中包含
<co: 1></co>标签标记引用
搜集汇总
数据集介绍
背景与挑战
背景概述
Glaive-RAG-v1是一个包含约5.1万条样本的合成数据集,专门设计用于微调模型以支持检索增强生成(RAG)应用。该数据集以JSON格式组织,每条数据包含文档列表、问题、答案模式('Grounded'或'Mixed')以及带有明确文档引用的答案,旨在训练模型根据提供的文档生成基于事实或混合知识的响应。
以上内容由遇见数据集搜集并总结生成


