Ablated Datasets 和 Semi-Synthetic dataset
收藏资源简介:
我们提出了消融数据集来测试模型在某些文字信息或关系信息从数据集中移除时的性能,以评估文字信息的重要性。消融数据集是从现有的包含文字的链接预测数据集创建的。我们还提出了半合成数据集来测试模型在需要理解实体的文字值以做出正确预测时的性能。
We propose an ablation dataset to evaluate the importance of textual information by testing model performance when certain textual or relational information is removed from the dataset. This ablation dataset is constructed from existing text-containing link prediction datasets. We also propose a semi-synthetic dataset to test model performance when the model needs to comprehend the textual values of entities to generate correct predictions.
数据集概述
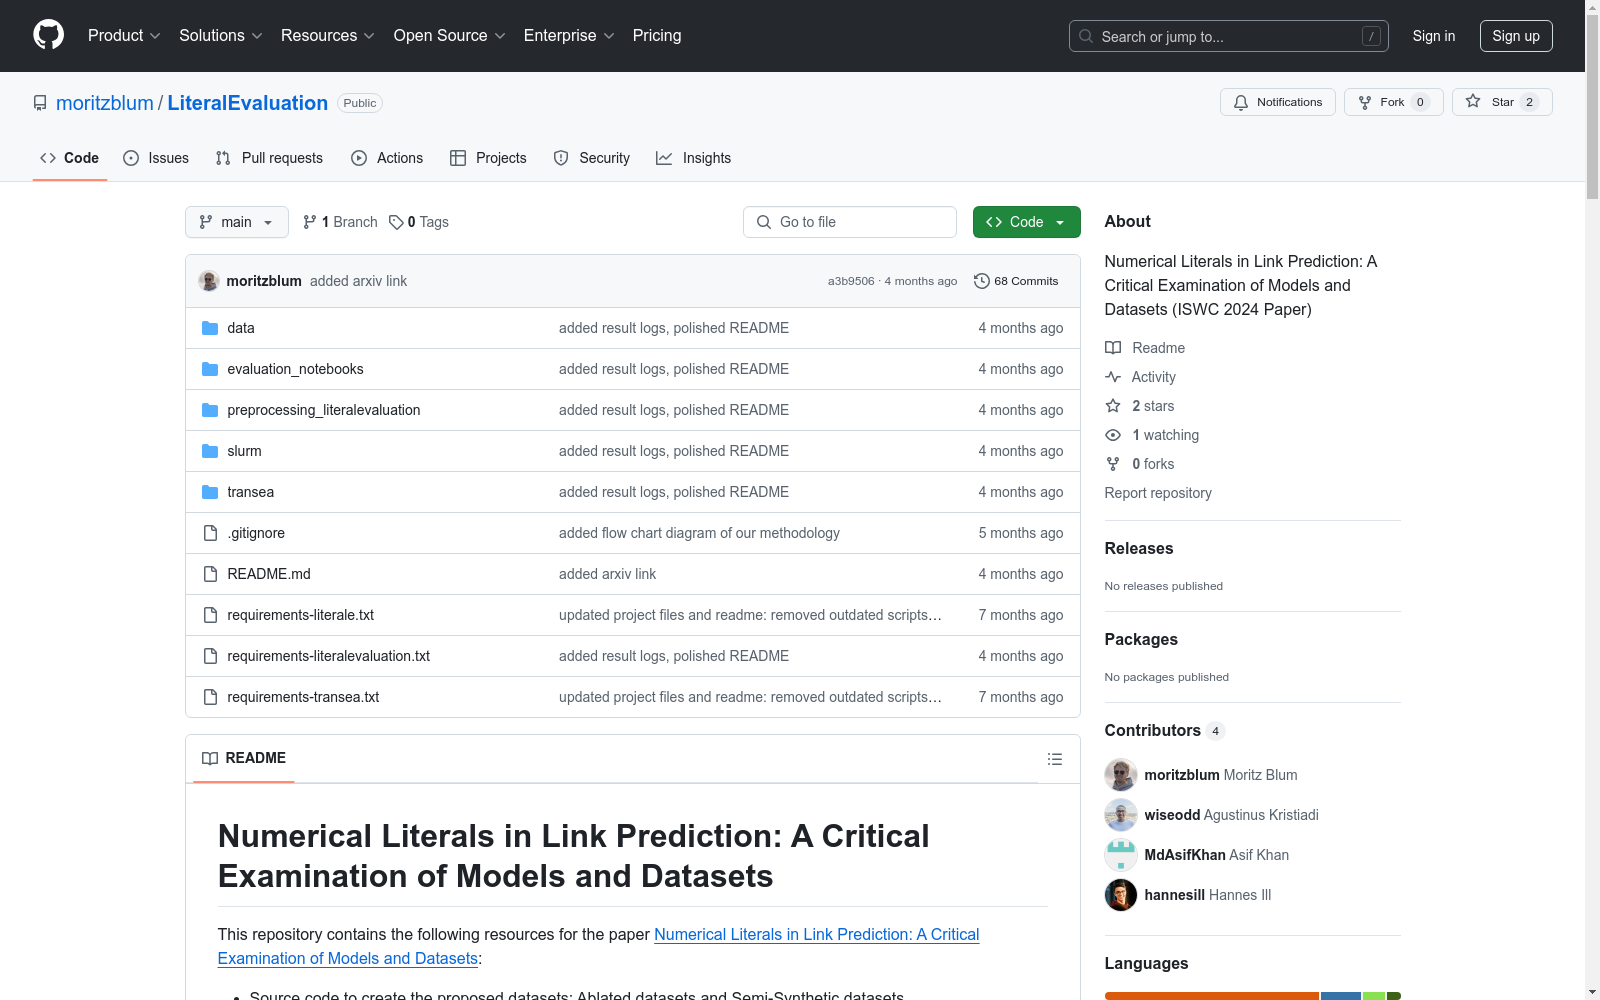
本仓库包含以下资源,用于论文《Numerical Literals in Link Prediction: A Critical Examination of Models and Datasets》:
- 源代码:用于创建提出的数据集,包括Ablated数据集和Semi-Synthetic数据集。(
/preprocessing_literalevaluation) - 评估命令和设置:用于在数据集上评估所调查模型的命令和设置。(
/slurm) - 训练日志:我们在实验期间获得的训练日志。(
/data/results&/data/saved_models) - Jupyter Notebooks:我们用于基于训练日志创建论文中的可视化和表格的Jupyter Notebooks。(
/evaluation_notebooks)
创建数据集
Ablated数据集
我们提出Ablated数据集,以测试模型在移除某些文字信息或关系信息后的性能,评估文字信息的重要性。Ablated数据集是从现有的包含文字的链接预测数据集中创建的。所有消融策略在论文中都有描述。
创建Ablated数据集的命令如下: shell python preprocessing_literalevaluation/get_literalevaluation_dataset.py --dataset {FB15k-237, YAGO3-10, LitWD48K} --features {org, rand, attribute} --literal_replacement_mode {sparse, full} --relation_ablation {0..10} --max_num_attributive_relations {1..} --data_dir {data path} --run_id {run id}
例如,创建FB15k-237的Ablated数据集,其中每个实体随机分配所有属性,并且20%的关系三元组被消融,运行以下命令: shell python preprocessing_literalevaluation/get_literalevaluation_dataset.py --dataset FB15k-237 --features "rand" --literal_replacement_mode "full" --relation_ablation 20 --data_dir "data"
新数据集将存储为data/FB15k-237_rand_rel-20_full。
Semi-Synthetic数据集
我们提出Semi-Synthetic数据集,以测试模型在需要理解实体的文字值才能做出正确预测时的性能。我们用于评估的Synthetic数据集是从FB15k-237数据集生成的。
我们提供了Synthetic数据集在data目录中。
如果要重新创建Synthetic数据集,或创建另一个数据集的Semi-Synthetic版本,可以使用以下脚本:
shell
python preprocessing_literalevaluation/get_synthetic_dataset.py --dataset_name {new semi-synthetic dataset name} --dataset {FB15k-237, YAGO3-10, LitWD48K} --class_mapping_file {class mapping file} --relevant_class_label {relevant class label}
例如,基于FB15k-237数据集创建Semi-Synthetic数据集Synthetic,运行以下命令:
shell
python preprocessing_literalevaluation/get_synthetic_dataset.py --dataset_name Synthetic --dataset "FB15k-237" --class_mapping_file "data/FB15k-237/FB15k-237_class_mapping.csv" --relevant_class_label "human"
重新创建评估
LiteralE
设置literale conda环境并评估数据集的步骤如下:
shell
conda create --name literale python=3.6.13
pip install -r requirements-literale.txt
conda activate literale
git clone git@github.com:SmartDataAnalytics/LiteralE.git
cd LiteralE
将数据集放置在data目录中并预处理数据集以进行评估。使用占位符[eval-datadet]表示数据集。
mkdir saved_modelspython wrangle_KG.py [eval-datadet]python preprocess_kg.py --dataset [eval-datadet]- 连续运行以下命令预处理属性数据:
- 创建词汇文件:
python main_literal.py dataset [eval-datadet] epochs 0 process True - 数值文字:
python preprocess_num_lit.py --dataset [eval-datadet]
- 创建词汇文件:
然后可以训练模型: shell python main_literal.py dataset [eval-datadet] model {DistMult, ComplEx} input_drop 0.2 embedding_dim 100 batch_size 128 epochs 100 lr 0.001 process True
TransEA
设置transea conda环境并训练模型的步骤如下:
shell
conda create --name transea python=3.10
pip install -r requirements-transea.txt
conda activate transea
然后可以训练模型: shell python transea/main_transea.py --model transea --dataset [eval-datadet] --alpha 0.3 --lr 0.001 --hidden 100 --saved_models_path="./saved_models"
KGA
设置kga conda环境并应用文字变换和训练模型的步骤如下:
shell
conda create --name kga python=3.8
conda activate kga
pip install torch
pip install numpy
pip install pandas
git clone git@github.com:Otamio/KGA.git
cd KGA
然后可以应用文字变换并训练模型: shell python augment_lp.py --mode "Quantile_Hierarchy" --bins 32 --dataset [eval-datadet] python run.py --dataset [eval-datadet]_QHC_5 --model {distmult, tucker}
重现实验
slurm目录中的脚本包含重现实验的命令。在slurm集群上运行以下脚本:
./slurm/slurm_FB15k-237.sh(LiteralE)./slurm/slurm_LitWD48K.sh(LiteralE)./slurm/slurm_YAGO3-10.sh(LiteralE)./slurm/slurm_Synthetic.sh(LiteralE)./slurm/slurm_TransEA.sh(TransEA)./slurm/slurm_KGA.sh(KGA)
可视化结果
可以使用evaluation_notebooks目录中的Jupyter Notebooks可视化结果:
evaluation_notebooks/evaluate_ablations.ipynb- 绘制结果并创建所有消融实验的Latex表格。evaluation_notebooks/evaluate_synthetic.ipynb- 实现Acc指标,绘制结果并创建Semi-Synthetic数据集实验的Latex表格。
引用
如果您在工作中使用了我们的评估数据集,请引用我们的论文: plaintext @inproceedings{mblum-etal-2024-literalevaluation, title = "Numerical Literals in Link Prediction: A Critical Examination of Models and Datasets", author = "Blum, Moritz and Ell, Basil and Ill, Hannes and Cimiano, Philipp", booktitle = "Proceedings of the 23rd International Semantic Web Conference (ISWC 2024)", month = November, year = "2024" }