ULVR-Bench
收藏资源简介:
ULVR-Bench(通用潜在视觉推理基准)是一个用于评估模型视觉推理能力的多模态基准数据集。它包含18,218个样本,根据中间视觉推理类型划分为7个独立的数据分割:text_reasoning、bbox_reasoning、scene_graph_reasoning、visual_repr_reasoning、helper_reasoning、chart_reasoning和doc_reasoning。每个样本包括输入图像、自然语言问题和最终答案真值,并提供中间状态真值(如文本、JSON或图像)。数据集遵循统一模式,主要字段包括样本唯一标识、推理类型、问题、答案真值、输入图像、中间状态类型和中间状态真值。所有样本来自知名数据集的公开测试或验证分割,确保与训练数据无重叠,旨在为视觉问答和复杂视觉推理任务提供一个全面、无偏的评估基准。核心评估指标仅为最终答案的准确率。
ULVR-Bench (Universal Latent Visual Reasoning Benchmark) is a multimodal benchmark dataset for evaluating model visual reasoning capabilities. It contains 18,218 samples, divided into 7 independent data splits based on the intermediate visual reasoning types: text_reasoning, bbox_reasoning, scene_graph_reasoning, visual_repr_reasoning, helper_reasoning, chart_reasoning, and doc_reasoning. Each sample includes an input image, a natural language question, and the corresponding ground truth final answer, with intermediate state ground truths (e.g., text, JSON, or images) provided. The dataset follows a unified schema, with key fields such as sample unique identifier, reasoning type, question, answer ground truth, input image, intermediate state type, and intermediate state ground truth. All samples are sourced from public test or validation splits of well-known datasets, ensuring no overlap with training data, and aim to provide a comprehensive, unbiased evaluation benchmark for visual question answering and complex visual reasoning tasks. The core evaluation metric is solely the accuracy of the final answer.
数据集概述:ULVR-Bench
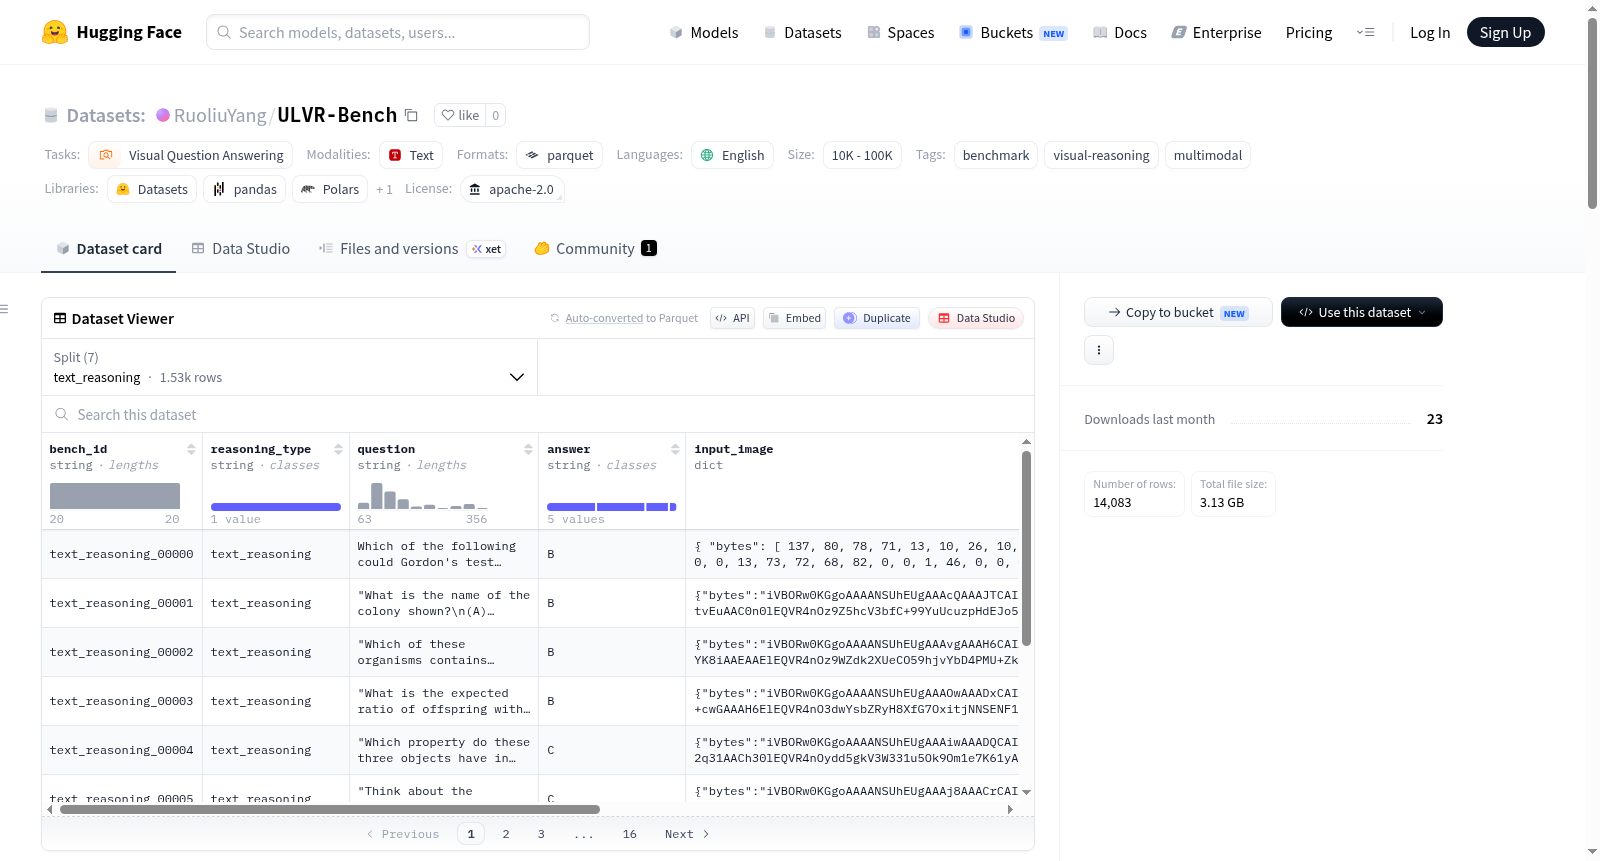
ULVR-Bench 是一个用于评估多模态模型通用潜在视觉推理能力的基准测试数据集,包含 14,083 个样本,涵盖 7 种不同的推理类型。
- 语言:英语
- 许可证:Apache-2.0
- 任务类别:视觉问答
- 数据集大小:10K < n < 100K
数据集结构
数据集包含 7 个独立的分片(Split),每个分片对应一种推理类型,并可在 Hugging Face 上通过 load_dataset 按分片名称加载。
| 分片名称 | 样本数 | 数据来源 | 中间状态 GT | 答案 GT |
|---|---|---|---|---|
| text_reasoning | 1,526 | ScienceQA 测试集 | ✅ 讲义与解题文本 | ✅ |
| bbox_reasoning | 910 | GQA val_balanced | ✅ 场景图生成的边界框 JSON | ✅ |
| scene_graph_reasoning | 3,707 | GQA val_balanced | ✅ 完整场景图 JSON | ✅ |
| visual_repr_reasoning | 587 | GQA val_balanced | ✅ 3 张辅助图像:深度图、边缘图、分割图 | ✅ |
| helper_reasoning | 88 | GeoQAPlus-StepbyStep 测试集(严格辅助线子集) | ✅ 中文解题过程描述辅助线构造 | ✅ (A/B/C/D) |
| chart_reasoning | 2,375 | ChartQA 测试集 | ⏳ 待手动标注的区域坐标 | ✅ |
| doc_reasoning | 4,890 | DocVQA 验证集 | ⏳ 待手动标注的区域坐标 | ✅ |
数据清洗与质量审核
- 原始数据集包含 18,218 个样本,经过启发式过滤和人工抽样审核后,移除了 4,135 个(22.7%) 低质量样本。
- 具体过滤规则和已知限制记录在
BENCH_QUALITY_AUDIT.md文件中(本地副本)。
数据模式(Schema)
每个样本包含以下字段:
bench_id: 字符串,例如 "bbox_reasoning_00042"reasoning_type: 字符串question: 字符串answer: 字符串,最终答案 GTinput_image: 字典(bytes, path)intermediate_state_type: 字符串intermediate_state: 字符串/JSON,中间状态 GT;对于 chart/doc 分片为空(待手动标注)intermediate_image: 字典(bytes, path);对于无 GT 图像的分片为 NULLsource: 字符串
特殊说明
- GQA val_balanced 的使用:由于 GQA testdev 没有公开的场景图 GT,无法填充
intermediate_state,因此使用 val_balanced 分片。 - DocVQA 验证集的使用:DocVQA 测试集不公开答案,验证集(5,349 个问题,过滤后 4,890 个)具有
answers字段。 - GeoQAPlus-StepbyStep 子集:通过关键词筛选带有辅助线构造的几何题,共 88 个样本。
- 视觉表征推理:
visual_repr_reasoning分片额外提供三个辅助图像(深度图、边缘图、分割图)。
设计原则
- 模型仅接收
input_image + question,仅根据answer评分。 intermediate_state和intermediate_image是参考 GT,用于分析模型推理过程,不参与评分。- 所有样本均来自公开的测试/验证集,与 ULVR_v2 训练语料无重叠。