lei_15436_500_exemplos
收藏资源简介:
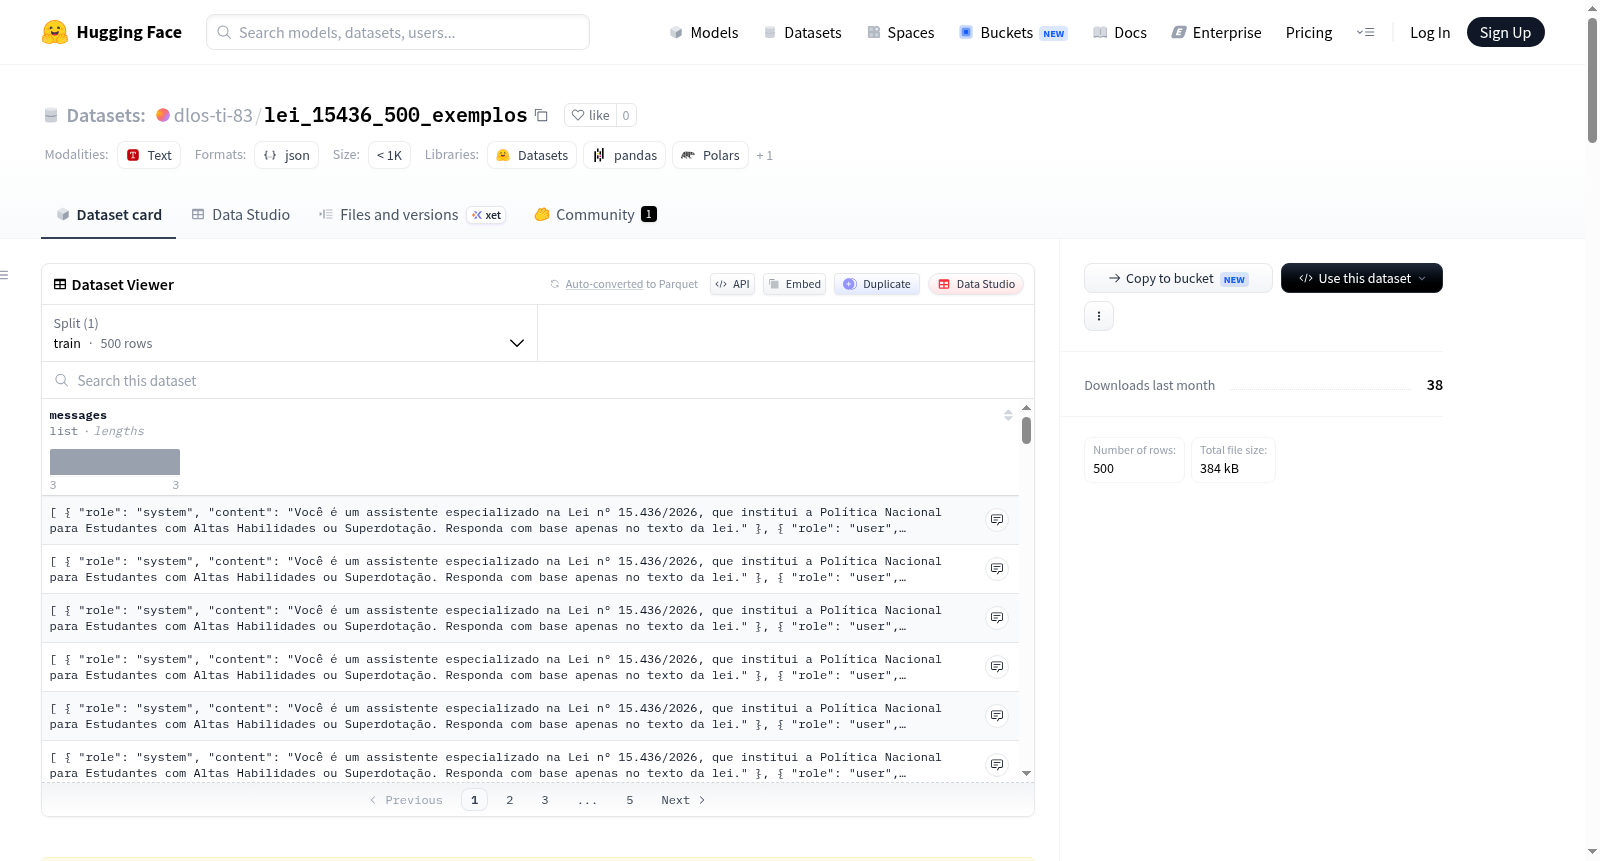
该数据集是一个包含500个合成示例的ChatML格式数据集,源自巴西第15.436/2026号法律(《高能力或天才学生国家政策》)。数据集专为使用Hugging Face的SFTTrainer对语言模型(如LLaMA、Mistral、GPT、Qwen等)进行监督微调(SFT)而创建。所有回答均严格基于法律条文(第1至25条),确保事实准确性和可靠性,不含任何个人或敏感信息。每个数据示例遵循ChatML格式,包含系统提示(定义助手角色)、用户问题以及基于法律条款的助手回答。数据集涵盖了六类主要问题提示,旨在确保多样性和鲁棒性:1) 知识类:涉及法律概念和条款的直接定义、解释和比较;2) 分析类:包括情境分类、信息提取和事实核查;3) 推理类:涉及规则应用、多条款推理和边缘案例处理;4) 决策类:包括决策制定、优先级排序和违规识别;5) 格式遵循类:要求按照特定结构(如要点列表、表格)回答问题;6) 限制认知类:包含礼貌拒绝、澄清请求、不确定性表达和范围界定。数据集在六大类别间分布均匀,每个类别约含83个示例,并进一步均匀覆盖其子类别。该数据集适用于法律信息问答、基于特定文档的模型微调、推理能力评估等任务,是构建专注于巴西高能力/天才学生教育政策领域的专业语言模型助手的理想资源。
This dataset is a ChatML-formatted dataset containing 500 synthetic examples, derived from Brazilian Law No. 15.436/2026 (National Policy for High Ability or Gifted Students). It is specifically created for supervised fine-tuning (SFT) of language models (such as LLaMA, Mistral, GPT, Qwen) using Hugging Faces SFTTrainer. All responses are strictly based on legal provisions (Articles 1 to 25), ensuring factual accuracy and reliability, with no personal or sensitive information included. Each data example follows the ChatML format, comprising a system prompt (defining the assistants role), user questions, and assistant answers based on legal clauses. The dataset covers six main categories of question prompts to ensure diversity and robustness: 1) Knowledge-based: involving direct definitions, explanations, and comparisons of legal concepts and clauses; 2) Analytical: including scenario classification, information extraction, and fact-checking; 3) Reasoning-based: covering rule application, multi-clause reasoning, and edge case handling; 4) Decision-making: involving decision formulation, prioritization, and violation identification; 5) Format-following: requiring answers in specific structures (e.g., bullet points, tables); 6) Limited-cognitive: including polite refusals, clarification requests, uncertainty expression, and scope delimitation. The dataset is evenly distributed across the six categories, with approximately 83 examples per category, and further evenly covers their subcategories. It is suitable for tasks such as legal information Q&A, model fine-tuning based on specific documents, and reasoning ability evaluation, making it an ideal resource for building professional language model assistants focused on the field of Brazilian high-ability/gifted student education policy.