
LLM4Mat-Bench
收藏资源简介:
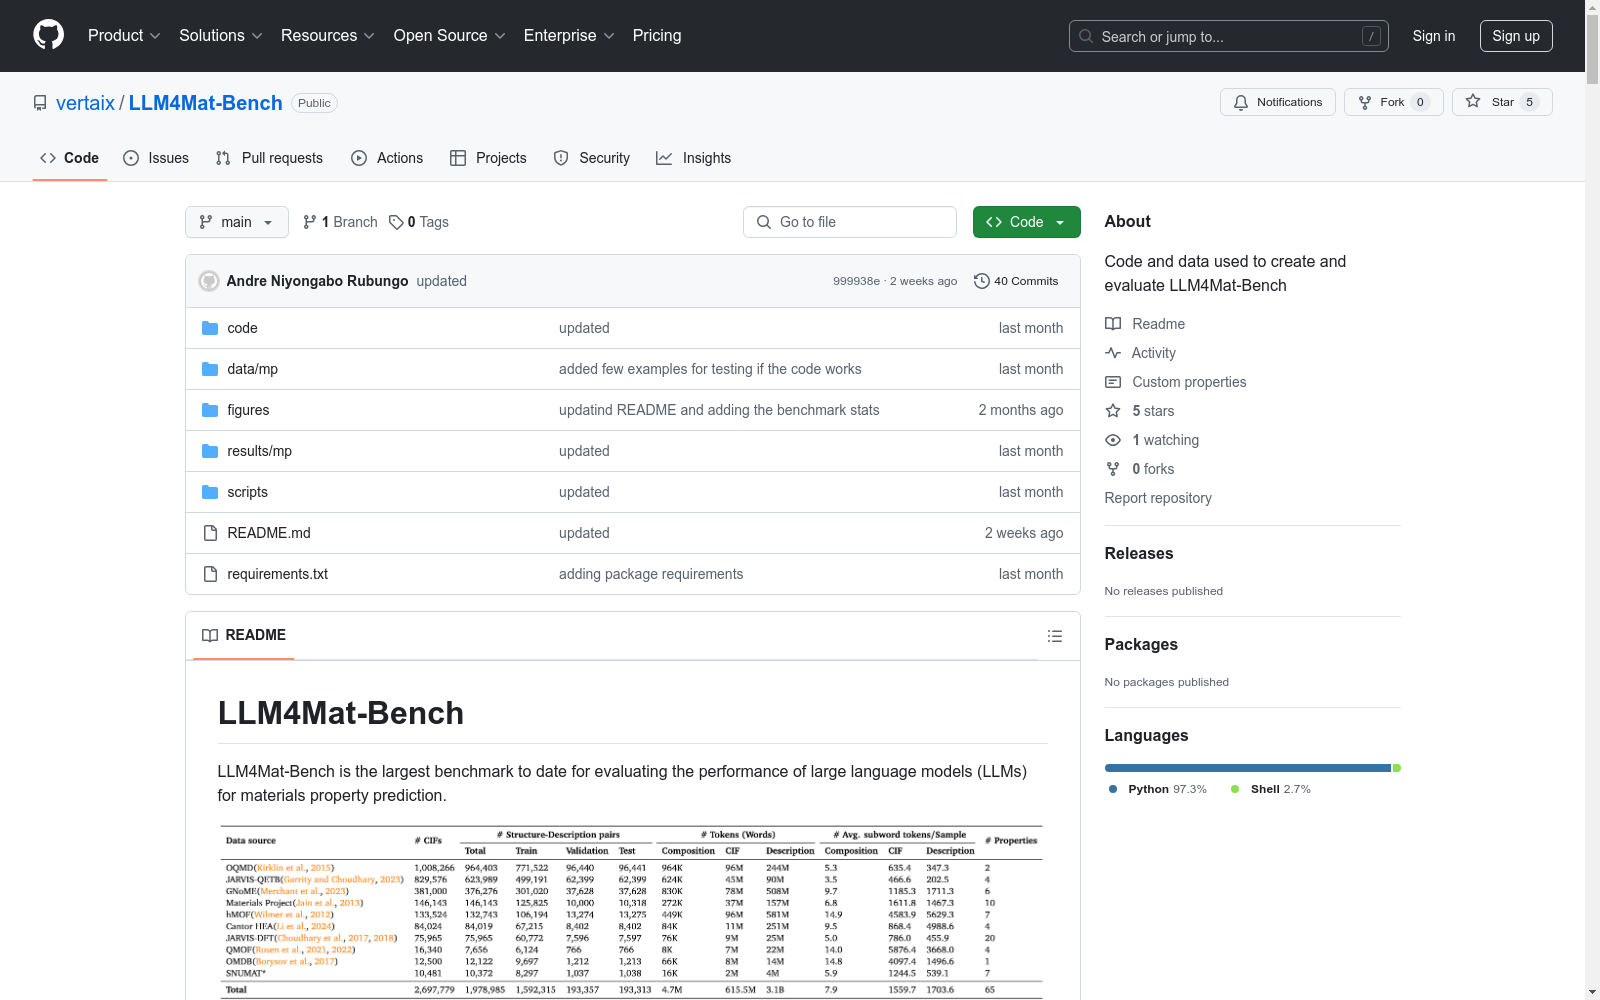
LLM4Mat-Bench是由普林斯顿大学和多伦多大学等机构创建的用于评估大型语言模型在材料属性预测中的性能的数据集。该数据集包含约197万条晶体结构数据,来自10个公开的材料数据源,涵盖45种不同的材料属性。数据集通过多种输入模态(如晶体组成、CIF文件和晶体文本描述)进行描述,总共有4.7M、615.5M和3.1B个tokens。数据集的创建过程包括从多个公开数据库中收集CIF文件和材料属性,并使用Robocrystallographer生成晶体结构的文本描述。LLM4Mat-Bench旨在解决材料科学中的属性预测和材料发现问题,通过提供多样化的材料表示和大规模的训练数据,推动任务特定预测模型和指令微调LLMs的发展。
LLM4Mat-Bench is a dataset developed by institutions including Princeton University, the University of Toronto, and others, for evaluating the performance of large language models (LLMs) in materials property prediction tasks. This dataset contains approximately 1.97 million crystal structure entries sourced from 10 public materials data repositories, covering 45 distinct material properties. The dataset supports multiple input modalities, such as crystal compositions, CIF files, and textual descriptions of crystal structures, with cumulative token counts reaching 4.7M, 615.5M, and 3.1B respectively. The construction of this dataset involves collecting CIF files and material property data from multiple public databases, and generating textual descriptions of crystal structures using Robocrystallographer. LLM4Mat-Bench aims to tackle property prediction and materials discovery challenges in materials science, and advance the development of task-specific prediction models and instruction-tuned LLMs by providing diverse material representations and large-scale training data.
LLM4Mat-Bench 数据集概述
数据集简介
LLM4Mat-Bench 是目前用于评估大型语言模型(LLMs)在材料属性预测性能方面最大的基准数据集。
数据获取
- 数据集可从以下链接下载:LLM4Mat-Bench 数据集。
- 每个数据集包含固定的训练/验证/测试分割,以确保可重复性和公平的模型比较。
数据结构
数据集包含多个子数据集,每个子数据集包含以下内容:
- 训练集
- 验证集
- 测试集
数据集使用
安装与环境配置
bash git clone https://github.com/vertaix/LLM4Mat-Bench.git cd LLM4Mat-Bench conda create -n <environment_name> requirement.txt conda activate <environment_name>
数据存储
- 下载的数据应存储在
data/目录下,其中LLM4Mat-Bench是父目录。
模型检查点
- 从以下链接下载 LLM-Prop 和 MatBERT 的检查点:检查点下载链接。
- 将检查点文件夹保存到
LLM4Mat-Bench目录中。
数据集评估
评估训练好的 LLM-Prop 和 MatBERT
通过修改 evaluate.sh 脚本来评估模型:
bash
bash scripts/evaluate.sh
从头训练 LLM-Prop 和 MatBERT
通过修改 train.sh 脚本来训练模型:
bash
bash scripts/train.sh
使用 LLaMA2-7b-chat 模型生成属性值
通过修改 llama_inference.sh 脚本来生成属性值:
bash
bash scripts/llama_inference.sh
评估 LLaMA 结果
在运行 llama_inference.sh 后,通过修改 llama_evaluate.sh 脚本来评估结果:
bash
bash scripts/llama_evaluate.sh
数据许可
数据集的许可归属于每个数据集/数据库的原始创建者。
排行榜
总体性能
| 输入 | 模型 | MP (回归) | MP (分类) | JARVIS-DFT (回归) | GNoME (回归) | hMOF (回归) | Cantor HEA (回归) | JARVIS-QETB (回归) | OQMD (回归) | QMOF (回归) | SNUMAT (分类) | SNUMAT (回归) | OMDB (回归) |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| CIF | CGCNN (baseline) | 5.319 | 0.846 | 7.048 | 19.478 | 2.257 | 17.780 | 61.729 | 14.496 | 3.076 | 1.973 | 0.722 | 2.751 |
| Comp. | Llama 2-7b-chat:0S | 0.389 | 0.491 | Inval. | 0.164 | 0.174 | 0.034 | 0.188 | 0.105 | 0.303 | 0.940 | Inval. | 0.885 |
| Comp. | Llama 2-7b-chat:5S | 0.627 | 0.507 | 0.704 | 0.499 | 0.655 | 0.867 | 1.047 | 1.160 | 0.932 | 1.157 | 0.466 | 1.009 |
| Comp. | MatBERT-109M | 5.317 | 0.722 | 4.103 | 12.834 | 1.430 | 6.769 | 11.952 | 5.772 | 2.049 | 1.828 | 0.712 | 1.554 |
| Comp. | LLM-Prop-35M | 4.394 | 0.691 | 2.912 | 15.599 | 1.479 | 8.400 | 59.443 | 6.020 | 1.958 | 1.509 | 0.719 | 1.507 |
MP 数据集结果
| 输入 | 模型 | FEPA | Bandgap | EPA | Ehull | Efermi | Density | Density Atomic | Volume | Is Stable | Is Gab Direct |
|---|---|---|---|---|---|---|---|---|---|---|---|
| CIF | CGCNN (baseline) | 8.151 | 3.255 | 7.224 | 3.874 | 3.689 | 8.773 | 5.888 | 1.703 | 0.882 | 0.810 |
| Comp. | Llama 2-7b-chat:0S | 0.008 | 0.623 | 0.009 | 0.001 | 0.003 | 0.967 | 0.754 | 0.747 | 0.500 | 0.482 |
| Comp. | Llama 2-7b-chat:5S | 0.33 | 1.217 | 0.239 | 0.132 | 0.706 | 0.899 | 0.724 | 0.771 | 0.502 | 0.512 |
| Comp. | MatBERT-109M | 8.151 | 2.971 | 9.32 | 2.583 | 3.527 | 7.626 | 5.26 | 3.099 | 0.764 | 0.681 |
| Comp. | LLM-Prop-35M | 7.482 | 2.345 | 7.437 | 2.006 | 3.159 | 6.682 | 3.523 | 2.521 | 0.746 | 0.636 |
JARVIS-DFT 数据集结果
| 输入 | 模型 | FEPA | Bandgap (OPT) | Tot. En. | Ehull | Bandgap (MBJ) | Kv | Gv | SLME | Spillage | ε<sub>x</sub> (OPT) | ε (DFPT) | Max. Piezo. (dij) | Max. Piezo. (eij) | Max. EFG | Exf. En. | Avg. m<sub>e</sub> | n-Seebeck | n-PF | p-Seebeck | p-PF |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| CIF | CGCNN (baseline) | 13.615 | 4.797 | 22.906 | 1.573 | 4.497 | 3.715 | 2.337 | 1.862 | 1.271 | 2.425 | 1.12 | 0.418 | 1.291 | 1.787 | 0.842 | 1.796 | 2.23 | 1.573 |
- 1LLM4Mat-Bench: Benchmarking Large Language Models for Materials Property Prediction普林斯顿大学 · 2024年


