nlpai-lab/miracl-multilingual-triplets
收藏资源简介:
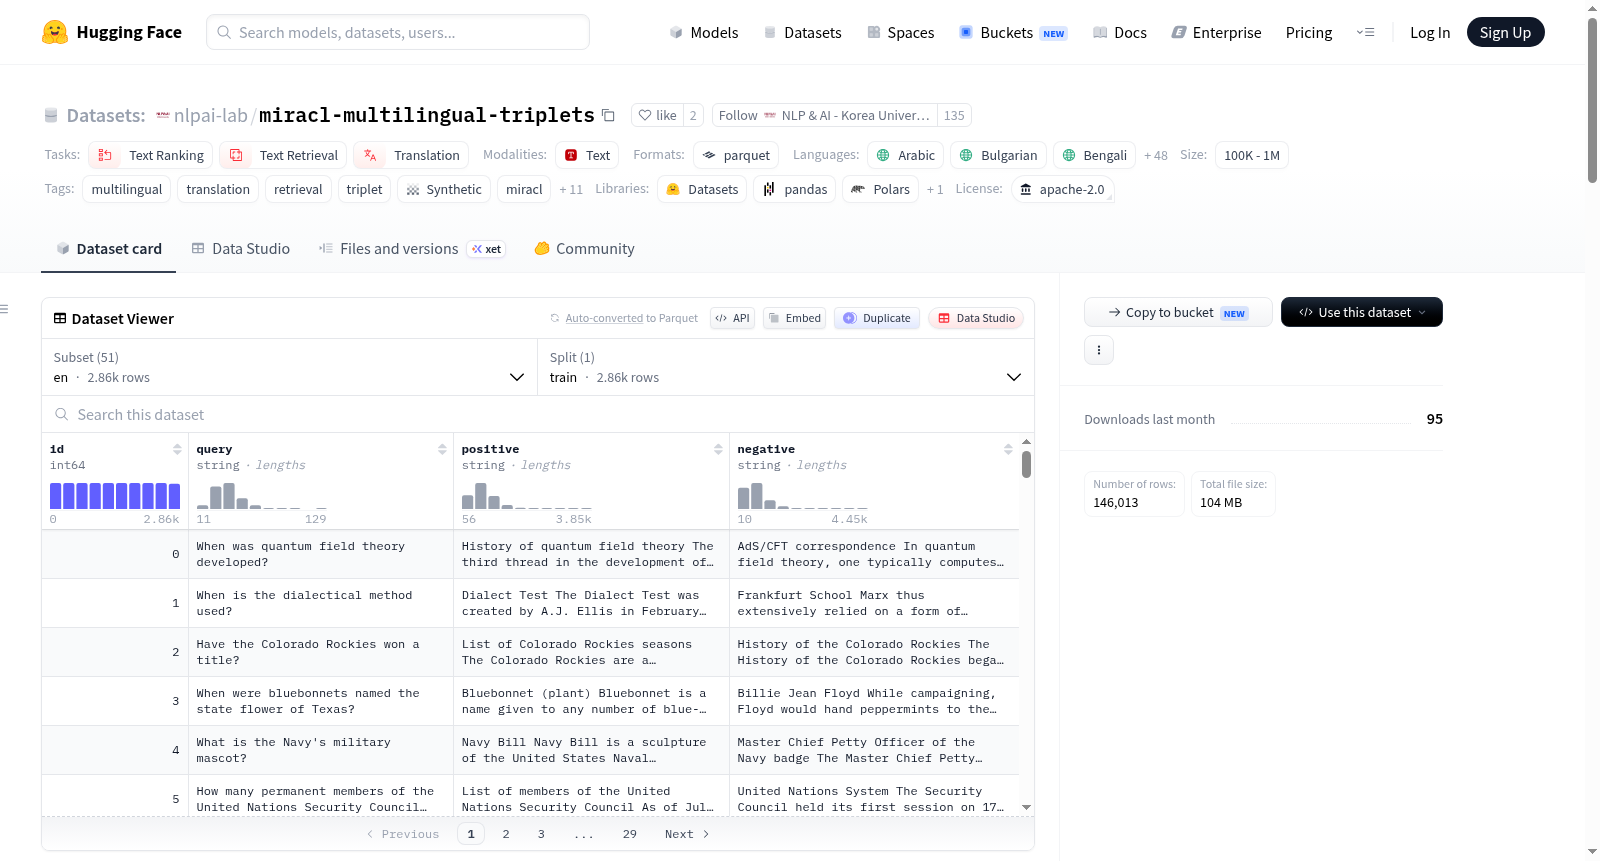
MIRACL 51种语言三元组数据集是一个多语言检索和重排序数据集,用于训练密集检索、句子嵌入、重排序和跨语言搜索模型。它包含从MIRACL英文训练集派生的(查询、正例、负例)三元组。该数据集提供51种语言子集:原始英文数据和翻译成50种语言的数据。每个子集包含2,863个对齐的训练示例,具有相同id的行表示同一源三元组的翻译。对齐的(查询、正例、负例)结构支持多语言检索、多语言重排序、对比学习和困难负样本训练。数据格式为Parquet,子集包括51种语言代码(如en、ko、ja、zh、de、fr等),仅包含训练分割,每个子集行数为2,863,总行数跨子集为146,013。数据列包括id(跨语言子集共享的对齐标识符)、查询(搜索查询)、正例(与查询相关的段落)和负例(与查询无关的段落)。数据集基于MIRACL源数据集,使用google/translategemma-27b-it模型翻译,并遵循Apache-2.0许可证。
MIRACL Triplets in 51 Languages is a multilingual retrieval and reranking dataset for training dense retrieval, sentence embedding, reranker, and cross-lingual search models. It contains (query, positive, negative) triplets derived from the English training split of miracl/miracl. The dataset provides 51 language subsets: the original English data and translations into 50 languages. Each subset contains 2,863 aligned training examples, where rows with the same id represent translations of the same source triplet. The aligned (query, positive, negative) structure supports multilingual retrieval, multilingual reranking, contrastive learning, and hard-negative training. Format: Parquet. Subsets: 51 language codes including en, ko, ja, zh, de, and fr. Split: train. Rows per subset: 2,863. Total rows across subsets: 146,013. Columns: id (alignment identifier shared across language subsets), query (search query), positive (passage relevant to the query), negative (passage not relevant to the query). Source dataset: miracl/miracl, translated using google/translategemma-27b-it model, and released under Apache-2.0 license.