CoffeeGitta/difficulty-aime_1983-2024-generations
收藏资源简介:
--- dataset_info: - config_name: Qwen--Qwen2.5-Math-1.5B-Instruct features: - name: formatted_prompt dtype: string - name: generated_solutions list: - name: input_cost_usd_once dtype: float64 - name: input_tokens dtype: int64 - name: output_cost_usd dtype: float64 - name: output_tokens dtype: int64 - name: rollout_cost_usd dtype: float64 - name: score dtype: float64 - name: text dtype: string - name: ground_truth dtype: string - name: input_cost_usd_once dtype: float64 - name: k dtype: int64 - name: majority_vote_extracted_answer dtype: string - name: majority_vote_is_correct dtype: int8 - name: max_len dtype: int64 - name: model_name dtype: string - name: pass_at_k dtype: float64 - name: problem dtype: string - name: problem_id dtype: string - name: rating dtype: float64 - name: split dtype: string - name: success_rate dtype: float64 - name: task dtype: string - name: temperature dtype: float64 - name: total_cost_usd dtype: float64 - name: total_input_tokens dtype: int64 - name: total_output_cost_usd dtype: float64 - name: total_output_tokens dtype: int64 splits: - name: train num_bytes: 10300676 num_examples: 747 - name: validation num_bytes: 2560424 num_examples: 186 - name: test num_bytes: 414719 num_examples: 30 download_size: 4396726 dataset_size: 13275819 - config_name: Qwen--Qwen2.5-Math-7B-Instruct features: - name: formatted_prompt dtype: string - name: generated_solutions list: - name: input_cost_usd_once dtype: float64 - name: input_tokens dtype: int64 - name: output_cost_usd dtype: float64 - name: output_tokens dtype: int64 - name: rollout_cost_usd dtype: float64 - name: score dtype: float64 - name: text dtype: string - name: ground_truth dtype: string - name: input_cost_usd_once dtype: float64 - name: k dtype: int64 - name: majority_vote_extracted_answer dtype: string - name: majority_vote_is_correct dtype: int8 - name: max_len dtype: int64 - name: model_name dtype: string - name: pass_at_k dtype: float64 - name: problem dtype: string - name: problem_id dtype: string - name: rating dtype: float64 - name: split dtype: string - name: success_rate dtype: float64 - name: task dtype: string - name: temperature dtype: float64 - name: total_cost_usd dtype: float64 - name: total_input_tokens dtype: int64 - name: total_output_cost_usd dtype: float64 - name: total_output_tokens dtype: int64 splits: - name: train num_bytes: 16988682 num_examples: 747 - name: validation num_bytes: 4267785 num_examples: 186 - name: test num_bytes: 685250 num_examples: 30 download_size: 12363943 dataset_size: 21941717 - config_name: Qwen--Qwen3-8B features: - name: formatted_prompt dtype: string - name: generated_solutions list: - name: input_cost_usd_once dtype: float64 - name: input_tokens dtype: int64 - name: output_cost_usd dtype: float64 - name: output_tokens dtype: int64 - name: rollout_cost_usd dtype: float64 - name: score dtype: float64 - name: text dtype: string - name: ground_truth dtype: string - name: input_cost_usd_once dtype: float64 - name: k dtype: int64 - name: majority_vote_extracted_answer dtype: string - name: majority_vote_is_correct dtype: int8 - name: max_len dtype: int64 - name: model_name dtype: string - name: pass_at_k dtype: float64 - name: problem dtype: string - name: problem_id dtype: string - name: rating dtype: float64 - name: split dtype: string - name: success_rate dtype: float64 - name: task dtype: string - name: temperature dtype: float64 - name: total_cost_usd dtype: float64 - name: total_input_tokens dtype: int64 - name: total_output_cost_usd dtype: float64 - name: total_output_tokens dtype: int64 splits: - name: train num_bytes: 139696847 num_examples: 747 - name: validation num_bytes: 34853241 num_examples: 186 - name: test num_bytes: 7636629 num_examples: 30 download_size: 69122087 dataset_size: 182186717 - config_name: deepseek-ai--DeepSeek-R1-Distill-Qwen-7B features: - name: formatted_prompt dtype: string - name: generated_solutions list: - name: input_cost_usd_once dtype: float64 - name: input_tokens dtype: int64 - name: output_cost_usd dtype: float64 - name: output_tokens dtype: int64 - name: rollout_cost_usd dtype: float64 - name: score dtype: float64 - name: text dtype: string - name: ground_truth dtype: string - name: input_cost_usd_once dtype: float64 - name: k dtype: int64 - name: majority_vote_extracted_answer dtype: string - name: majority_vote_is_correct dtype: int8 - name: max_len dtype: int64 - name: model_name dtype: string - name: pass_at_k dtype: float64 - name: problem dtype: string - name: problem_id dtype: string - name: rating dtype: float64 - name: split dtype: string - name: success_rate dtype: float64 - name: task dtype: string - name: temperature dtype: float64 - name: total_cost_usd dtype: float64 - name: total_input_tokens dtype: int64 - name: total_output_cost_usd dtype: float64 - name: total_output_tokens dtype: int64 splits: - name: train num_bytes: 103945759 num_examples: 747 - name: validation num_bytes: 25254903 num_examples: 186 - name: test num_bytes: 5949109 num_examples: 30 download_size: 51923554 dataset_size: 135149771 - config_name: openai--gpt-oss-20b_high features: - name: formatted_prompt dtype: string - name: generated_solutions list: - name: input_cost_usd_once dtype: float64 - name: input_tokens dtype: int64 - name: output_cost_usd dtype: float64 - name: output_tokens dtype: int64 - name: rollout_cost_usd dtype: float64 - name: score dtype: float64 - name: text dtype: string - name: ground_truth dtype: string - name: input_cost_usd_once dtype: float64 - name: k dtype: int64 - name: majority_vote_extracted_answer dtype: string - name: majority_vote_is_correct dtype: int8 - name: max_len dtype: int64 - name: model_name dtype: string - name: pass_at_k dtype: float64 - name: problem dtype: string - name: problem_id dtype: string - name: rating dtype: float64 - name: split dtype: string - name: success_rate dtype: float64 - name: task dtype: string - name: temperature dtype: float64 - name: total_cost_usd dtype: float64 - name: total_input_tokens dtype: int64 - name: total_output_cost_usd dtype: float64 - name: total_output_tokens dtype: int64 splits: - name: train num_bytes: 245770860 num_examples: 598 - name: validation num_bytes: 63258808 num_examples: 149 - name: test num_bytes: 17802996 num_examples: 30 download_size: 156628984 dataset_size: 326832664 - config_name: openai--gpt-oss-20b_low features: - name: formatted_prompt dtype: string - name: generated_solutions list: - name: input_cost_usd_once dtype: float64 - name: input_tokens dtype: int64 - name: output_cost_usd dtype: float64 - name: output_tokens dtype: int64 - name: rollout_cost_usd dtype: float64 - name: score dtype: float64 - name: text dtype: string - name: ground_truth dtype: string - name: input_cost_usd_once dtype: float64 - name: k dtype: int64 - name: majority_vote_extracted_answer dtype: string - name: majority_vote_is_correct dtype: int8 - name: max_len dtype: int64 - name: model_name dtype: string - name: pass_at_k dtype: float64 - name: problem dtype: string - name: problem_id dtype: string - name: rating dtype: float64 - name: split dtype: string - name: success_rate dtype: float64 - name: task dtype: string - name: temperature dtype: float64 - name: total_cost_usd dtype: float64 - name: total_input_tokens dtype: int64 - name: total_output_cost_usd dtype: float64 - name: total_output_tokens dtype: int64 splits: - name: train num_bytes: 16580971 num_examples: 747 - name: validation num_bytes: 4380677 num_examples: 186 - name: test num_bytes: 740470 num_examples: 30 download_size: 10987909 dataset_size: 21702118 - config_name: openai--gpt-oss-20b_medium features: - name: formatted_prompt dtype: string - name: generated_solutions list: - name: input_cost_usd_once dtype: float64 - name: input_tokens dtype: int64 - name: output_cost_usd dtype: float64 - name: output_tokens dtype: int64 - name: rollout_cost_usd dtype: float64 - name: score dtype: float64 - name: text dtype: string - name: ground_truth dtype: string - name: input_cost_usd_once dtype: float64 - name: k dtype: int64 - name: majority_vote_extracted_answer dtype: string - name: majority_vote_is_correct dtype: int8 - name: max_len dtype: int64 - name: model_name dtype: string - name: pass_at_k dtype: float64 - name: problem dtype: string - name: problem_id dtype: string - name: rating dtype: float64 - name: split dtype: string - name: success_rate dtype: float64 - name: task dtype: string - name: temperature dtype: float64 - name: total_cost_usd dtype: float64 - name: total_input_tokens dtype: int64 - name: total_output_cost_usd dtype: float64 - name: total_output_tokens dtype: int64 splits: - name: train num_bytes: 85607637 num_examples: 747 - name: validation num_bytes: 22787178 num_examples: 186 - name: test num_bytes: 4956684 num_examples: 30 download_size: 56277198 dataset_size: 113351499 configs: - config_name: Qwen--Qwen2.5-Math-1.5B-Instruct data_files: - split: train path: Qwen--Qwen2.5-Math-1.5B-Instruct/train-* - split: validation path: Qwen--Qwen2.5-Math-1.5B-Instruct/validation-* - split: test path: Qwen--Qwen2.5-Math-1.5B-Instruct/test-* - config_name: Qwen--Qwen2.5-Math-7B-Instruct data_files: - split: train path: Qwen--Qwen2.5-Math-7B-Instruct/train-* - split: validation path: Qwen--Qwen2.5-Math-7B-Instruct/validation-* - split: test path: Qwen--Qwen2.5-Math-7B-Instruct/test-* - config_name: Qwen--Qwen3-8B data_files: - split: train path: Qwen--Qwen3-8B/train-* - split: validation path: Qwen--Qwen3-8B/validation-* - split: test path: Qwen--Qwen3-8B/test-* - config_name: deepseek-ai--DeepSeek-R1-Distill-Qwen-7B data_files: - split: train path: deepseek-ai--DeepSeek-R1-Distill-Qwen-7B/train-* - split: validation path: deepseek-ai--DeepSeek-R1-Distill-Qwen-7B/validation-* - split: test path: deepseek-ai--DeepSeek-R1-Distill-Qwen-7B/test-* - config_name: openai--gpt-oss-20b_high data_files: - split: train path: openai--gpt-oss-20b_high/train-* - split: validation path: openai--gpt-oss-20b_high/validation-* - split: test path: openai--gpt-oss-20b_high/test-* - config_name: openai--gpt-oss-20b_low data_files: - split: train path: openai--gpt-oss-20b_low/train-* - split: validation path: openai--gpt-oss-20b_low/validation-* - split: test path: openai--gpt-oss-20b_low/test-* - config_name: openai--gpt-oss-20b_medium data_files: - split: train path: openai--gpt-oss-20b_medium/train-* - split: validation path: openai--gpt-oss-20b_medium/validation-* - split: test path: openai--gpt-oss-20b_medium/test-* --- # Generations Dataset: aime_1983-2024 LLM-generated solutions across train/validation/test splits for multiple models. ## Columns | Column | Type | Description | |--------|------|-------------| | `problem` | str | Problem statement | | `generated_solutions` | list | Generated solutions with scores | | `success_rate` | float | Fraction of correct generations | | `majority_vote_is_correct` | int (0/1) | Whether majority vote is correct | | `k` | int | Number of samples generated | | `temperature` | float | Sampling temperature | | `max_len` | int | Maximum generation length | | `model_name` | str | Model used for generation | ## Usage ```python from datasets import load_dataset dataset = load_dataset("CoffeeGitta/difficulty-aime_1983-2024-generations", name="<org--model>") train = dataset["train"] ``` ## Citation ```bibtex @article{lugoloobi_llms_2026, title = {LLMs Encode Their Failures: Predicting Success from Pre-Generation Activations}, url = {http://arxiv.org/abs/2602.09924}, author = {Lugoloobi, William and Foster, Thomas and Bankes, William and Russell, Chris}, year = {2026}, } ```
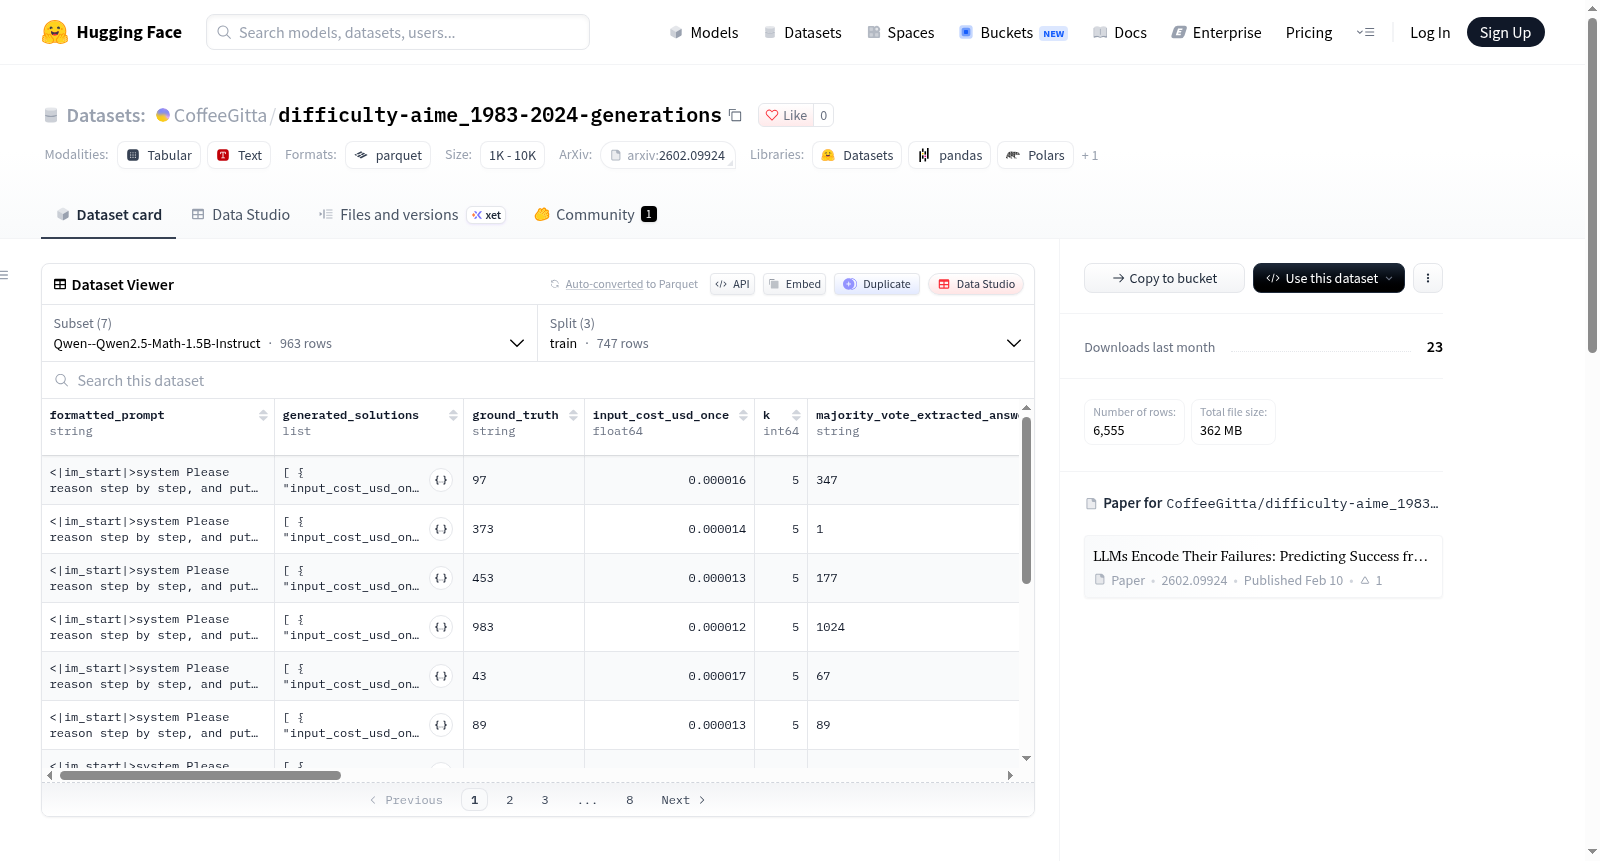
Generations Dataset: aime_1983-2024. LLM-generated solutions across train/validation/test splits for multiple models. It contains solutions generated by various models (e.g., Qwen2.5-Math, DeepSeek-R1, GPT-OSS-20B) for AIME (American Invitational Mathematics Examination, 1983-2024) problems, with features such as problem statements, generated solutions (with scores and cost information), success rates, majority vote correctness, etc. The dataset is designed for research on predicting LLM failures from pre-generation activations. Total dataset size is approximately 1.8GB, with 747 training examples, 186 validation examples, and 30 test examples (varies slightly across models).