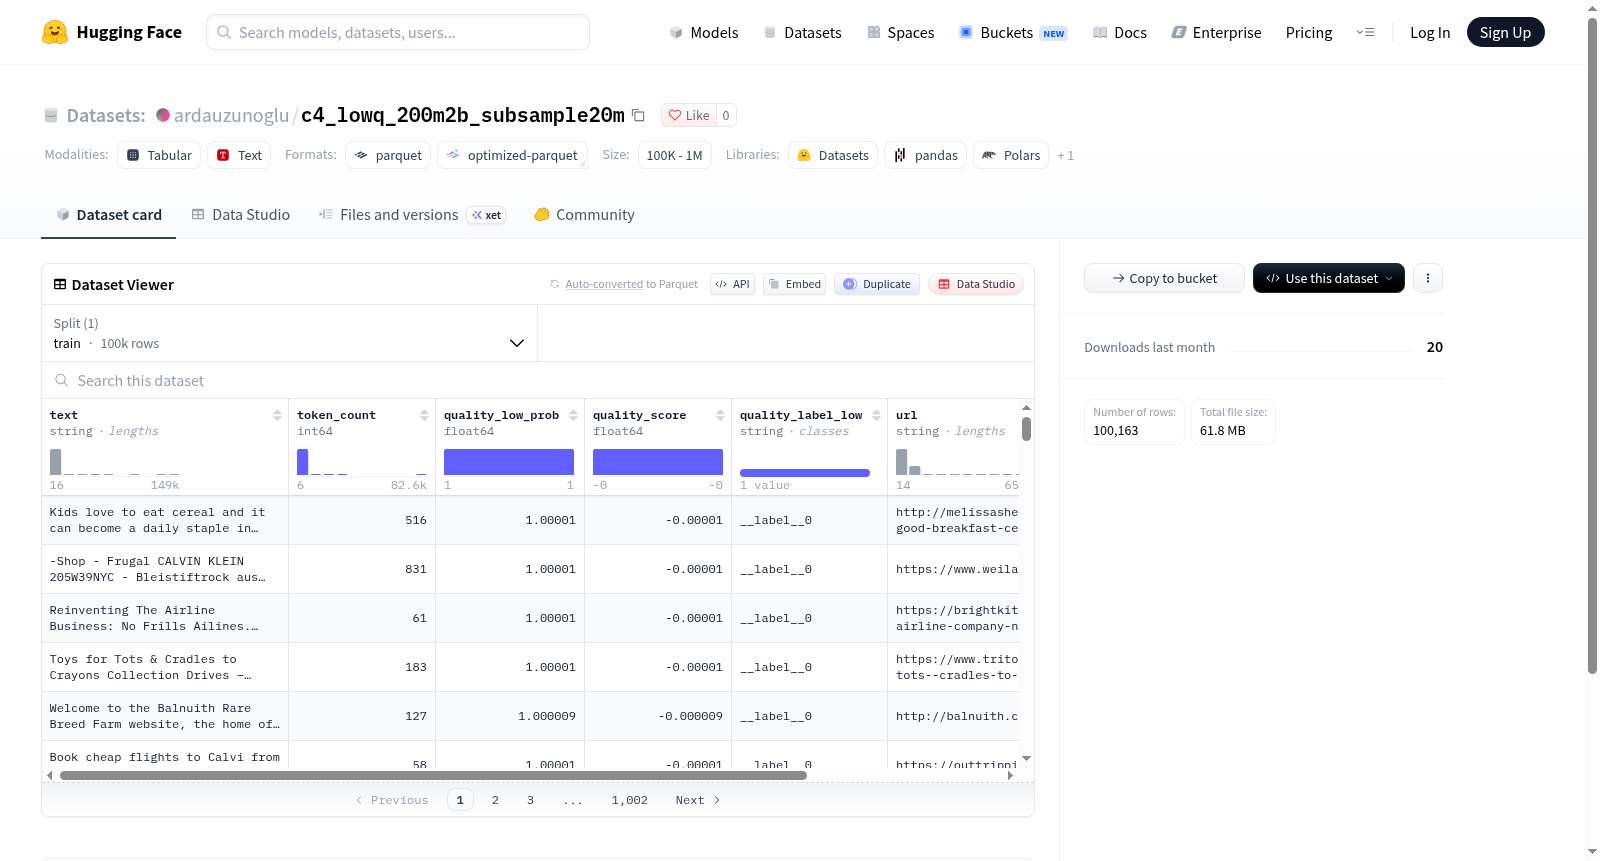
ardauzunoglu/c4_lowq_200m2b_subsample20m
收藏资源简介:
--- dataset_info: features: - name: text dtype: string - name: token_count dtype: int64 - name: quality_low_prob dtype: float64 - name: quality_score dtype: float64 - name: quality_label_low dtype: string - name: url dtype: string splits: - name: train num_bytes: 105430605 num_examples: 100163 download_size: 61840164 dataset_size: 105430605 configs: - config_name: default data_files: - split: train path: data/train-* ---
This dataset contains 100,163 training examples, each with text content, token count, text quality assessment metrics (such as low-quality probability, score, and label), and source URL. It may be used for text quality analysis, filtering, or machine learning tasks, with a total size of approximately 105 MB and a download size of approximately 62 MB.