Enheduanna-Dataset
收藏资源简介:
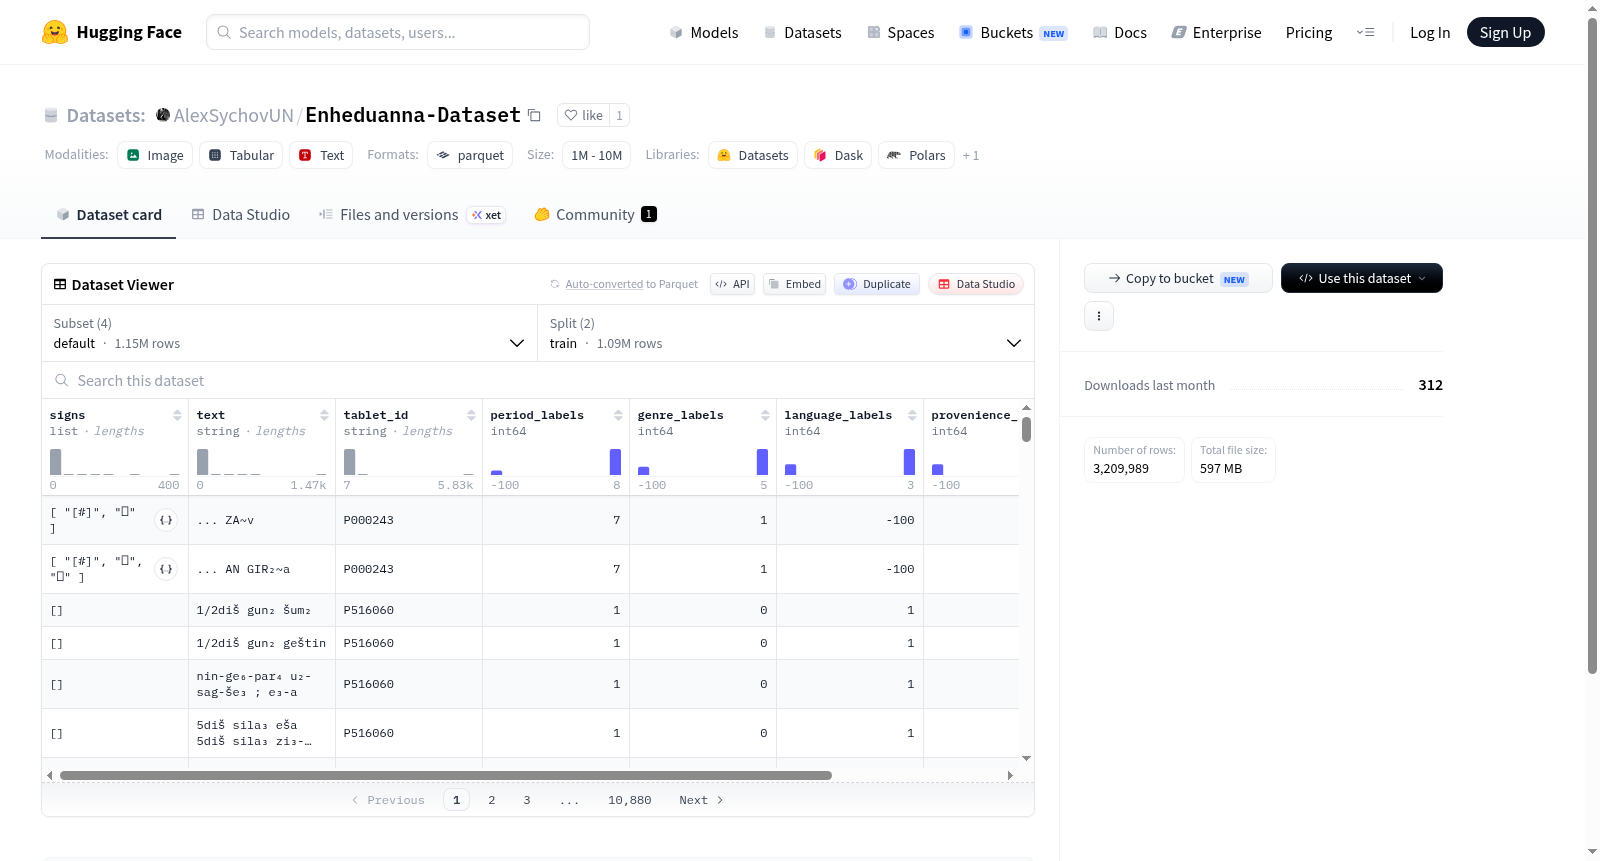
该数据集是针对古代楔形文字碑文的多模态资源,包含多个配置版本,用于支持不同粒度的研究和机器学习任务。default 配置提供原始的碑文符号列表、文本内容和翻译,并附带时期、体裁、语言和出处的标签;该配置包含约 108.8 万条训练样本和 6 万条验证样本。documents 配置以文档级粒度组织,包含文本、翻译和相同的标签,训练集约 13.6 万条,验证集 7664 条,测试集 7516 条。signs_translit 配置专注于符号转写,提供符号列表、文本和碑文编号,训练集约 170.7 万条,验证集 94159 条,测试集 96772 条。vision 配置包含碑文图像及其对应的时期、体裁、出处和语言,以及图像中文本区域的边界框坐标(x1, y1, x2, y2),训练集 11327 张图像,验证集 632 张,测试集 666 张。数据集适用于文本分类、符号识别、翻译、图像检测、多模态学习等任务。
This dataset is a multimodal resource for ancient cuneiform inscriptions, containing multiple configuration versions to support research and machine learning tasks at different granularities. The default configuration provides original lists of cuneiform signs, text content, and translations, along with labels for period, genre, language, and provenance; it includes approximately 1.088 million training samples and 60,000 validation samples. The documents configuration organizes data at the document level, including text, translations, and the same labels, with approximately 136,000 training samples, 7,664 validation samples, and 7,516 test samples. The signs_translit configuration focuses on sign transliteration, providing lists of signs, text, and inscription numbers, with approximately 1.707 million training samples, 94,159 validation samples, and 96,772 test samples. The vision configuration includes inscription images along with their corresponding period, genre, provenance, and language, as well as bounding box coordinates (x1, y1, x2, y2) for text regions in the images, with 11,327 training images, 632 validation images, and 666 test images. The dataset is suitable for tasks such as text classification, sign recognition, translation, image detection, and multimodal learning.
Enheduanna-Dataset 数据集概述
数据集简介
Enheduanna-Dataset是针对古代楔形文字文献研究的多模态数据集,以美索不达米亚文学经典《Enheduanna》为基础资料构建。数据集包含多个配置(config),覆盖文本、符号转写与图像三种数据形式,旨在支持亚述学、语言学和计算机视觉等相关研究领域。
数据集配置
1. default(默认配置)
- 适用场景:基础的文本与翻译对齐任务。
- 数据字段:
signs:楔形符号序列(列表形式)text:原文文本tablet_id:泥板编号period_labels:时期标签(整数)genre_labels:体裁标签(整数)language_labels:语言标签(整数)provenience_labels:出土位置标签(整数)translation:翻译文本
- 数据规模:
- 训练集:1,087,943 条
- 验证集:60,477 条
- 数据大小:总大小约 875 MB(下载大小约 93 MB)
2. documents(文档级配置)
- 适用场景:面向整篇文献的处理任务(如文档分类、翻译等),每条记录对应一篇完整文献。
- 数据字段:与 default 相同(共8个字段)。
- 数据规模:
- 训练集:135,628 条
- 验证集:7,664 条
- 测试集:7,516 条
- 数据大小:总大小约 200 MB(下载大小约 152 MB)
3. signs_translit(符号转写配置)
- 适用场景:专注楔形符号级转写研究,不包含标签与翻译信息。
- 数据字段:
signs:楔形符号序列(列表形式)text:转写文本(英文音译)tablet_id:泥板编号
- 数据规模:
- 训练集:1,707,204 条
- 验证集:94,159 条
- 测试集:96,772 条
- 数据大小:总大小约 194 MB(下载大小约 134 MB)
4. vision(视觉配置)
- 适用场景:用于泥板图像中的符号检测与定位任务,提供图像及其对应的标注框与元数据。
- 数据字段:
tablet_id:泥板编号image:泥板图像x1,y1,x2,y2:边界框坐标(float32)period:时期(字符串)genre:体裁(字符串)provenience:出土位置(字符串)language:语言(字符串)
- 数据规模:
- 训练集:11,327 条
- 验证集:632 条
- 测试集:666 条
- 数据大小:总大小约 218 MB(下载大小约 217 MB)
综合统计
- 总数据量:约 1,487,947,165 字节(约 1.49 GB)
- 总下载大小:约 597,127,341 字节(约 597 MB)
- 四种配置均提供明确的 train/validation/test(或 train/validation)划分,便于开展有监督学习实验。