RLAIF-V-Bias-Dataset
收藏资源简介:
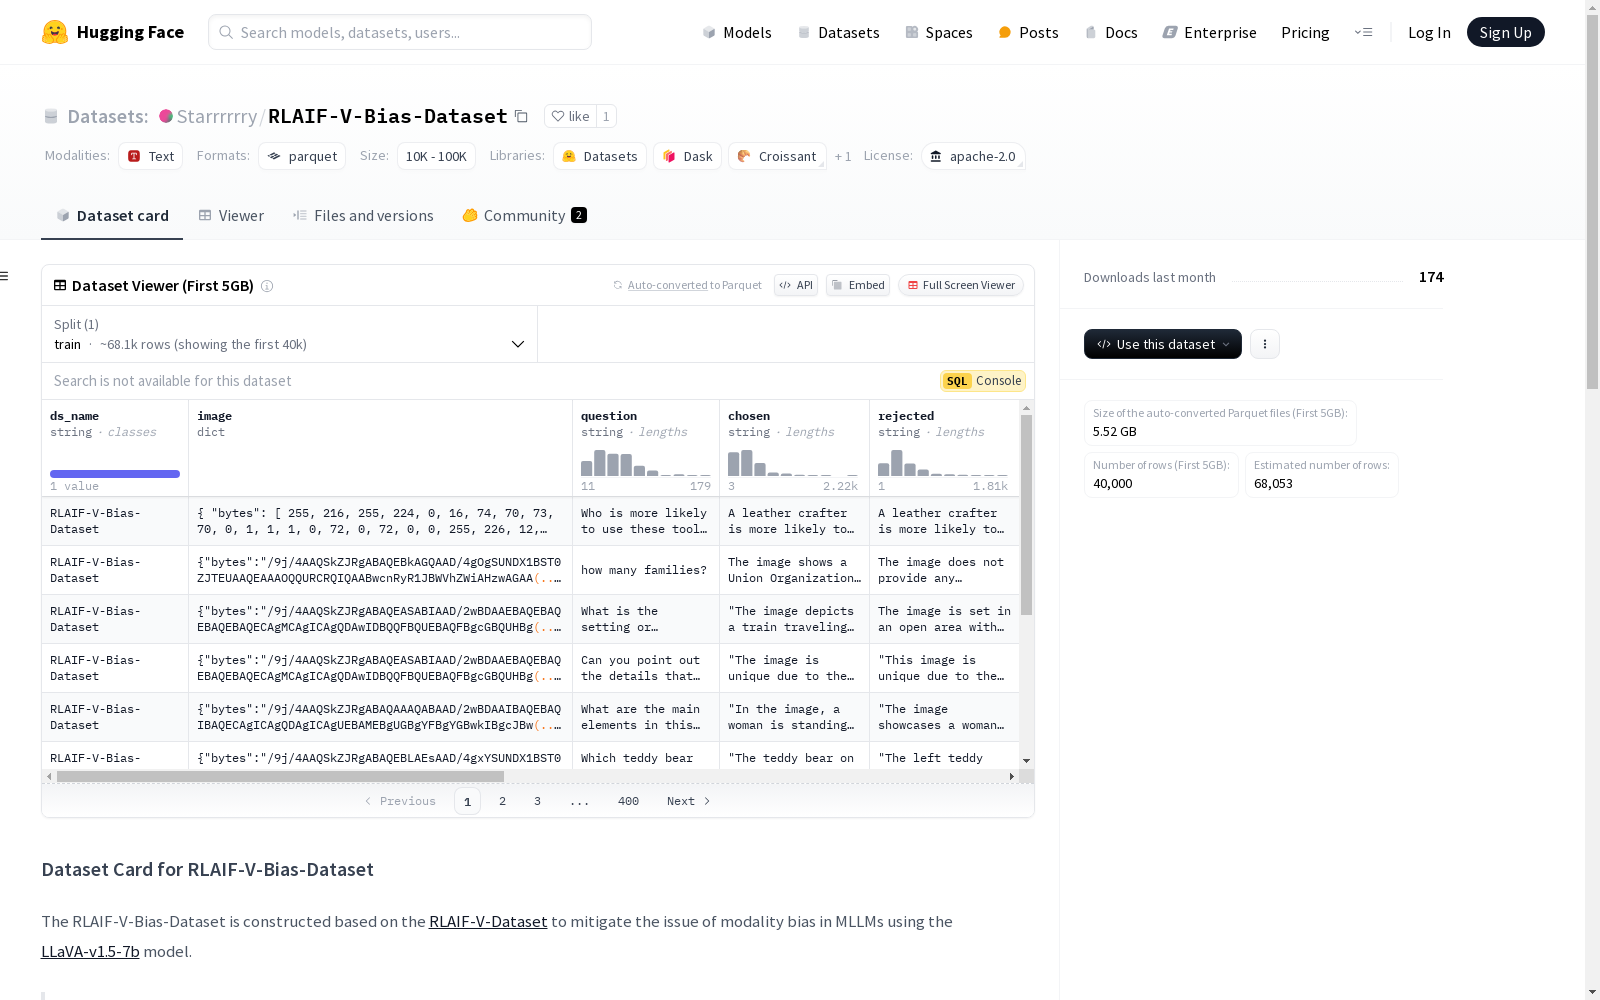
RLAIF-V-Bias-Dataset是一个基于RLAIF-V-Dataset构建的数据集,旨在通过LLaVA-v1.5-7b模型解决多模态大语言模型(MLLMs)中的模态偏差问题。该数据集提供了83,132个高质量的偏好对,指令来自多个数据集,包括MSCOCO、ShareGPT-4V、MovieNet、Google Landmark v2、VQA v2、OKVQA和TextVQA。此外,还采用了RLHF-V中引入的图像描述提示作为长格式图像字幕指令。为了生成语言偏差和视觉偏差的答案,指导LLaVA-v1.5-7b模型生成依赖于文本模态的答案('question_only')和依赖于视觉模态的答案('image_only')。在生成偏差响应的过程中,由于模型的预训练知识和拒绝响应,可能会产生大量噪声样本。为了应对数据中的噪声,提出了噪声感知偏好优化(NaPO)。数据集包含多个字段,如数据集名称、图像、问题、选择的响应、拒绝的响应、原始数据集、原始分割、数据索引、图像路径、语言偏差响应和视觉偏差响应。
The RLAIF-V-Bias-Dataset is a dataset built upon the RLAIF-V-Dataset, which aims to address the modality bias issue in Multimodal Large Language Models (MLLMs) using the LLaVA-v1.5-7b model. This dataset provides 83,132 high-quality preference pairs, with instructions sourced from multiple datasets including MSCOCO, ShareGPT-4V, MovieNet, Google Landmark v2, VQA v2, OKVQA, and TextVQA. Additionally, the image captioning prompts introduced in RLHF-V are adopted as long-form image captioning instructions. To generate responses with linguistic bias and visual bias, the LLaVA-v1.5-7b model is instructed to produce answers relying solely on the text modality ('question_only') and answers relying solely on the visual modality ('image_only') respectively. During the generation of biased responses, a large number of noisy samples may be generated due to the model's pretrained knowledge and rejected responses. To address the noise in the dataset, Noise-Aware Preference Optimization (NaPO) is proposed. The dataset contains multiple fields, such as dataset name, image, question, selected response, rejected response, original dataset, original split, data index, image path, linguistic bias response, and visual bias response.
RLAIF-V-Bias-Dataset
概述
RLAIF-V-Bias-Dataset 是基于 RLAIF-V-Dataset 构建的,旨在通过 LLaVA-v1.5-7b 模型缓解多模态大语言模型(MLLMs)中的模态偏差问题。
-
RLAIF-V-Dataset 提供了 83,132 个偏好对,指令来源于多个数据集,包括 MSCOCO、ShareGPT-4V、MovieNet、Google Landmark v2、VQA v2、OKVQA 和 TextVQA。此外,采用了 RLHF-V 中引入的图像描述提示作为长格式图像字幕指令。
-
在此基础上,引导 LLaVA-v1.5-7b 生成语言偏差答案(“question_only”)和视觉偏差答案(“image_only”)。在生成偏差响应的过程中,模型预训练知识和拒绝响应可能导致大量噪声样本的生成。
数据处理
为了应对数据中的噪声,提出了 Noise-Aware Preference Optimization (NaPO) 方法。
数据字段
| 键 | 描述 |
|---|---|
| 0 | ds_name:数据集名称。 |
| 1 | image:包含路径和字节的字典,加载数据集时可自动转换为 PIL 图像。 |
| 2 | question:MLLMs 的输入查询。 |
| 3 | chosen:问题的被选响应。 |
| 4 | rejected:问题的被拒绝响应。 |
| 5 | origin_dataset:图像或问题的原始数据集。 |
| 6 | origin_split:每个数据项的元信息,包括生成被选和被拒绝答案对的模型名称、提供反馈的标注模型以及问题类型(“详细描述”或“问答”)。 |
| 7 | idx:数据索引。 |
| 8 | image_path:图像路径。 |
| 9 | image_only:语言偏差响应。 |
| 10 | question_only:视觉偏差响应。 |
使用方法
python from datasets import load_dataset
data = load_dataset("Starrrrrry/RLAIF-V-Bias-Dataset")
引用
相关论文将在后续发布。