Ultra-FineWeb-L1
收藏资源简介:
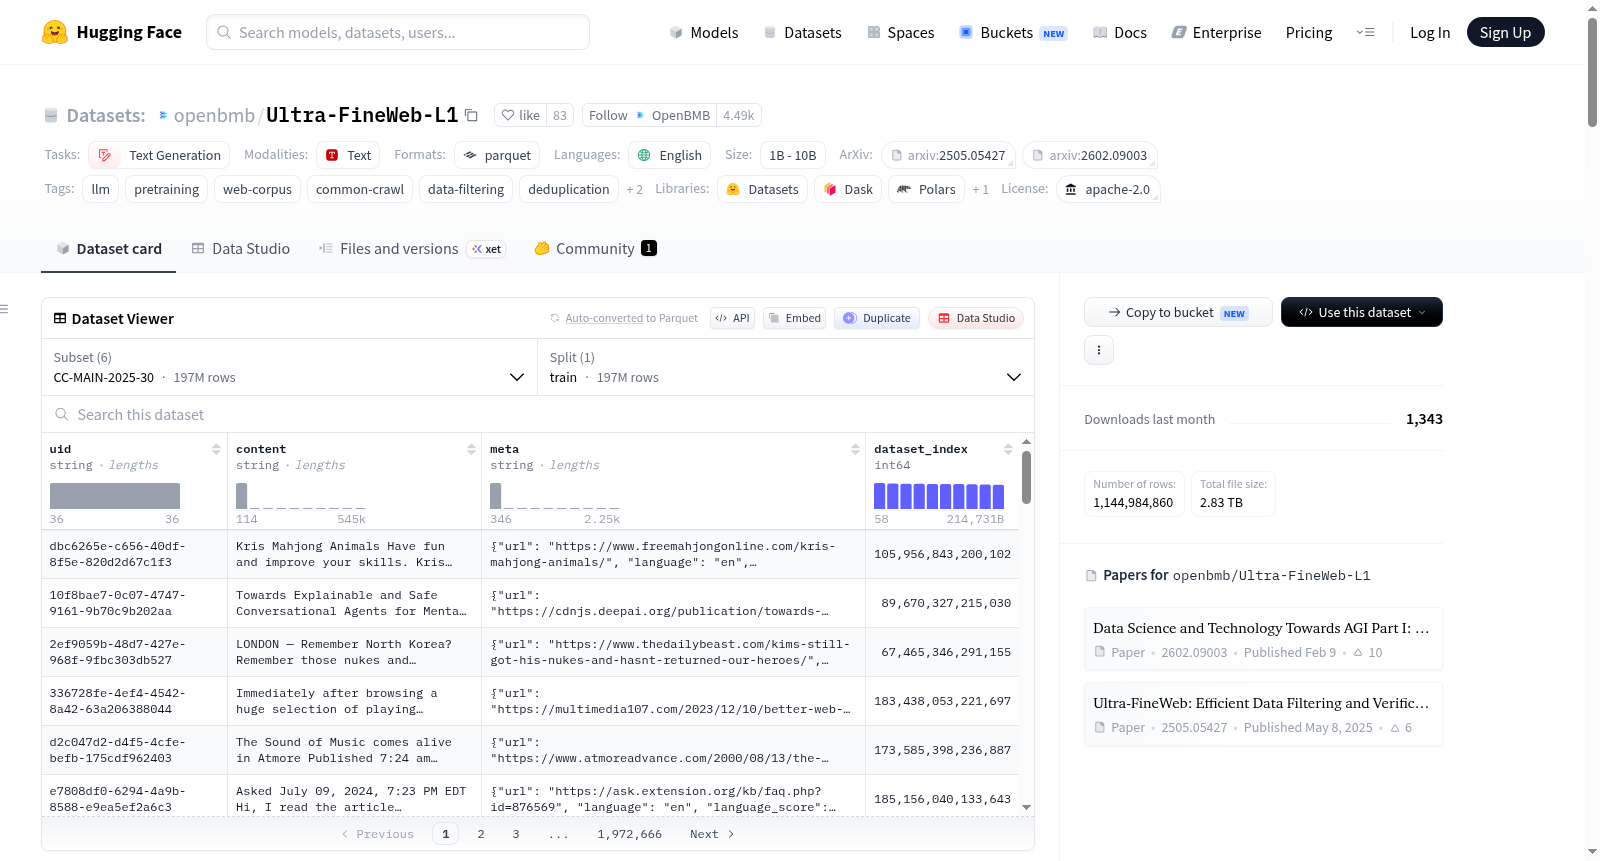
Ultra-FineWeb-L1是一个大规模英文网页语料库,基于Common Crawl快照构建,属于UltraData数据管理框架中的L1过滤层,为后续的L2选择和L3精炼提供基础。该数据集在FineWeb处理流程的基础上,升级了主文本提取工具(trafilatura 2.0),并采用UltraData的数据质量检测工具和清洗代理优化规则,对残存HTML、编码损坏、乱码、不可见字符、异常文档长度等问题进行了针对性处理。首个版本包含来自2025年六个Common Crawl快照的超过1万亿token(约11.4亿文档)。数据按Common Crawl快照组织,每个快照作为一个配置,包含训练集。每个样本包含四个字段:uid(字符串类型,UUID4文档标识符)、content(字符串类型,清洗后的纯文本)、meta(字符串类型,JSON编码的源数据和处理元数据,包括url、language、language_score、warc_record_id、warc_date、source_file)、dataset_index(int64类型,数据集源标识符)。该数据集适用于大型语言模型的预训练(文本生成任务)。实验表明,在MiniCPM5-1B模型上训练20B token后,Ultra-FineWeb-L1在12个基准测试上的六类别宏观平均得分和12任务微观平均得分分别达到9.668%和9.180%,优于FineWeb的9.033%和8.484%。许可证为Apache 2.0,用户需遵守原始网页内容的权利和许可。
Ultra-FineWeb-L1 is a large-scale English web corpus built from Common Crawl snapshots, serving as the L1 filtering layer within the UltraData data management framework, providing a foundation for subsequent L2 selection and L3 refinement. Building upon the FineWeb pipeline, it upgrades the main text extraction tool (trafilatura 2.0) and leverages UltraDatas data quality detection tools and cleaning agent optimization rules to address issues such as residual HTML, encoding corruption, garbled text, invisible characters, and abnormal document lengths. The first release contains over 1 trillion tokens (approximately 1.14 billion documents) from six Common Crawl snapshots in 2025. Data is organized by Common Crawl snapshots, each snapshot as a configuration containing a training set. Each sample includes four fields: uid (string type, UUID4 document identifier), content (string type, cleaned plain text), meta (string type, JSON-encoded source data and processing metadata including url, language, language_score, warc_record_id, warc_date, source_file), and dataset_index (int64 type, dataset source identifier). The dataset is suitable for pre-training large language models (text generation tasks). Experiments show that after training 20B tokens on the MiniCPM5-1B model, Ultra-FineWeb-L1 achieves 9.668% six-category macro average score and 9.180% 12-task micro average score on 12 benchmarks, outperforming FineWebs 9.033% and 8.484%. License is Apache 2.0, and users must comply with the rights and licenses of the original web content.
Ultra-FineWeb-L1 数据集概述
基本信息
- 数据集名称:Ultra-FineWeb-L1
- 语言:英语
- 许可证:Apache 2.0
- 规模:包含超过1万亿个token,约11.4亿个文档
- 任务类别:文本生成
- 发布时间:2026年8月20日
- 发布机构:OpenBMB
数据集简介
Ultra-FineWeb-L1 是一个大规模英语网络语料库,基于 Common Crawl 快照构建。在 UltraData 的 L0-L4 分级数据管理框架中,它作为 L1 过滤层,为后续的 L2 精选和 L3 精炼提供基础。该数据集在 FineWeb 处理流水线的基础上进行了升级,包含六个 2025 年的 Common Crawl 快照,是目前覆盖最新 Common Crawl 快照(截至 CC-MAIN-2025-51)的开源网络预训练数据集。
数据处理流水线
每个 Common Crawl 转储独立处理,包含以下六个步骤:
- 页面和正文提取:使用 trafilatura 2.0 提取纯文本,排除评论、导航栏等非主要内容
- 语言过滤:使用 fastText 语言识别,保留高置信度的英文文档
- 启发式过滤:基于 FineWeb 的启发式过滤方法,处理重复、低质量文档、样板文本和异常行结构
- 敏感字段替换:将检测到的邮箱、IP 地址、电话号码、身份证号和信用卡号替换为有效占位符
- MinHash 去重:在每个 Common Crawl 转储内进行近似重复文档识别(与 FineWeb 一致,独立于各转储内进行)
- 定制化清洗:使用 UltraData 的数据质量检查工具和清洗智能体,处理残留 HTML、编码损坏和乱码、不可见字符、损坏内容及异常文档长度
数据集结构
数据集按 Common Crawl 转储组织,包含以下配置:
- CC-MAIN-2025-30
- CC-MAIN-2025-33
- CC-MAIN-2025-38
- CC-MAIN-2025-43
- CC-MAIN-2025-47
- CC-MAIN-2025-51
每个配置均包含训练分割,文件格式为 Parquet。
数据字段
| 字段 | 类型 | 描述 |
|---|---|---|
uid |
string | UUID4 文档标识符 |
content |
string | 清洗后的纯文本文档 |
meta |
string | JSON 编码的源和处理元数据,包括 url、language、language_score、warc_record_id、warc_date 和 source_file |
dataset_index |
int64 | 数据集源标识符 |
实验结果
在 MiniCPM5-1B 模型上训练 200 亿 token 进行评测:
- Ultra-FineWeb-L1 六类宏平均得分为 9.668%,12 任务微平均得分为 9.180%
- 相比 FineWeb(9.033% / 8.484%),宏平均提升 0.635 个百分点,微平均提升 0.696 个百分点
- 经过 L2 质量筛选后(Ultra-FineWeb-from-L1),宏平均达 10.379%,微平均达 9.798%,表明 L1 清洗与后续质量筛选具有互补效益
关联数据集
- Ultra-FineWeb:L2 精选数据,包含约 1 万亿英文 token 和 1200 亿中文 token
- Ultra-FineWeb-L3:L3 精炼数据,包含 4000 亿+英文 token 和 2000 亿+中文 token
使用须知
- 数据集源于网络内容,用户需遵守原始来源的权利、许可和相关条款
- 未经原作者书面许可,禁止任何机构或第三方平台直接转发、镜像、重新托管或商业性重新打包发布该项目成果