nb-asr-mt-filtered
收藏资源简介:
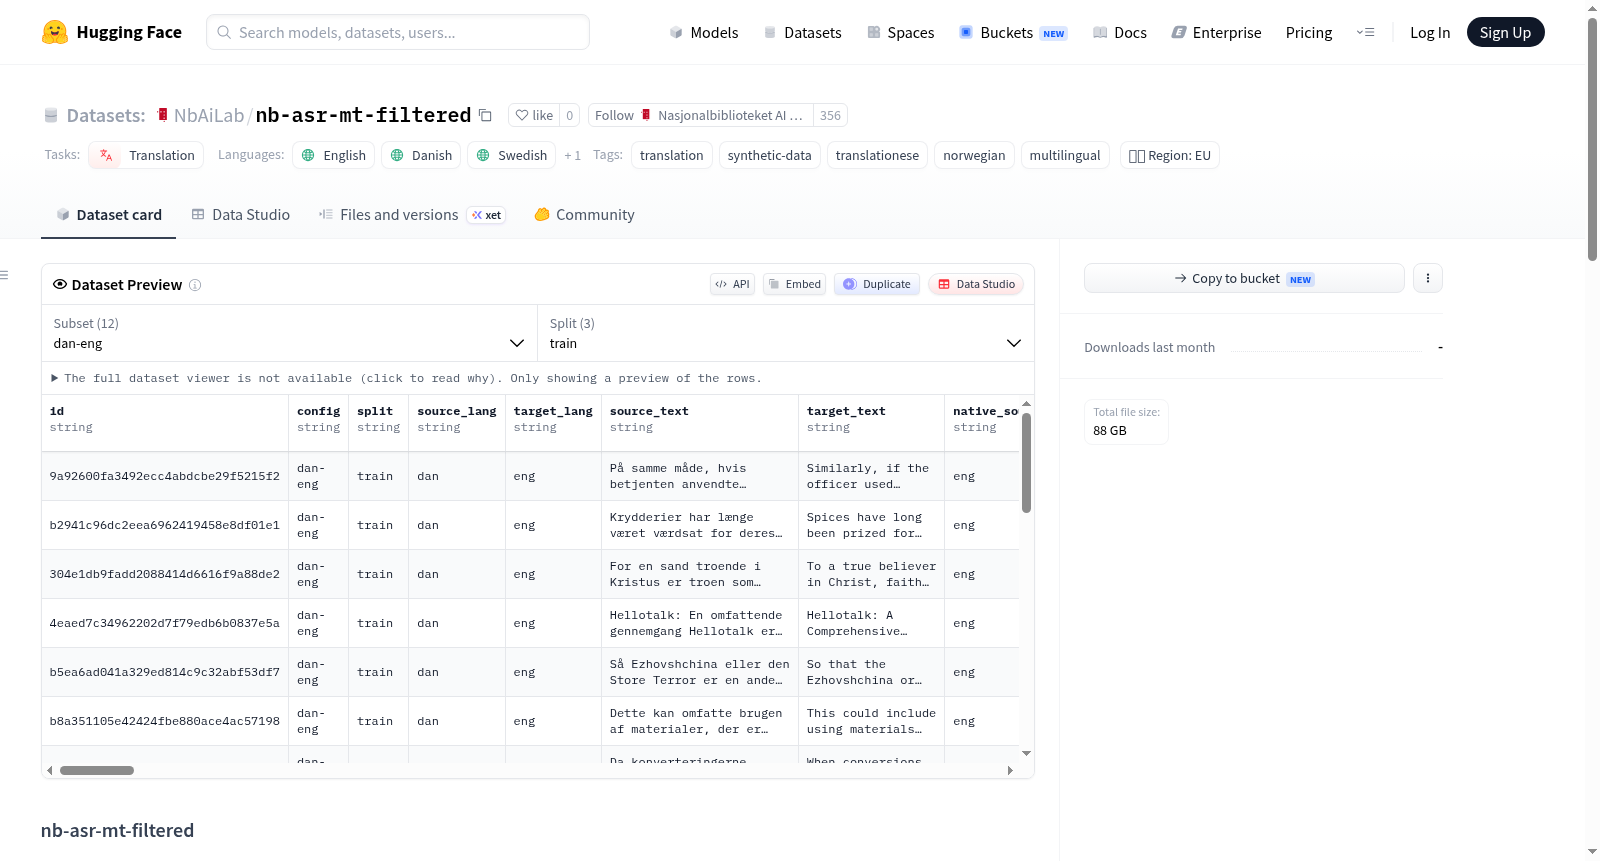
nb-asr-mt-filtered 是一个为NB-ASR项目内部使用而生成的机器翻译清单数据集,目前仍处于积极开发阶段。该数据集基于翻译腔(translationese)处理流程构建,采用反向使用合成数据的核心构建规则:将语言X的母语文本文本翻译成合成语言Y,生成的语料行用作Y到X的训练数据,因此监督目标始终是母语文本,而源端可能包含翻译腔伪影。该数据集是过滤后的变体,应用了保守的多语言双语文本嵌入完整性过滤器,以移除严重的源-目标不匹配情况,同时保持广泛的覆盖范围。数据生成过程涉及四种模型家族(如google/translategemma-4b-it、Qwen/Qwen3.6-35B-A3B-FP8等)生成翻译路线,并使用不同的模型进行回译。数据分割基于配置和源块ID确定,采用95%训练集、2.5%验证集和2.5%测试集的固定比例。每行记录保留了模型ID、版本、验证元数据、使用元数据、时间元数据、母语原始文本、枢轴翻译文本和回译文本。与基础产品nb-asr-mt相比,nb-asr-mt-filtered额外应用了保守的多语言嵌入完整性过滤器,以移除明显的幻觉、截断伪影、解析错误和错误语言失败。还有一个更严格的变体nb-asr-mt-gold,在母语原文和回译文之间使用相同语言嵌入相似性检查,旨在获得高置信度的有用覆盖。数据集总规模为10,814,726行,包含12种语言对配置,涵盖英语(eng)、丹麦语(dan)、瑞典语(swe)和挪威语(nob)之间的双向翻译组合,例如eng-nob(1,811,476行)、nob-eng(593,810行)、swe-eng(590,793行)等。该数据集旨在用于机器翻译训练和翻译腔感知数据构建研究,在训练时,应使用source_text作为输入,target_text作为监督的母语目标。
nb-asr-mt-filtered is a machine translation list dataset generated for internal use within the NB-ASR project and is still under active development. The dataset is built based on a translationese processing pipeline, employing a core construction rule of reverse usage of synthetic data: translating native language texts from language X into synthetic language Y, with the generated corpus lines used as training data for Y to X translation. Thus, the supervised target is always the native text, while the source may contain translationese artifacts. This dataset is a filtered variant that applies a conservative multilingual bilingual text embedding integrity filter to remove severe source-target mismatches while maintaining broad coverage. The data generation process involves four model families (e.g., google/translategemma-4b-it, google/translategemma-12b-it, BSC-LT/salamandraTA-7b-instruct, Qwen/Qwen3.6-35B-A3B-FP8) generating translation routes on Olivia, with back-translation using different models. Data splitting is determined based on (configuration, source chunk ID) with a fixed ratio of 95% training set, 2.5% validation set, and 2.5% test set. Each row in the dataset retains model ID, version, validation metadata, usage metadata, temporal metadata, native original text, pivot translation text, and back-translation text. Compared to the base product nb-asr-mt (which only retains rows with successful forward translation, non-empty source/target texts, and passing conservative language ID guardrails), nb-asr-mt-filtered additionally applies a conservative multilingual embedding integrity filter to remove obvious hallucinations, truncation artifacts, parsing errors, and incorrect language failures. There is also a stricter variant, nb-asr-mt-gold, which uses same-language embedding similarity checks between native original and back-translation texts, aiming for high-confidence useful coverage rather than exact string equality. The total dataset size is 10,814,726 rows, containing 12 language pair configurations covering bidirectional translation combinations among English (eng), Danish (dan), Swedish (swe), and Norwegian (nob), such as eng-nob (1,811,476 rows), nob-eng (593,810 rows), swe-eng (590,793 rows), etc. The dataset is intended for machine translation training and translationese-aware data construction research. During training, source_text should be used as input and target_text as the supervised native target.