VideoRefer-700K
收藏资源简介:
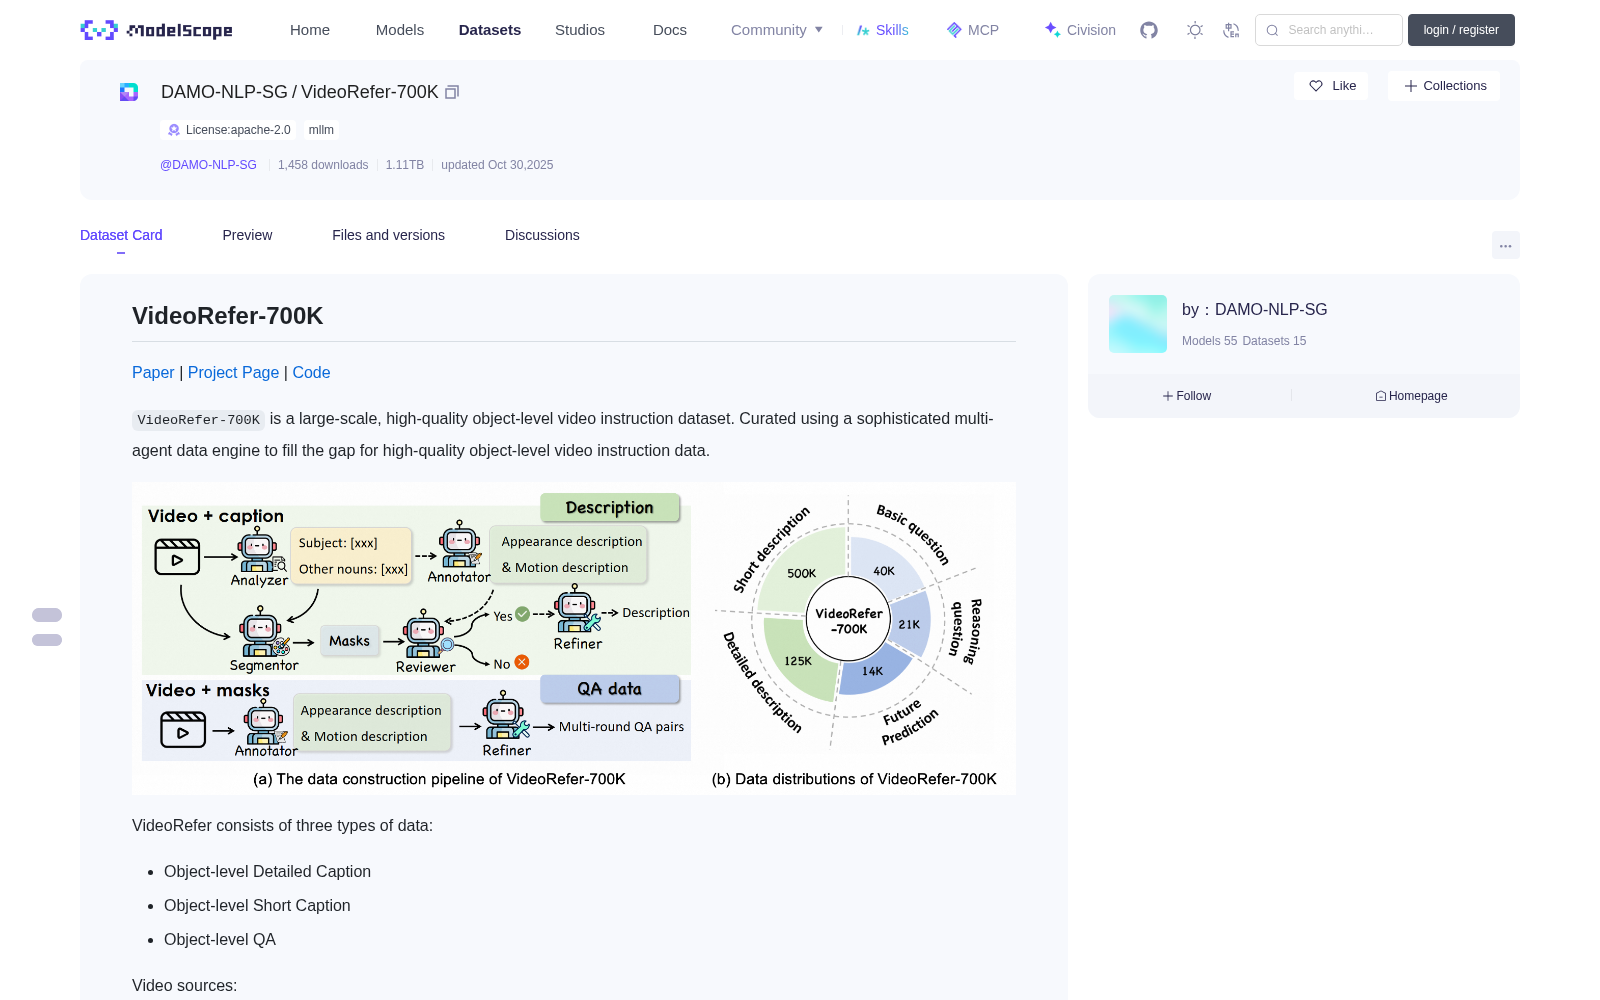
# VideoRefer-700K [Paper](https://huggingface.co/papers/2510.23603) | [Project Page](https://circleradon.github.io/PixelRefer) | [Code](https://github.com/alibaba-damo-academy/PixelRefer) `VideoRefer-700K` is a large-scale, high-quality object-level video instruction dataset. Curated using a sophisticated multi-agent data engine to fill the gap for high-quality object-level video instruction data.  VideoRefer consists of three types of data: - Object-level Detailed Caption - Object-level Short Caption - Object-level QA Video sources: - Detailed&Short Caption - [Panda-70M](https://snap-research.github.io/Panda-70M/). - QA - [MeViS](https://codalab.lisn.upsaclay.fr/competitions/15094) - [A2D](https://web.eecs.umich.edu/~jjcorso/r/a2d/index.html#downloads) - [Youtube-VOS](https://competitions.codalab.org/competitions/29139#participate-get_data) Data format: ```json [ { "video": "videos/xxx.mp4", "conversations": [ { "from": "human", "value": "<video> What is the relationship of <region> and <region>?" }, { "from": "gpt", "value": "...." }, ... ], "annotation":[ //object1 { "frame_idx":{ "segmentation": { //rle format or polygon } } "frame_idx":{ "segmentation": { //rle format or polygon } } }, //object2 { "frame_idx":{ "segmentation": { //rle format or polygon } } }, ... ] } ``` Dataset samples:  ## Citation If you find PixelRefer Series useful for your research and applications, please cite using this BibTeX: ```bibtex @article{yuan2025pixelrefer, title = {PixelRefer: A Unified Framework for Spatio-Temporal Object Referring with Arbitrary Granularity}, author = {Yuqian Yuan and Wenqiao Zhang and Xin Li and Shihao Wang and Kehan Li and Wentong Li and Jun Xiao and Lei Zhang and Beng Chin Ooi}, year = {2025}, journal = {arXiv}, } @inproceedings{yuan2025videorefer, title = {Videorefer Suite: Advancing Spatial-Temporal Object Understanding with Video LLM}, author = {Yuqian Yuan and Hang Zhang and Wentong Li and Zesen Cheng and Boqiang Zhang and Long Li and Xin Li and Deli Zhao and Wenqiao Zhang and Yueting Zhuang and others}, booktitle = {Proceedings of the Computer Vision and Pattern Recognition Conference}, pages = {18970--18980}, year = {2025}, } ```
# VideoRefer-700K [论文](https://huggingface.co/papers/2510.23603) | [项目主页](https://circleradon.github.io/PixelRefer) | [代码](https://github.com/alibaba-damo-academy/PixelRefer) `VideoRefer-700K` 是一款大规模高质量的对象级视频指令数据集。本数据集依托先进的多智能体数据引擎构建,旨在填补高质量对象级视频指令数据的空白。  VideoRefer 包含三类数据: - 对象级详细描述(Object-level Detailed Caption) - 对象级简短描述(Object-level Short Caption) - 对象级问答(Object-level QA) 数据来源: - 详细与简短描述数据来源: - [Panda-70M](https://snap-research.github.io/Panda-70M/) - 问答数据来源: - [MeViS](https://codalab.lisn.upsaclay.fr/competitions/15094) - [A2D](https://web.eecs.umich.edu/~jjcorso/r/a2d/index.html#downloads) - [Youtube-VOS](https://competitions.codalab.org/competitions/29139#participate-get_data) 数据格式: json [ { "video": "videos/xxx.mp4", "conversations": [ { "from": "human", "value": "<video> What is the relationship of <region> and <region>?" }, { "from": "gpt", "value": "...." }, ... ], "annotation":[ //object1 { "frame_idx":{ "segmentation": { //rle format or polygon } }, "frame_idx":{ "segmentation": { //rle format or polygon } } }, //object2 { "frame_idx":{ "segmentation": { //rle format or polygon } } }, ... ] } ] 数据集示例:  引用说明:若您的研究或应用场景中用到了PixelRefer系列数据集,请使用以下BibTeX格式进行引用: bibtex @article{yuan2025pixelrefer, title = {PixelRefer: A Unified Framework for Spatio-Temporal Object Referring with Arbitrary Granularity}, author = {Yuqian Yuan and Wenqiao Zhang and Xin Li and Shihao Wang and Kehan Li and Wentong Li and Jun Xiao and Lei Zhang and Beng Chin Ooi}, year = {2025}, journal = {arXiv}, } @inproceedings{yuan2025videorefer, title = {Videorefer套件:依托视频大语言模型(Video LLM)推进时空对象理解}, author = {Yuqian Yuan and Hang Zhang and Wentong Li and Zesen Cheng and Boqiang Zhang and Long Li and Xin Li and Deli Zhao and Wenqiao Zhang and Yueting Zhuang and others}, booktitle = {Proceedings of the Computer Vision and Pattern Recognition Conference}, pages = {18970--18980}, year = {2025}, }