MathCode-Pile
收藏资源简介:
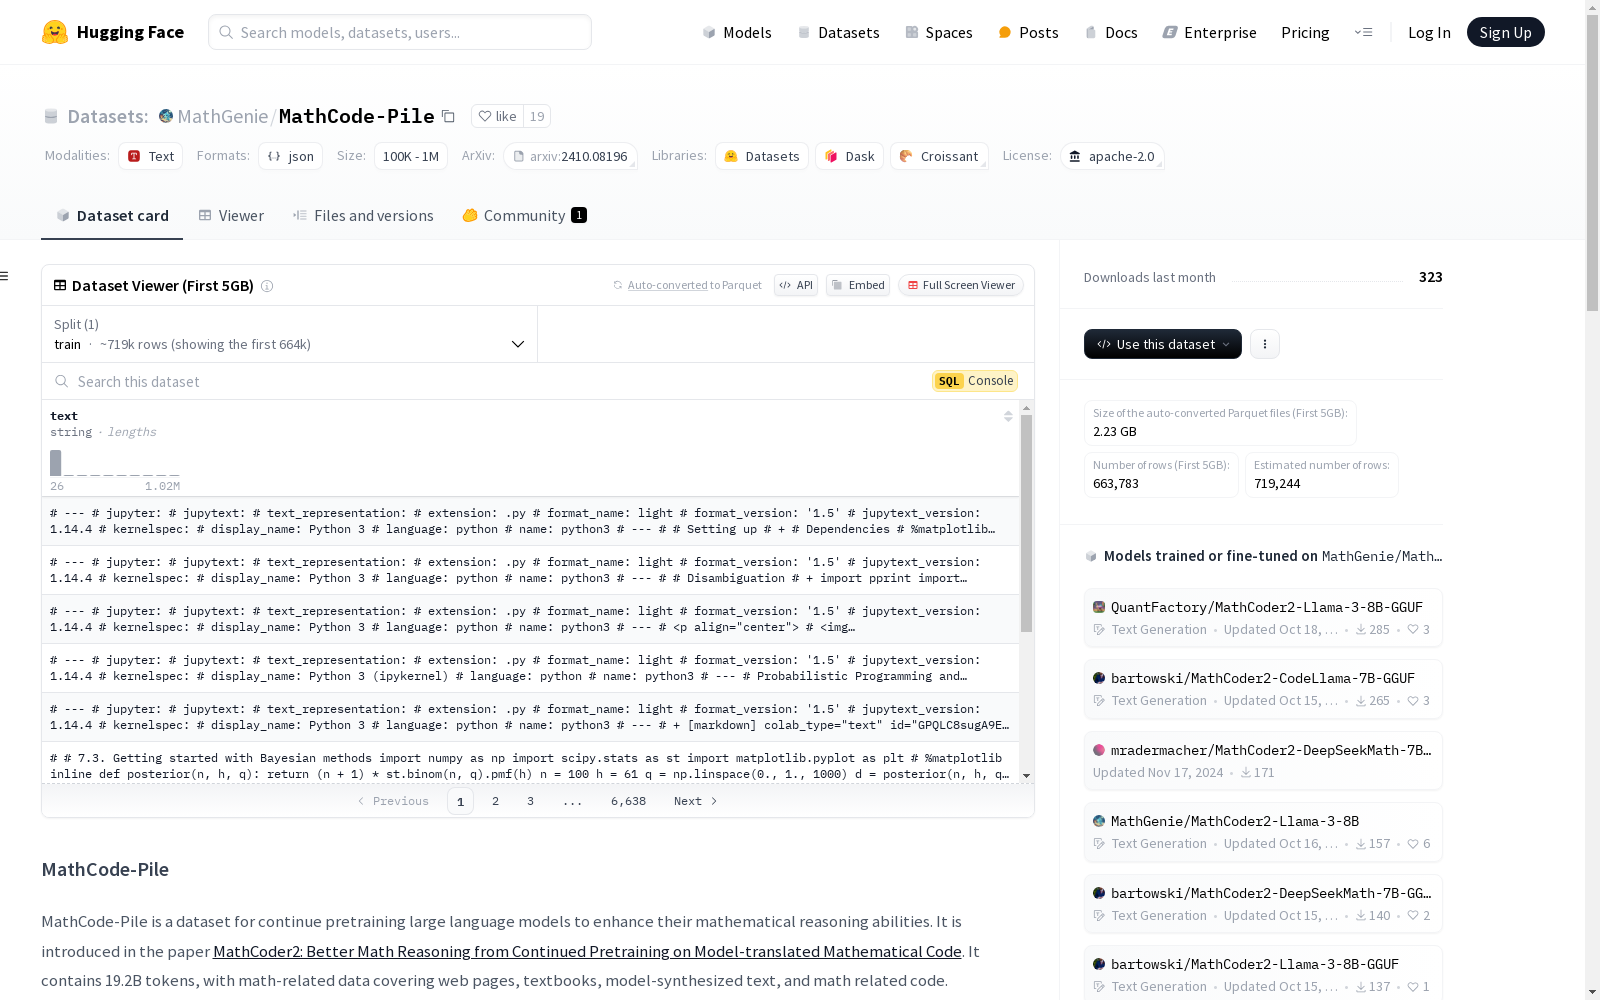
MathCode-Pile是一个用于继续预训练大型语言模型以增强其数学推理能力的数据集。该数据集包含19.2亿个token,涵盖了网页、教科书、模型合成的文本以及与数学相关的代码。数据集的组成部分包括过滤后的OpenWebMath、过滤后的CC-En-math和翻译后的数学代码,目前仅部分发布,其他部分已完全发布。数据集的完整版本将在论文被接受后发布,用户也可以使用数据处理代码生成完整数据集。数据集中的数学代码是通过一种新颖的方法生成的,该方法利用Llama-3.1-70B-Instruct模型提取LaTeX表达式及其相关上下文,并将其翻译成Python代码片段,最终生成包含数学推理步骤和相应代码的数据。
MathCode-Pile is a dataset designed for continued pre-training of large language models to enhance their mathematical reasoning capabilities. It contains 1.92 billion tokens, spanning webpages, textbooks, model-synthesized text, and mathematics-related code. The dataset comprises three core components: filtered OpenWebMath, filtered CC-En-math, and translated mathematical code. Currently, only a subset of the dataset has been publicly released, while the remaining portions have been fully made available. The full version of the dataset will be released upon acceptance of the associated research paper, and users can generate the complete dataset using the provided data processing code. The mathematical code within the dataset is generated through a novel methodology: this approach leverages the Llama-3.1-70B-Instruct model to extract LaTeX expressions and their associated contextual information, then translates these into Python code snippets, ultimately producing samples that incorporate both mathematical reasoning steps and their corresponding code.
MathCode-Pile 数据集概述
数据集简介
MathCode-Pile 是一个用于继续预训练大型语言模型以增强其数学推理能力的数据集。该数据集包含 19.2B 个标记,涵盖网页、教科书、模型合成的文本以及与数学相关的代码。目前,filtered-OpenWebMath、filtered-CC-En-math 和翻译后的数学代码仅部分发布,其他部分已完全发布。完整数据集将在论文接受后发布。
数据组成
MathCode-Pile 包含广泛的数学相关数据。各部分数据集的标记数量如下表所示:

数学代码生成
提出了一种生成大量配对的数学推理步骤及其相应 Python 代码的新方法。通过精心设计的提示,指导 Llama-3.1-70B-Instruct 模型提取 LaTeX 表达式及其相关上下文,包括每个表达式的条件和计算结果。然后,模型将每个推理步骤翻译成捕捉底层推理过程的 Python 代码片段。生成的 Python 代码片段被执行,只有那些成功运行并产生预期结果的代码片段被保留。通过将代码与相应的推理步骤配对,创建最终数据。
模型性能