CLUES
收藏资源简介:
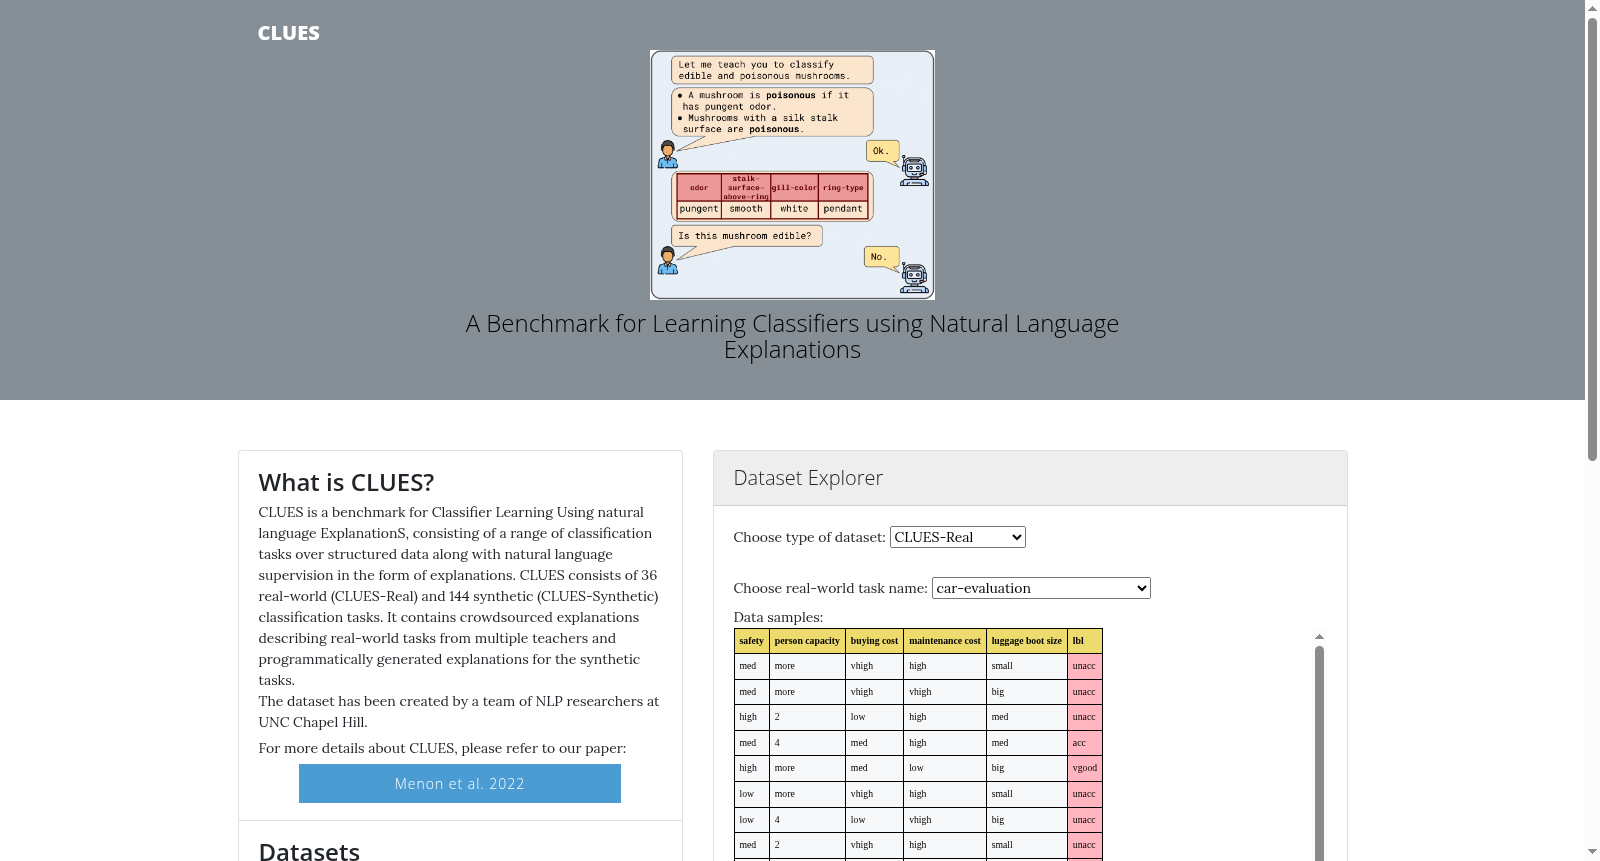
CLUES数据集是一个用于通过自然语言解释学习分类器的基准,由北卡罗来纳大学教堂山分校的研究人员创建。该数据集包含36个真实世界和144个合成分类任务,每个任务都配有自然语言解释。真实世界的任务来自UCI、Kaggle和Wikipedia,而合成任务则是程序生成的。数据集旨在通过解释来指导模型学习,特别是在零样本学习场景中。CLUES数据集的应用领域包括但不限于机器学习模型的可解释性和零样本学习能力的提升,旨在解决模型在未见任务上的泛化问题。
The CLUES dataset is a benchmark for learning classifiers via natural language explanations, created by researchers at the University of North Carolina at Chapel Hill. This dataset contains 36 real-world and 144 synthetic classification tasks, each paired with natural language explanations. The real-world tasks are sourced from UCI, Kaggle, and Wikipedia, while the synthetic tasks are programmatically generated. The dataset is designed to guide model learning through explanations, particularly in zero-shot learning scenarios. Application areas of the CLUES dataset include, but are not limited to, improving the interpretability of machine learning models and their zero-shot learning capabilities, aiming to address the generalization issue of models on unseen tasks.