strl-rollouts-Eenv-Ggen-S0-h50e9202c
收藏资源简介:
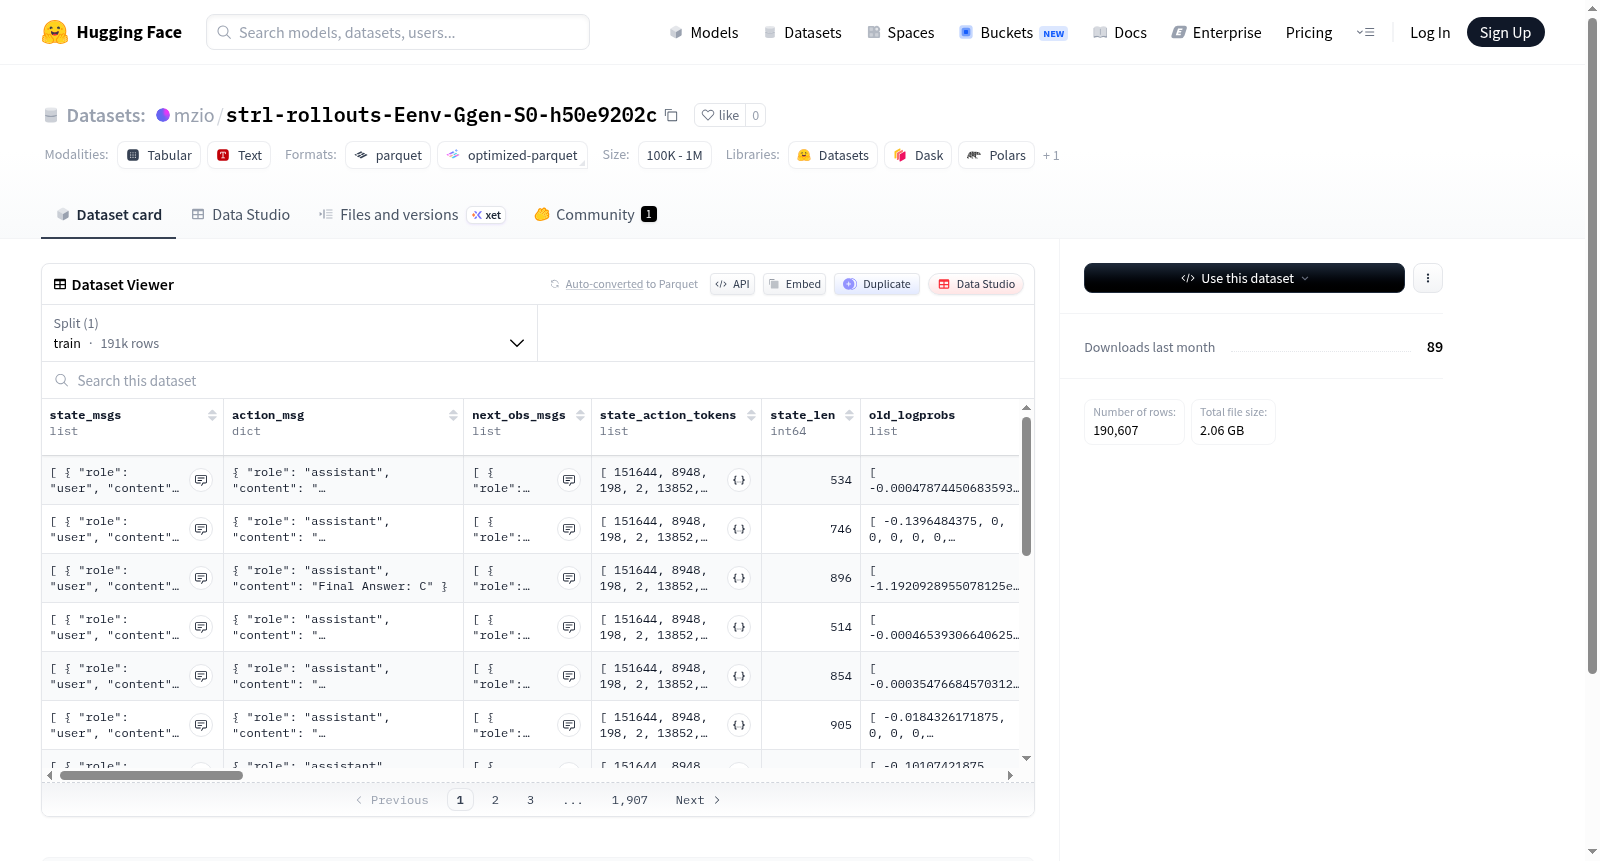
该数据集是一个用于语言模型训练的高结构化数据集,特别适用于强化学习或决策任务。每个样本代表一个交互步骤或轨迹片段,包含丰富的上下文和反馈信息,核心数据包括对话状态消息(state_msgs)、模型采取的动作消息(action_msg)以及后续观察消息(next_obs_msgs),这些通常组织为包含角色和内容的列表。数据集整合了强化学习训练所需的多个要素,如奖励(reward)、完成标志(done)、优势值(advantage)、回报(return_)以及各种计算标志(如return_is_computed)。此外,样本还包含任务定义信息,如系统提示(system_prompt)、可用工具列表(tools,包含工具类型、名称、描述和参数定义)以及任务提示(task_prompt)。其他元数据包括时间步(timestep)、批次ID(batch_id)、样本ID(sample_id)以及分割标识(split,当前仅包含训练集)。数据规模方面,训练集包含188,582个样本,总大小约为2.33GB。该数据集适用于训练或微调语言模型进行序列决策、工具调用、对话生成等任务,并为基于人类反馈的强化学习(RLHF)或类似范式提供格式化的训练数据。
This dataset is a highly structured dataset for language model training, particularly suitable for reinforcement learning or decision-making tasks. Each sample represents an interaction step or trajectory segment, containing rich contextual and feedback information. The core data includes dialogue state messages (state_msgs), action messages taken by the model (action_msg), and subsequent observation messages (next_obs_msgs), which are typically organized as lists with roles and content. The dataset integrates multiple elements required for reinforcement learning training, such as reward (reward), completion flag (done), advantage value (advantage), return (return_), and various computation flags (e.g., return_is_computed). Additionally, samples include task definition information, such as system prompts (system_prompt), available tool lists (tools, containing tool type, name, description, and parameter definitions), and task prompts (task_prompt). Other metadata includes timestep (timestep), batch ID (batch_id), sample ID (sample_id), and split identifier (split, currently only containing the training set). In terms of data scale, the training set contains 188,582 samples, with a total size of approximately 2.33GB. This dataset is suitable for training or fine-tuning language models for tasks such as sequential decision-making, tool calling, dialogue generation, and provides formatted training data for reinforcement learning from human feedback (RLHF) or similar paradigms.
基于您提供的数据集详情页面README内容,以下是对该数据集的总结:
数据集概述
- 数据集名称:strl-rollouts-Eenv-Ggen-S0-h50e9202c
- 存储位置:Hugging Face Datasets(通过链接访问)
- 数据集大小:约2.35 GB(2355398782 字节)
- 下载大小:约2.06 GB(2061191770 字节)
数据划分
- 训练集(train):包含 190,607 条样本,数据大小为 2,355,398,782 字节。
特征字段
该数据集包含丰富的结构化字段,主要用于强化学习或交互式环境中的轨迹数据。主要特征字段如下:
对话与动作相关
- state_msgs:状态消息列表,每条包含
role(字符串)和content(字符串)。 - action_msg:动作消息,包含
role(字符串)和content(字符串)。 - next_obs_msgs:下一步观测消息列表,每条包含
role和content。 - current_state:当前状态消息列表,每条包含
role和content。 - final_outcome:最终结果消息列表,每条包含
role和content。 - system_prompt:系统提示(字符串)。
- task_prompt:任务提示(字符串)。
- tools:工具列表,每个工具包含
type、name、description、parameters(其中参数包含类型和属性)及required字段。
状态与动作标记
- state_action_tokens:状态-动作标记列表(
int64类型)。 - state_len:状态长度(
int64类型)。
奖励与回报相关
- reward:奖励值(
float64类型)。 - return_:回报值(
float64类型)。 - return_is_computed:回报是否已计算(
bool类型)。 - state_returns:状态回报列表(
float64类型)。 - trajectory_returns:轨迹回报列表(
float64类型)。
优势函数相关
- advantage:优势函数值(
float64类型)。 - advantage_is_computed:优势是否已计算(
bool类型)。 - state_advantages:状态优势列表(
float64类型)。 - trajectory_advantages:轨迹优势列表(
float64类型)。
日志与轨迹控制
- old_logprobs:旧对数概率列表(
float64类型)。 - temperature:温度参数(
float64类型)。 - done:是否完成(
bool类型)。 - truncated:是否截断(
bool类型)。 - timestep:时间步(
int64类型)。 - try_step:尝试步骤(
int64类型)。 - batch_id:批次ID(
int64类型)。 - sample_id:样本ID(
int64类型)。 - generation_id:生成ID(
int64类型)。 - split:数据集划分标识(字符串,此处为
train)。
其他标识字段
- constant_reward_group:是否为恒定奖励组(
bool类型)。 - default_context:默认上下文(空列表
null)。 - prior_context:先前上下文(空列表
null)。 - prior_rewards:先前奖励(空列表
null)。 - prior_returns:先前回报(空列表
null)。 - prior_advantages:先前优势(空列表
null)。 - is_train:是否为训练数据(
bool类型)。 - is_icl:是否为上下文学习(
bool类型)。 - is_complete:是否完成(
bool类型)。
数据用途
该数据集可能用于训练或评估强化学习模型、语言模型与环境的交互能力,涵盖状态-动作序列、奖励信号、优势函数以及多轮对话记录。数据集包含完整的轨迹信息,适合用于策略梯度、PPO等算法的离线训练或评估。