Firoj/HumAID
收藏资源简介:
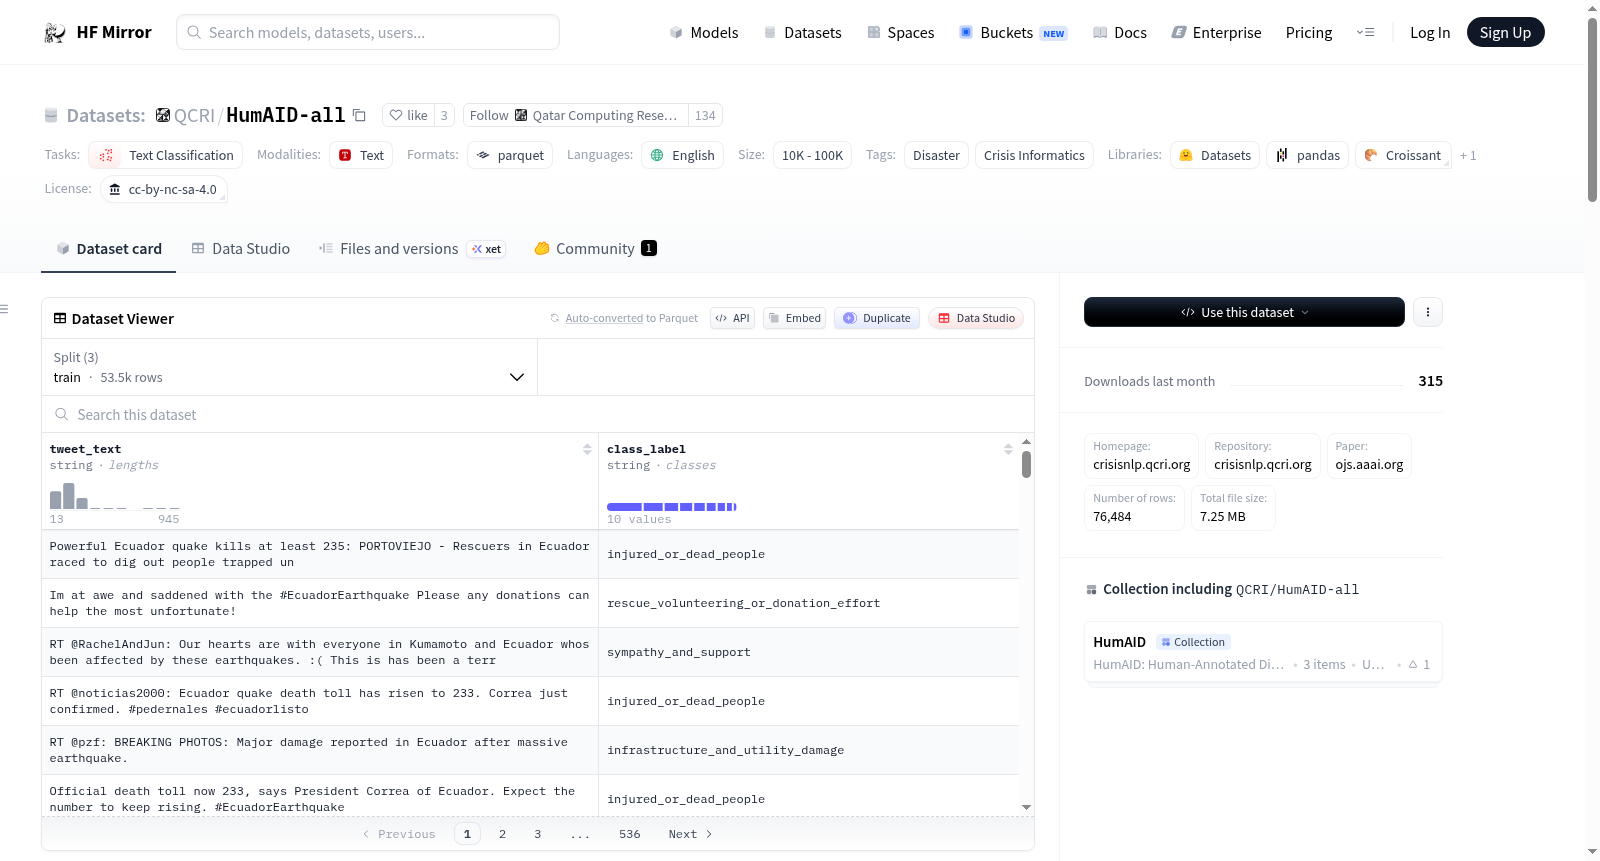
# Dataset Card for HumAID ## Table of Contents - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks](#supported-tasks-and-leaderboards) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Data Instances](#data-instances) - [Data Fields](#data-instances) - [Data Splits](#data-instances) - [Dataset Creation](#dataset-creation) - [Curation Rationale](#curation-rationale) - [Source Data](#source-data) - [Annotations](#annotations) - [Personal and Sensitive Information](#personal-and-sensitive-information) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Social Impact of Dataset](#social-impact-of-dataset) - [Discussion of Biases](#discussion-of-biases) - [Other Known Limitations](#other-known-limitations) - [Additional Information](#additional-information) - [Dataset Curators](#dataset-curators) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) ## Dataset Description - **Homepage:** https://crisisnlp.qcri.org/humaid_dataset - **Repository:** https://crisisnlp.qcri.org/data/humaid/humaid_data_all.zip - **Paper:** https://ojs.aaai.org/index.php/ICWSM/article/view/18116/17919 <!-- - **Leaderboard:** [Needs More Information] --> <!-- - **Point of Contact:** [Needs More Information] --> ### Dataset Summary The HumAID Twitter dataset consists of several thousands of manually annotated tweets that has been collected during 19 major natural disaster events including earthquakes, hurricanes, wildfires, and floods, which happened from 2016 to 2019 across different parts of the World. The annotations in the provided datasets consists of following humanitarian categories. The dataset consists only english tweets and it is the largest dataset for crisis informatics so far. ** Humanitarian categories ** - Caution and advice - Displaced people and evacuations - Dont know cant judge - Infrastructure and utility damage - Injured or dead people - Missing or found people - Not humanitarian - Other relevant information - Requests or urgent needs - Rescue volunteering or donation effort - Sympathy and support The resulting annotated dataset consists of 11 labels. ### Supported Tasks and Benchmark The dataset can be used to train a model for multiclass tweet classification for disaster response. The benchmark results can be found in https://ojs.aaai.org/index.php/ICWSM/article/view/18116/17919. Dataset is also released with event-wise and JSON objects for further research. Full set of the dataset can be found in https://dataverse.harvard.edu/dataset.xhtml?persistentId=doi:10.7910/DVN/A7NVF7 ### Languages English ## Dataset Structure ### Data Instances ``` { "tweet_text": "@RT_com: URGENT: Death toll in #Ecuador #quake rises to 233 \u2013 President #Correa #1 in #Pakistan", "class_label": "injured_or_dead_people" } ``` ### Data Fields * tweet_text: corresponds to the tweet text. * class_label: corresponds to a label assigned to a given tweet text ### Data Splits * Train * Development * Test ## Dataset Creation <!-- ### Curation Rationale --> ### Source Data #### Initial Data Collection and Normalization Tweets has been collected during several disaster events. ### Annotations #### Annotation process AMT has been used to annotate the dataset. Please check the paper for a more detail. #### Who are the annotators? - crowdsourced <!-- ## Considerations for Using the Data --> <!-- ### Social Impact of Dataset --> <!-- ### Discussion of Biases --> <!-- [Needs More Information] --> <!-- ### Other Known Limitations --> <!-- [Needs More Information] --> ## Additional Information ### Dataset Curators Authors of the paper. ### Licensing Information - cc-by-nc-4.0 ### Citation Information ``` @inproceedings{humaid2020, Author = {Firoj Alam, Umair Qazi, Muhammad Imran, Ferda Ofli}, booktitle={Proceedings of the Fifteenth International AAAI Conference on Web and Social Media}, series={ICWSM~'21}, Keywords = {Social Media, Crisis Computing, Tweet Text Classification, Disaster Response}, Title = {HumAID: Human-Annotated Disaster Incidents Data from Twitter}, Year = {2021}, publisher={AAAI}, address={Online}, } ```
# HumAID 数据集卡片 ## 目录 - [数据集描述](#dataset-description) - [数据集概述](#dataset-summary) - [支持任务与评测基准](#supported-tasks-and-leaderboards) - [语言](#languages) - [数据集结构](#dataset-structure) - [数据实例](#data-instances) - [数据字段](#data-fields) - [数据划分](#data-splits) - [数据集构建](#dataset-creation) - [构建初衷](#curation-rationale) - [源数据](#source-data) - [标注信息](#annotations) - [个人与敏感信息](#personal-and-sensitive-information) - [数据集使用注意事项](#considerations-for-using-the-data) - [数据集的社会影响](#social-impact-of-dataset) - [偏见讨论](#discussion-of-biases) - [其他已知局限性](#other-known-limitations) - [附加信息](#additional-information) - [数据集维护者](#dataset-curators) - [授权信息](#licensing-information) - [引用信息](#citation-information) ## 数据集描述 - **主页**:https://crisisnlp.qcri.org/humaid_dataset - **代码仓库**:https://crisisnlp.qcri.org/data/humaid/humaid_data_all.zip - **相关论文**:https://ojs.aaai.org/index.php/ICWSM/article/view/18116/17919 <!-- - **评测基准**:[需补充更多信息] --> <!-- - **联系方式**:[需补充更多信息] --> ### 数据集概述 HumAID 推特(Twitter)数据集包含数千条人工标注的推文,这些推文采集自2016年至2019年间全球19起重大自然灾害事件,涵盖地震、飓风、山火与洪水等灾害类型。本数据集的标注涵盖以下人道主义相关类别。本数据集仅包含英文推文,是目前危机信息学领域规模最大的公开数据集。 **人道主义类别** - 警示与建议 - 流离失所者与疏散行动 - 无法判断 - 基础设施与公共设施损毁 - 人员伤亡 - 人员失踪/获救 - 非人道主义相关内容 - 其他相关信息 - 请求或紧急需求 - 救援、志愿或捐赠行动 - 同情与支持 最终的标注数据集共包含11个分类标签。 ### 支持任务与评测基准 本数据集可用于训练面向灾害响应的多分类推文分类模型。相关评测基准结果可参见https://ojs.aaai.org/index.php/ICWSM/article/view/18116/17919。 本数据集同时提供按事件划分的JSON格式数据,以供后续研究使用。 数据集完整版本可通过以下链接获取:https://dataverse.harvard.edu/dataset.xhtml?persistentId=doi:10.7910/DVN/A7NVF7 ### 语言 英语 ## 数据集结构 ### 数据实例 { "tweet_text": "@RT_com: URGENT: Death toll in #Ecuador #quake rises to 233 u2013 President #Correa #1 in #Pakistan", "class_label": "injured_or_dead_people" } ### 数据字段 * tweet_text:对应推文文本内容 * class_label:对应为给定推文分配的分类标签 ### 数据划分 * 训练集 * 开发集 * 测试集 ## 数据集构建 <!-- ### 构建初衷 --> ### 源数据 #### 初始数据采集与标准化 推文采集自多起灾害事件。 ### 标注信息 #### 标注流程 本数据集采用AMT(Amazon Mechanical Turk,亚马逊机械 Turk)进行标注,详细信息请参见相关论文。 #### 标注人员来源 - 众包标注人员 <!-- ## 数据集使用注意事项 --> <!-- ### 数据集的社会影响 --> <!-- ### 偏见讨论 --> <!-- [需补充更多信息] --> <!-- ### 其他已知局限性 --> <!-- [需补充更多信息] --> ## 附加信息 ### 数据集维护者 论文作者。 ### 授权信息 - cc-by-nc-4.0 ### 引用信息 @inproceedings{humaid2020, Author = {Firoj Alam, Umair Qazi, Muhammad Imran, Ferda Ofli}, booktitle={Proceedings of the Fifteenth International AAAI Conference on Web and Social Media}, series={ICWSM~'21}, Keywords = {Social Media, Crisis Computing, Tweet Text Classification, Disaster Response}, Title = {HumAID: Human-Annotated Disaster Incidents Data from Twitter}, Year = {2021}, publisher={AAAI}, address={Online}, }
数据集概述
数据集名称
HumAID
数据集总结
HumAID Twitter数据集包含数千条手动标注的推文,这些推文收集自2016年至2019年间发生的19次重大自然灾害事件,包括地震、飓风、野火和洪水等。该数据集仅包含英文推文,是目前为止最大的危机信息学数据集。数据集中的标注包括以下人道主义类别:
- 警告和建议
- 流离失所者和疏散
- 不知道无法判断
- 基础设施和公用设施损坏
- 受伤或死亡人员
- 失踪或找到人员
- 非人道主义
- 其他相关信息
- 请求或紧急需求
- 救援志愿或捐赠努力
- 同情和支持
数据集包含11个标签。
支持的任务和基准
该数据集可用于训练多类别推文分类模型,用于灾害响应。基准测试结果可在以下链接找到:HumAID Paper。
语言
英语
数据集结构
数据实例
每个数据实例包含以下字段:
tweet_text: 推文文本class_label: 分配给推文文本的标签
数据字段
tweet_text: 推文内容class_label: 推文的类别标签
数据分割
- 训练集
- 开发集
- 测试集
数据集创建
源数据
推文在多个灾害事件期间收集。
标注
- 标注过程:使用AMT进行数据集标注。
- 标注者:众包
附加信息
数据集管理者
论文作者
许可信息
- cc-by-nc-4.0
引用信息
@inproceedings{humaid2020, Author = {Firoj Alam, Umair Qazi, Muhammad Imran, Ferda Ofli}, booktitle={Proceedings of the Fifteenth International AAAI Conference on Web and Social Media}, series={ICWSM~21}, Keywords = {Social Media, Crisis Computing, Tweet Text Classification, Disaster Response}, Title = {HumAID: Human-Annotated Disaster Incidents Data from Twitter}, Year = {2021}, publisher={AAAI}, address={Online}, }