hi-en-synth-cs
收藏资源简介:
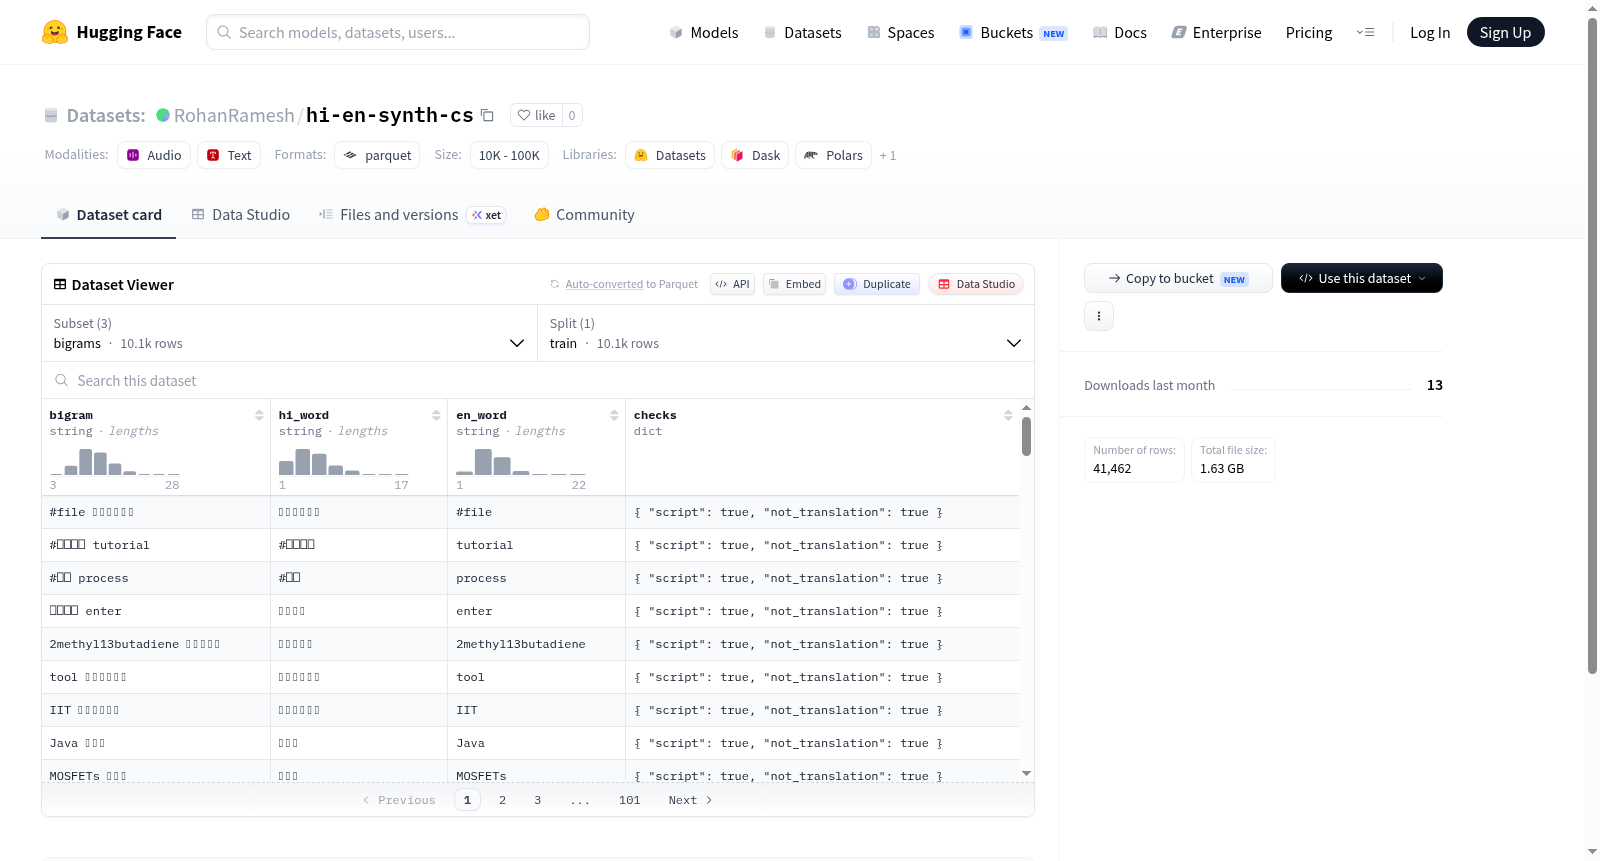
该数据集包含三个配置:bigrams、sentences和synth_t2。bigrams配置包含10,078个训练样本,每个样本包含bigram(字符串)、hi_word(字符串)、en_word(字符串)字段以及一个checks结构体(包含script和not_translation两个布尔值字段),可能用于双语词汇对分析或翻译验证任务。sentences配置包含15,733个训练样本,每个样本包含sent_id(字符串)、text(字符串)、bigram(字符串)和matrix_lang(字符串)字段,可能用于句子级语言分析或跨语言研究。synth_t2配置包含15,651个训练样本,是一个多模态数据集,包含音频(16kHz采样率)、utt_id(字符串)、text(字符串)、dur(浮点数)、speaker(字符串)、lang(字符串)、bigram(字符串)和matrix_lang(字符串)字段,可能用于语音合成、语音-文本对齐或多语言语音处理任务。所有配置均仅提供训练集。
The dataset includes three configurations: bigrams, sentences, and synth_t2. The bigrams configuration contains 10,078 training samples, each with fields including bigram (string), hi_word (string), en_word (string), and a checks struct (with boolean fields script and not_translation), potentially used for bilingual word pair analysis or translation validation tasks. The sentences configuration contains 15,733 training samples, each with fields including sent_id (string), text (string), bigram (string), and matrix_lang (string), potentially used for sentence-level language analysis or cross-linguistic research. The synth_t2 configuration contains 15,651 training samples and is a multimodal dataset, including audio (16kHz sample rate), utt_id (string), text (string), dur (float), speaker (string), lang (string), bigram (string), and matrix_lang (string), potentially used for speech synthesis, speech-text alignment, or multilingual speech processing tasks. All configurations provide only training sets.
数据集概述
- 数据集名称:hi-en-synth-cs
- 数据集地址:https://huggingface.co/datasets/RohanRamesh/hi-en-synth-cs
- 语言:印地语-英语(hi-en)
数据集配置
该数据集包含三个配置(子集),每个配置均为训练集(train):
1. bigrams(二元组)
- 样本数:10,078
- 数据集大小:546,656 字节
- 特征:
bigram(字符串):二元组hi_word(字符串):印地语单词en_word(字符串):英语单词checks(结构体):script(布尔值):脚本检查not_translation(布尔值):非翻译检查
2. sentences(句子)
- 样本数:15,733
- 数据集大小:2,158,287 字节
- 特征:
sent_id(字符串):句子IDtext(字符串):文本内容bigram(字符串):二元组matrix_lang(字符串):矩阵语言
3. synth_t2(合成T2)
- 样本数:15,651
- 数据集大小:1,830,359,817.872 字节
- 特征:
audio(音频):音频数据,采样率为16,000 Hzutt_id(字符串):话语IDtext(字符串):文本内容dur(浮点数):持续时间speaker(字符串):说话人lang(字符串):语言bigram(字符串):二元组matrix_lang(字符串):矩阵语言