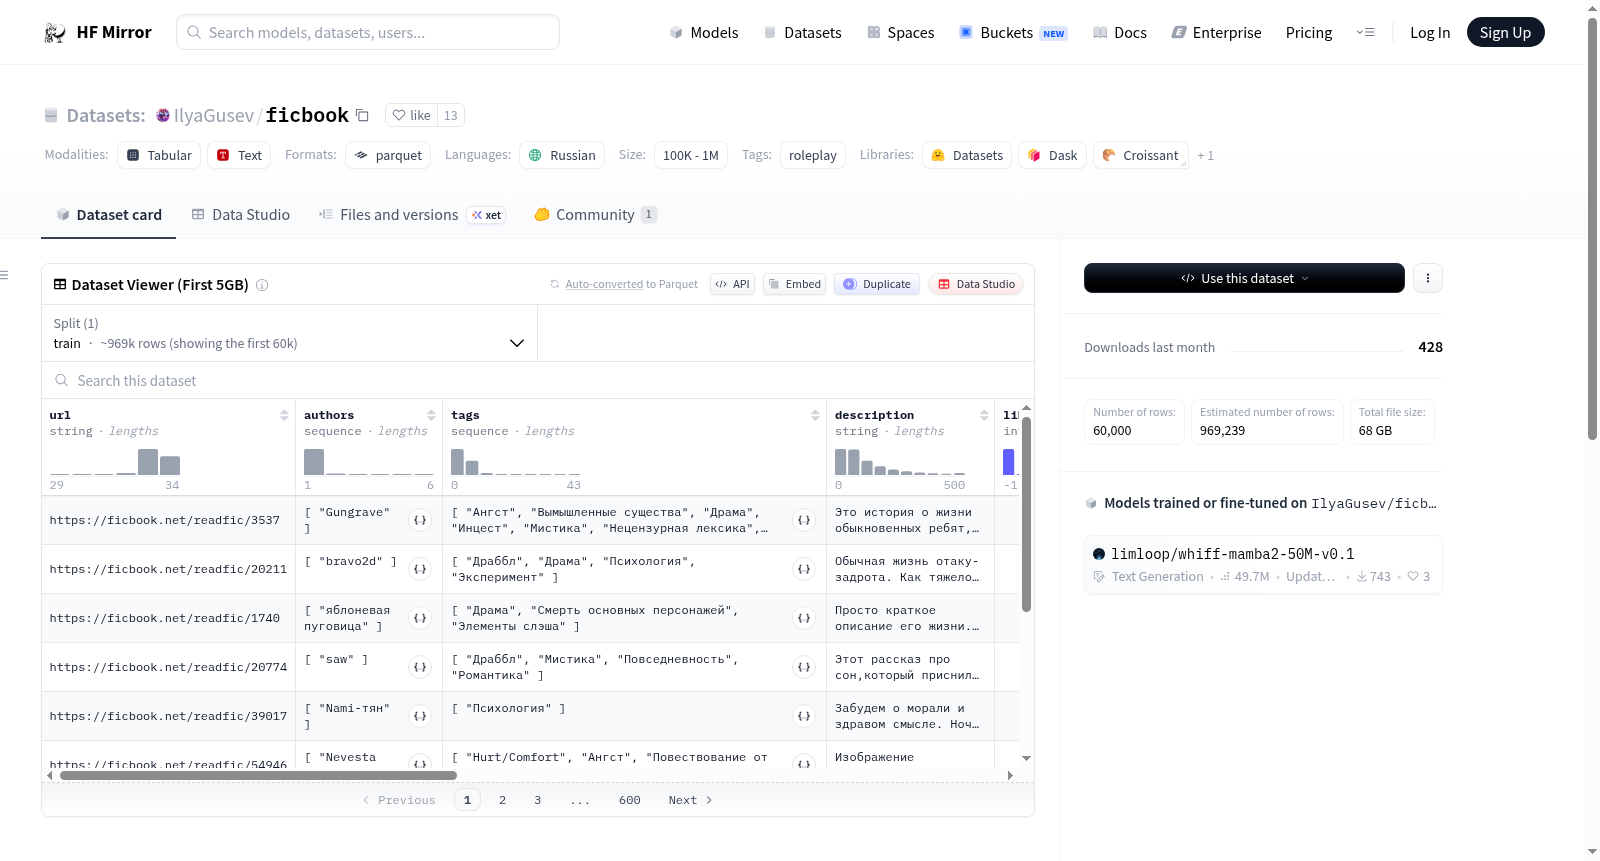
IlyaGusev/ficbook
收藏资源简介:
--- dataset_info: features: - name: url dtype: string - name: authors sequence: string - name: tags sequence: string - name: description dtype: string - name: likes dtype: int64 - name: parts list: - name: clean_text dtype: string - name: date dtype: string - name: text dtype: string - name: title dtype: string - name: url dtype: string - name: part_count dtype: int64 - name: title dtype: string - name: rating dtype: string - name: status dtype: string - name: direction dtype: string - name: category dtype: string - name: pairing dtype: string splits: - name: train num_bytes: 133011363906 num_examples: 1390475 download_size: 68013121186 dataset_size: 133011363906 language: - ru pretty_name: Ficbook Refined tags: - not-for-all-audiences - roleplay task_categories: - text-generation size_categories: - 100K<n<1M --- # Ficbook dataset ## Table of Contents - [Table of Contents](#table-of-contents) - [Description](#description) - [Usage](#usage) - [Personal and Sensitive Information](#personal-and-sensitive-information) ## Description **Summary:** Dataset of 1.4M fan fiction stories from [ficbook.net](https://ficbook.net/). Dataset collection is still in progress. **Script:** [create_ficbook.py](https://github.com/IlyaGusev/rulm/blob/master/data_processing/create_ficbook.py) **Point of Contact:** [Ilya Gusev](phoenixilya@gmail.com) **Languages:** Mostly Russian ## Usage Dataset iteration: ```python from datasets import load_dataset dataset = load_dataset('IlyaGusev/ficbook', split="train", streaming=True) for example in dataset: print(example["parts"][0]["clean_text"]) ``` ## Personal and Sensitive Information Information about the original authors is included in the dataset where possible. Many stories from the dataset contain NSFW content.
dataset_info: 数据集信息: 特征列表: - 字段名:url,数据类型:字符串 - 字段名:authors,数据类型:字符串序列 - 字段名:tags,数据类型:字符串序列 - 字段名:description,数据类型:字符串 - 字段名:likes,数据类型:64位整数 - 字段名:parts,数据类型:列表,包含子字段: - 字段名:clean_text,数据类型:字符串 - 字段名:date,数据类型:字符串 - 字段名:text,数据类型:字符串 - 字段名:title,数据类型:字符串 - 字段名:url,数据类型:字符串 - 字段名:part_count,数据类型:64位整数 - 字段名:title,数据类型:字符串 - 字段名:rating,数据类型:字符串 - 字段名:status,数据类型:字符串 - 字段名:direction,数据类型:字符串 - 字段名:category,数据类型:字符串 - 字段名:pairing,数据类型:字符串 数据集划分: - 划分名称:train(训练集),占用字节数:133011363906,样本数量:1390475 下载大小:68013121186字节 数据集总大小:133011363906字节 语言:俄语 展示名称:Ficbook Refined 标签: - not-for-all-audiences(全年龄段不适宜) - roleplay(角色扮演) 任务类别: - text-generation(文本生成) 规模类别:100K<n<1M(样本量介于10万至100万之间) # Ficbook数据集 ## 目录 - [目录](#目录) - [数据集说明](#数据集说明) - [使用方法](#使用方法) - [个人与敏感信息](#个人与敏感信息) ## 数据集说明 **摘要:** 该数据集包含来自[ficbook.net](https://ficbook.net/)的140万篇同人小说故事,数据集收集工作仍在进行中。 **数据处理脚本:** [create_ficbook.py](https://github.com/IlyaGusev/rulm/blob/master/data_processing/create_ficbook.py) **联系人:** [Ilya Gusev](phoenixilya@gmail.com) **语言:** 以俄语为主 ## 使用方法 数据集迭代示例: python from datasets import load_dataset dataset = load_dataset('IlyaGusev/ficbook', split="train", streaming=True) for example in dataset: print(example["parts"][0]["clean_text"]) ## 个人与敏感信息 数据集尽可能保留了原作者的相关信息。数据集中的多篇故事包含不适合全年龄段(Not Safe For Work, NSFW)内容。
Ficbook 数据集
数据集信息
特征
- url: 字符串类型
- authors: 字符串序列
- tags: 字符串序列
- description: 字符串类型
- likes: 64位整数类型
- parts: 列表类型
- clean_text: 字符串类型
- date: 字符串类型
- text: 字符串类型
- title: 字符串类型
- url: 字符串类型
- part_count: 64位整数类型
- title: 字符串类型
- rating: 字符串类型
- status: 字符串类型
- direction: 字符串类型
- category: 字符串类型
- pairing: 字符串类型
分割
- train: 包含1390475个样本,总字节数为133011363906
大小
- 下载大小: 68013121186字节
- 数据集大小: 133011363906字节
语言
- 俄语
标签
- not-for-all-audiences
- roleplay
任务类别
- 文本生成
大小类别
- 100K<n<1M
描述
摘要: 来自ficbook.net的140万篇同人小说数据集。数据集收集仍在进行中。
联系人: Ilya Gusev
语言: 主要是俄语
使用
数据集迭代示例: python from datasets import load_dataset dataset = load_dataset(IlyaGusev/ficbook, split="train", streaming=True) for example in dataset: print(example["parts"][0]["clean_text"])
个人和敏感信息
数据集中包含原作者信息(如果可能)。许多故事包含NSFW内容。