minicpm5-sft3-3turn
收藏资源简介:
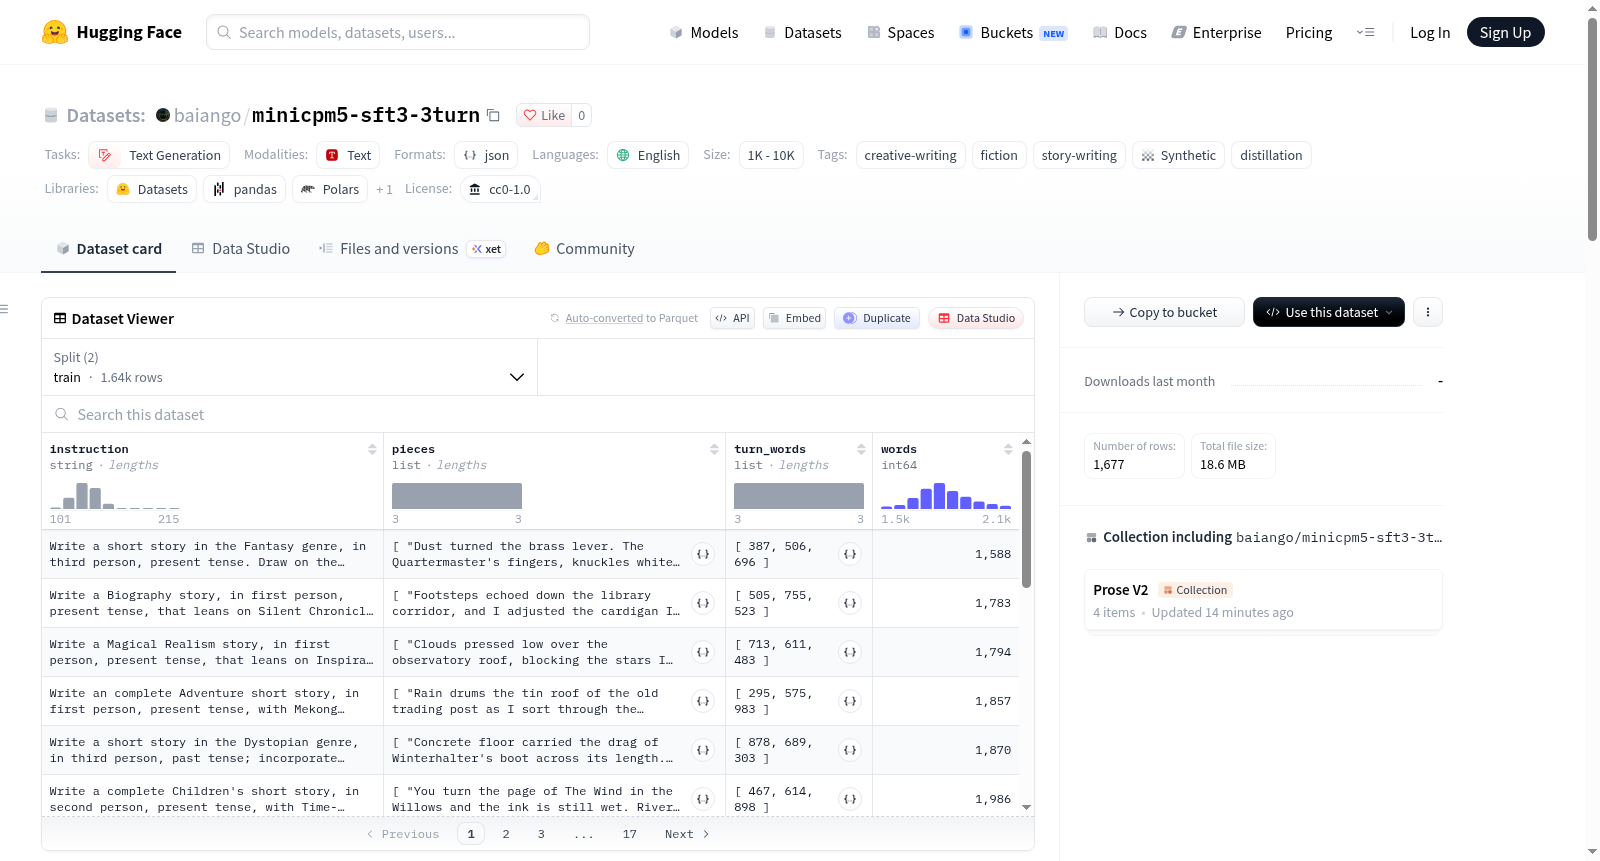
该数据集名为 minicpm5-sft3-3turn,是用于英文小说三回合故事写作任务的训练与验证数据。它属于 baiango/minicpm5-ul4b-story 模型的 sft3 微调阶段,所有故事文本均通过从更强的教师大语言模型进行知识蒸馏生成。数据集共有两个配置:data3 包含1637条训练样本和40条验证样本,总故事字数约300万词(字数范围1503-2099,中位数1781),每条记录包括一个模板化的写作指令,以及三段连续的故事段落(pieces),并附带每轮计划的词数(turn_words)和记录的总词数(words);data3r_mix 包含258条训练样本和40条验证样本(验证集与data3相同),是RAFT实验的混合数据,包含54条来自拒绝采样的三段式故事以及150条来自DAgger流程的原始数据,额外有奖励分数(R)和层级(tier)。指令模板基于一个参数网格:34种体裁 × 第一/二/三人称 × 过去/现在时 × 两个风味标签,并使用6种不同的措辞变体呈现。数据完全合成,无人工筛选,适合用于训练故事写作模型;但需注意POV(视角)遵循不完美,且data3中记录的总词数与实际段落词数略有偏差(最大约280词)。数据集以CC0 1.0许可发布。
The dataset is named minicpm5-sft3-3turn, designed for three-turn story writing tasks in English fiction. It belongs to the sft3 fine-tuning stage of the baiango/minicpm5-ul4b-story model, with all story texts generated via knowledge distillation from stronger teacher LLMs. It has two configurations: data3 contains 1,637 training samples and 40 validation samples, with a total story word count of approximately 3 million words (word count range 1503-2099, median 1781). Each record includes a templated writing instruction and three consecutive story pieces, along with planned word counts per turn (turn_words) and total word count (words). data3r_mix contains 258 training samples and 40 validation samples (same validation set as data3), which is a mixed dataset for RAFT experiments, including 54 triple-story pieces from rejection sampling and 150 original data from the DAgger pipeline, with additional reward scores (R) and tiers (tier). The instruction template is based on a parameter grid: 34 genres × first/second/third person × past/present tense × two flavor tags, and presented in 6 different wording variants. The data is fully synthetic without human filtering, suitable for training story writing models; but note that POV (point-of-view) adherence is imperfect, and the recorded total word counts in data3 deviate slightly from actual paragraph word counts (up to ~280 words). The dataset is released under CC0 1.0 license.
minicpm5-sft3-3turn 数据集概述
基本信息
- 数据集地址:https://huggingface.co/datasets/baiango/minicpm5-sft3-3turn
- 别名:MiniCPM5 SFT3 3-Turn Story Writing Data
- 许可证:CC0 1.0(公有领域奉献)
- 任务类别:文本生成(text-generation)
- 语言:英语(en)
- 规模类别:小型(small)
- 标签:creative-writing、fiction、story-writing、synthetic、distillation
数据集用途
该数据集是 baiango/minicpm5-ul4b-story 模型背后 3 轮写作阶梯(stage sft3 diet)的训练/验证数据。每条记录包含一个模板化的写作指令,以及由更强的教师 LLM 蒸馏生成的三段式故事(英语虚构作品)。
配置与数据划分
- 配置名:
data3 - 训练集:train_3turn.jsonl,1637 条记录
- 验证集:valid_3turn.jsonl,40 条记录
- 所有划分共享统一的 schema
数据规模统计
- 总故事词数(data3):约 3.0M
- 训练集(data3):
- 行数:1637
- 词数:最小值 1503 / 中位数 1781 / 最大值 2099
- 总词数:2,934,795
- 每轮中位词数(实际):534
- 验证集:40 条记录(1581–2003 词)
Prompt 模板
指令共享一个轴网格 —— 34 种体裁 × 第一/第二/第三人称 × 过去/现在时态 × 成对风格标签 —— 以六种轮换措辞渲染(所有划分中每类约 300 行):
Write a short story in the {genre} genre, in {pov} person, {tense} tense. Draw on the flavors of {f1} and {f2}.…; incorporate elements of {f1} and {f2}.Write a {genre} story, in {pov} person, {tense} tense, that leans on {f1} and {f2} for atmosphere.Write a complete {genre} short story, in {pov} person, {tense} tense, with {f1} and {f2} woven into the setting.Write a short story in the {genre} genre, in {pov} person, {tense} tense. Let {f1} and {f2} shape its world.Compose a {genre} short story, in {pov} person, {tense} tense. Let {f1} and {f2} inform the premise.
Schema(字段结构)
| 字段 | 类型 | 说明 |
|---|---|---|
instruction |
string | 3 轮写作任务(上述模板) |
pieces |
list[string] ×3 | 故事分段,每轮一段(均为散文) |
turn_words |
list[int] ×3 | 教师为三轮预生成的词数计划(总和约等于 words) |
words |
int | 记录的总词数 —— 在编辑前记录,因此与 pieces 总和有少量偏差(尾部最多约 280 词) |
分段长度说明
分段长度与 turn_words 计划的比例(data3 训练集,实际/目标比):
- 第 1 轮中位数 1.00(p10–p90 0.99–1.00)
- 第 2 轮中位数 1.71(1.43–1.96)
- 第 3 轮中位数 0.27(0.06–0.60)
这是存储产物,而非教师未按计划生成 —— 已组装的故事在段落边界处按照接近累计计划目标的位置重新切分为三段。除第 1 轮外,各轮长度应视为近似值。
使用方法
python from datasets import load_dataset ds = load_dataset("baiango/minicpm5-sft3-3turn", "data3")
生成过程与局限
- 完全合成:指令由模板组装;故事文本由更强的教师 LLM 蒸馏。教师的偏差会延续到数据中。
- 仅英语;仅虚构作品。指令约束(体裁/时态)在总体上可靠,但底层数据中的 POV(人称视角)依从性不完美。
- 除自动化质量门外无人为策展;不打算作为阅读语料库。