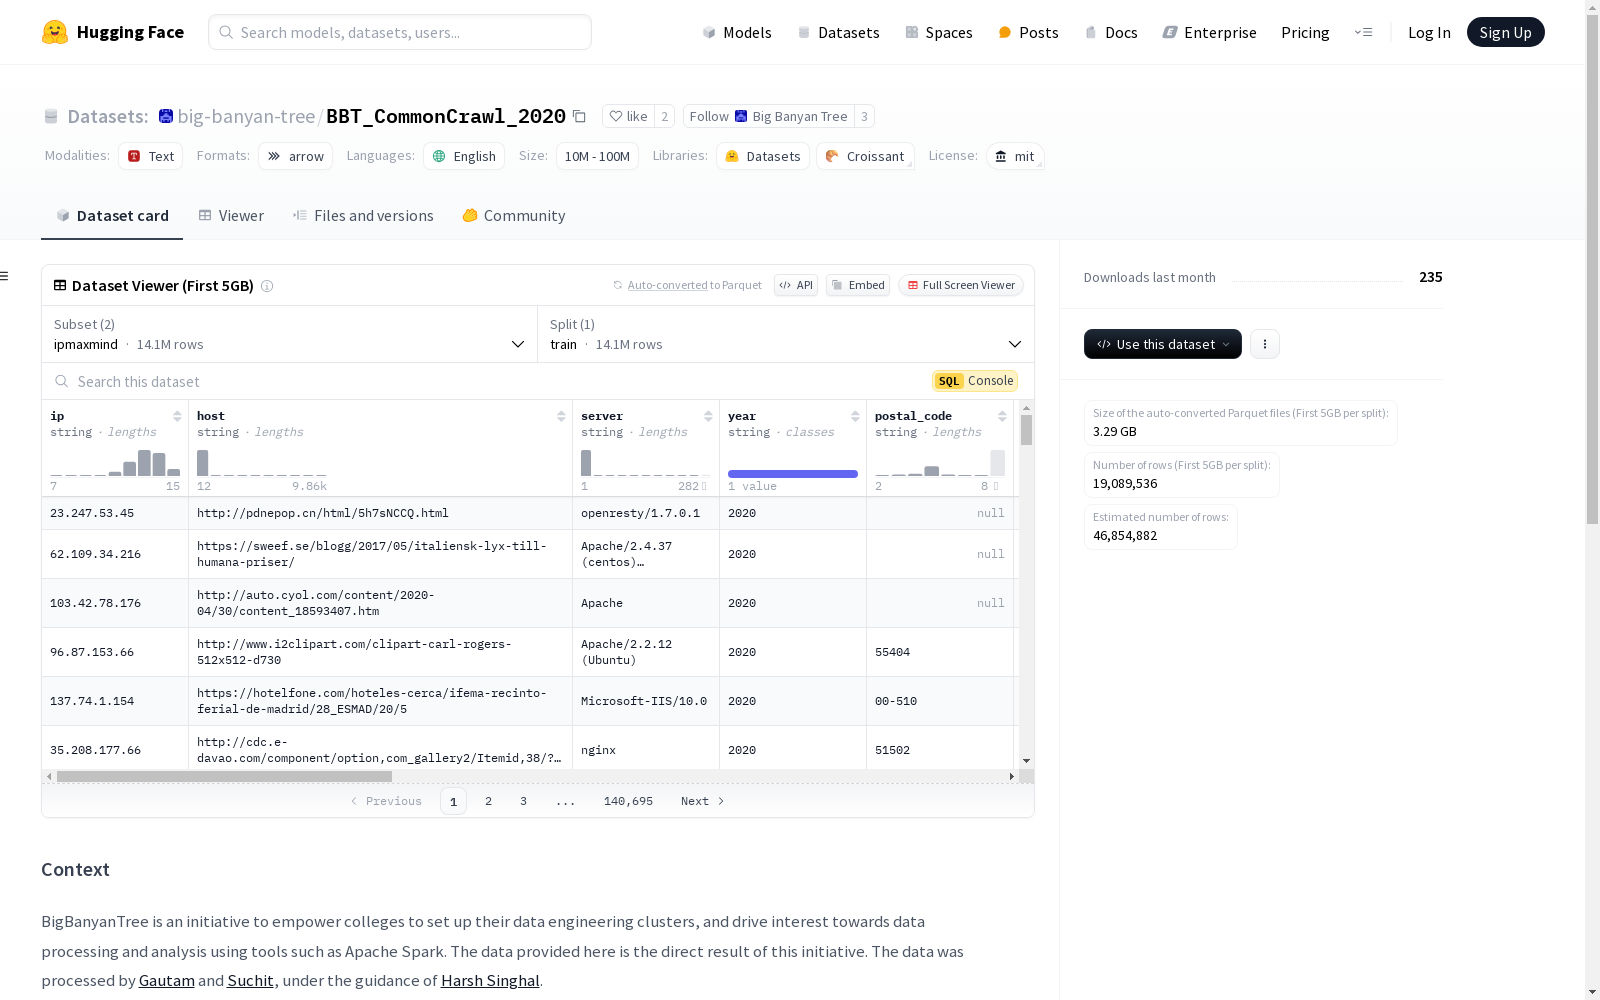
BBT_CommonCrawl_2020
收藏资源简介:
BBT-CC20数据集是BigBanyanTree项目的一部分,旨在帮助学院建立数据工程集群,并推动使用Apache Spark等工具进行数据处理和分析的兴趣。数据由Gautam和Suchit在Harsh Singhal的指导下处理。每个parquet文件包含从Common Crawl WARC文件中提取的字段表。数据是互联网的原始样本,未经过滤,可能包含推广不良内容和虚假信息的URL,使用时需根据需要进行过滤。
The BBT-CC20 dataset is part of the BigBanyanTree project, which aims to support academic institutions in establishing data engineering clusters and cultivating interest in data processing and analysis using tools such as Apache Spark. The dataset was processed by Gautam and Suchit under the supervision of Harsh Singhal. Each Parquet file contains a table of fields extracted from Common Crawl WARC files. The data constitutes an unfiltered raw sample of the internet, and may contain URLs promoting harmful content and misinformation; appropriate filtering should be conducted when utilizing this dataset.
数据集概述
基本信息
- 名称: BBT-CC20
- 许可证: MIT
- 语言: 英语
- 数据量: 10M<n<100M
配置
- 配置名称: script_extraction
- 数据文件: script_extraction_out/*.parquet
- 配置名称: ipmaxmind
- 数据文件: ipmaxmind_out/*.parquet
内容描述
- 每个parquet文件包含从Common Crawl WARC文件中提取的字段。
- 数据未经筛选,可能包含推广不良内容和虚假信息的URL。
- 建议根据需求进行过滤。