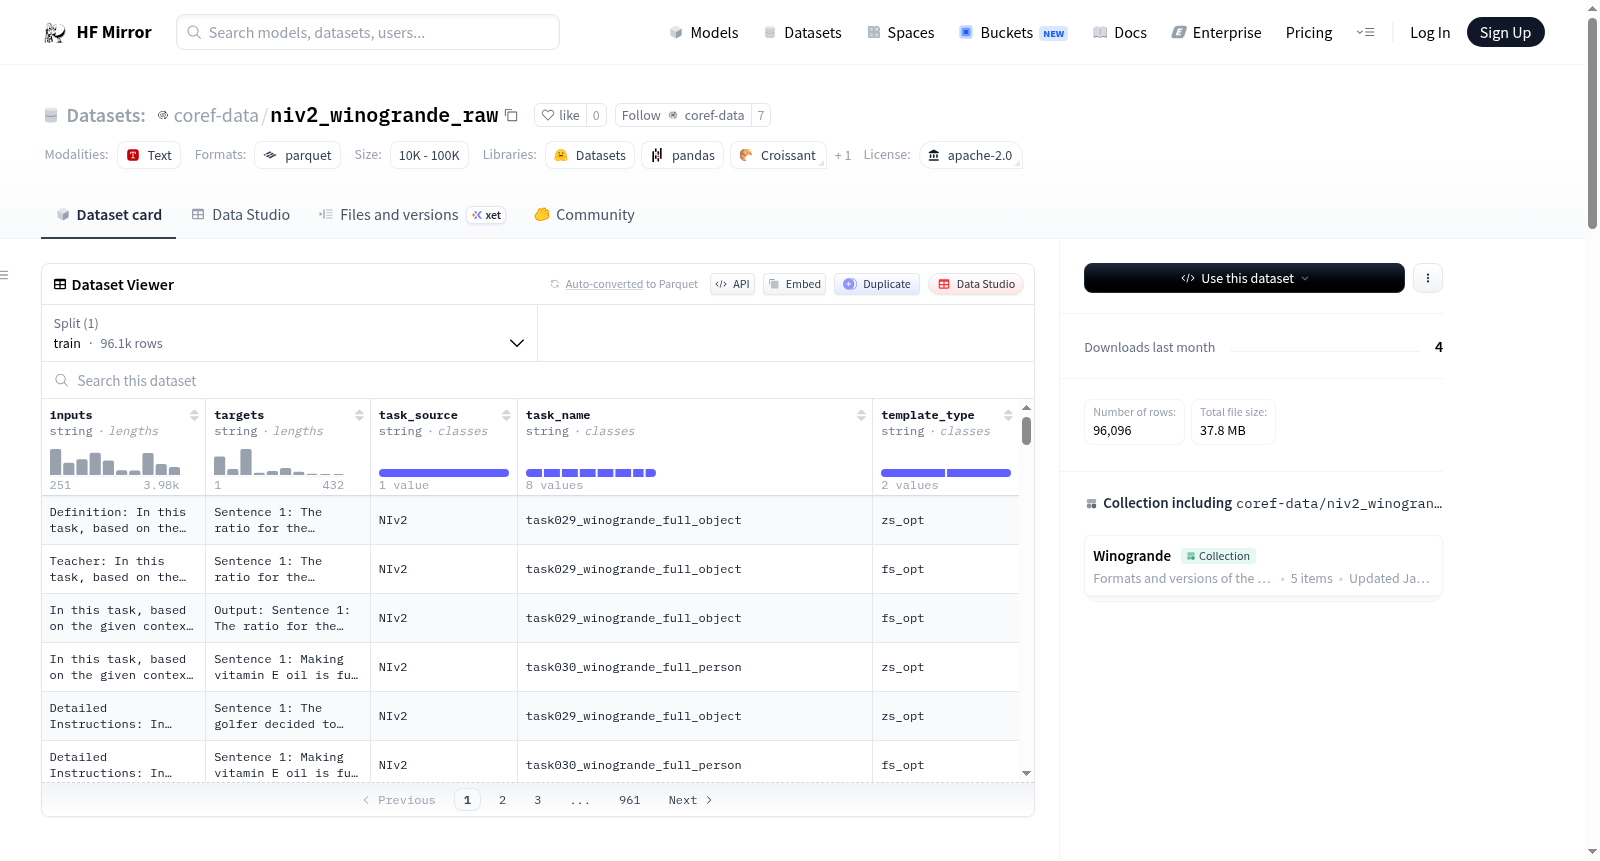
coref-data/niv2_winogrande_raw
收藏资源简介:
--- license: apache-2.0 --- # Natural Instructions v2 Winogrande Tasks - Project: https://github.com/allenai/natural-instructions - Data source: [DataProvenanceInitiative/niv2_submix_original](https://huggingface.co/datasets/DataProvenanceInitiative/niv2_submix_original) ## Details This dataset contains all Winogrande examples that were included in the [Flan 2022 collection](https://github.com/google-research/FLAN/tree/main/flan/v2) which were orignally published in Super-Natural-Instructions. The data is copied from the preprocessed Natural Instructions v2 dataset at [DataProvenanceInitiative/niv2_submix_original](https://huggingface.co/datasets/DataProvenanceInitiative/niv2_submix_original). These tasks are: 1. 'task029_winogrande_full_object': Creating a pair of fill in the blank question-answer pairs on objects. 2. 'task030_winogrande_full_person': Creating a pair of fill in the blank questions on persons. 3. 'task031_winogrande_question_generation_object': Writing a fill in the blank question on objects. 4. 'task032_winogrande_question_generation_person': Writing a fill in the blank question on persons. 5. 'task033_winogrande_answer_generation': Answering a fill in the blank question on objects. 6. 'task034_winogrande_question_modification_object': Modifying a fill in the blank question on objects. 7. 'task035_winogrande_question_modification_person': Modifying a fill in the blank question on persons. 8. 'task1391_winogrande_easy_answer_generation': Answering a fill in the blank question on objects. ### Fields - `inputs`: a `string` feature. - `targets`: a `string` feature. - `task_source`: a `string` feature. - `task_name`: a `string` feature. - `template_type`: a `string` feature. ## Citation ``` @inproceedings{wang-etal-2022-super, title = "Super-{N}atural{I}nstructions: Generalization via Declarative Instructions on 1600+ {NLP} Tasks", author = "Wang, Yizhong and Mishra, Swaroop and Alipoormolabashi, Pegah and Kordi, Yeganeh and Mirzaei, Amirreza and Naik, Atharva and Ashok, Arjun and Dhanasekaran, Arut Selvan and Arunkumar, Anjana and Stap, David and Pathak, Eshaan and Karamanolakis, Giannis and Lai, Haizhi and Purohit, Ishan and Mondal, Ishani and Anderson, Jacob and Kuznia, Kirby and Doshi, Krima and Pal, Kuntal Kumar and Patel, Maitreya and Moradshahi, Mehrad and Parmar, Mihir and Purohit, Mirali and Varshney, Neeraj and Kaza, Phani Rohitha and Verma, Pulkit and Puri, Ravsehaj Singh and Karia, Rushang and Doshi, Savan and Sampat, Shailaja Keyur and Mishra, Siddhartha and Reddy A, Sujan and Patro, Sumanta and Dixit, Tanay and Shen, Xudong", editor = "Goldberg, Yoav and Kozareva, Zornitsa and Zhang, Yue", booktitle = "Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing", month = dec, year = "2022", address = "Abu Dhabi, United Arab Emirates", publisher = "Association for Computational Linguistics", url = "https://aclanthology.org/2022.emnlp-main.340", doi = "10.18653/v1/2022.emnlp-main.340", pages = "5085--5109", abstract = "How well can NLP models generalize to a variety of unseen tasks when provided with task instructions? To address this question, we first introduce Super-NaturalInstructions, a benchmark of 1,616 diverse NLP tasks and their expert-written instructions. Our collection covers 76 distinct task types, including but not limited to classification, extraction, infilling, sequence tagging, text rewriting, and text composition. This large and diverse collection of tasks enables rigorous benchmarking of cross-task generalization under instructions{---}training models to follow instructions on a subset of tasks and evaluating them on the remaining unseen ones. Furthermore, we build Tk-Instruct, a transformer model trained to follow a variety of in-context instructions (plain language task definitions or k-shot examples). Our experiments show that Tk-Instruct outperforms existing instruction-following models such as InstructGPT by over 9{\%} on our benchmark despite being an order of magnitude smaller. We further analyze generalization as a function of various scaling parameters, such as the number of observed tasks, the number of instances per task, and model sizes. We hope our dataset and model facilitate future progress towards more general-purpose NLP models.", } ```
许可证:Apache-2.0 # 自然指令v2温诺格兰德(Winogrande)任务集 - 项目:https://github.com/allenai/natural-instructions - 数据来源:[DataProvenanceInitiative/niv2_submix_original](https://huggingface.co/datasets/DataProvenanceInitiative/niv2_submix_original) ## 数据集详情 本数据集包含收录于[Flan 2022数据集合集](https://github.com/google-research/FLAN/tree/main/flan/v2)中的全部温诺格兰德示例,这些示例最初发表于《Super-Natural-Instructions》研究中。 本数据集的数据源自[DataProvenanceInitiative/niv2_submix_original](https://huggingface.co/datasets/DataProvenanceInitiative/niv2_submix_original)中的预处理版自然指令v2数据集。 本数据集包含以下任务: 1. `task029_winogrande_full_object`:针对物体构建一组填空式问答对。 2. `task030_winogrande_full_person`:针对人物构建一组填空式问题。 3. `task031_winogrande_question_generation_object`:针对物体撰写填空式问题。 4. `task032_winogrande_question_generation_person`:针对人物撰写填空式问题。 5. `task033_winogrande_answer_generation`:针对物体的填空式问题给出答案。 6. `task034_winogrande_question_modification_object`:修改针对物体的填空式问题。 7. `task035_winogrande_question_modification_person`:修改针对人物的填空式问题。 8. `task1391_winogrande_easy_answer_generation`:针对物体的填空式问题给出简易答案。 ### 字段说明 - `inputs`:字符串类型特征。 - `targets`:字符串类型特征。 - `task_source`:字符串类型特征。 - `task_name`:字符串类型特征。 - `template_type`:字符串类型特征。 ## 引用 bibtex @inproceedings{wang-etal-2022-super, title = "Super-{N}atural{I}nstructions: Generalization via Declarative Instructions on 1600+ {NLP} Tasks", author = "Wang, Yizhong and Mishra, Swaroop and Alipoormolabashi, Pegah and Kordi, Yeganeh and Mirzaei, Amirreza and Naik, Atharva and Ashok, Arjun and Dhanasekaran, Arut Selvan and Arunkumar, Anjana and Stap, David and Pathak, Eshaan and Karamanolakis, Giannis and Lai, Haizhi and Purohit, Ishan and Mondal, Ishani and Anderson, Jacob and Kuznia, Kirby and Doshi, Krima and Pal, Kuntal Kumar and Patel, Maitreya and Moradshahi, Mehrad and Parmar, Mihir and Purohit, Mirali and Varshney, Neeraj and Kaza, Phani Rohitha and Verma, Pulkit and Puri, Ravsehaj Singh and Karia, Rushang and Doshi, Savan and Sampat, Shailaja Keyur and Mishra, Siddhartha and Reddy A, Sujan and Patro, Sumanta and Dixit, Tanay and Shen, Xudong", editor = "Goldberg, Yoav and Kozareva, Zornitsa and Zhang, Yue", booktitle = "Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing", month = dec, year = "2022", address = "Abu Dhabi, United Arab Emirates", publisher = "Association for Computational Linguistics", url = "https://aclanthology.org/2022.emnlp-main.340", doi = "10.18653/v1/2022.emnlp-main.340", pages = "5085--5109", abstract = "How well can NLP models generalize to a variety of unseen tasks when provided with task instructions? To address this question, we first introduce Super-NaturalInstructions, a benchmark of 1,616 diverse NLP tasks and their expert-written instructions. Our collection covers 76 distinct task types, including but not limited to classification, extraction, infilling, sequence tagging, text rewriting, and text composition. This large and diverse collection of tasks enables rigorous benchmarking of cross-task generalization under instructions---training models to follow instructions on a subset of tasks and evaluating them on the remaining unseen ones. Furthermore, we build Tk-Instruct, a transformer model trained to follow a variety of in-context instructions (plain language task definitions or k-shot examples). Our experiments show that Tk-Instruct outperforms existing instruction-following models such as InstructGPT by over 9% on our benchmark despite being an order of magnitude smaller. We further analyze generalization as a function of various scaling parameters, such as the number of observed tasks, the number of instances per task, and model sizes. We hope our dataset and model facilitate future progress towards more general-purpose NLP models.", }
Natural Instructions v2 Winogrande Tasks
数据集详情
该数据集包含所有被包含在Flan 2022 collection中的Winogrande示例,这些示例最初发表在Super-Natural-Instructions中。数据来自预处理的Natural Instructions v2数据集DataProvenanceInitiative/niv2_submix_original。
任务类型
task029_winogrande_full_object: 创建关于对象的填空题-答案对。task030_winogrande_full_person: 创建关于人物的填空题。task031_winogrande_question_generation_object: 编写关于对象的填空题。task032_winogrande_question_generation_person: 编写关于人物的填空题。task033_winogrande_answer_generation: 回答关于对象的填空题。task034_winogrande_question_modification_object: 修改关于对象的填空题。task035_winogrande_question_modification_person: 修改关于人物的填空题。task1391_winogrande_easy_answer_generation: 回答关于对象的填空题。
数据字段
inputs: 字符串特征。targets: 字符串特征。task_source: 字符串特征。task_name: 字符串特征。template_type: 字符串特征。
引用
@inproceedings{wang-etal-2022-super, title = "Super-{N}atural{I}nstructions: Generalization via Declarative Instructions on 1600+ {NLP} Tasks", author = "Wang, Yizhong and Mishra, Swaroop and Alipoormolabashi, Pegah and Kordi, Yeganeh and Mirzaei, Amirreza and Naik, Atharva and Ashok, Arjun and Dhanasekaran, Arut Selvan and Arunkumar, Anjana and Stap, David and Pathak, Eshaan and Karamanolakis, Giannis and Lai, Haizhi and Purohit, Ishan and Mondal, Ishani and Anderson, Jacob and Kuznia, Kirby and Doshi, Krima and Pal, Kuntal Kumar and Patel, Maitreya and Moradshahi, Mehrad and Parmar, Mihir and Purohit, Mirali and Varshney, Neeraj and Kaza, Phani Rohitha and Verma, Pulkit and Puri, Ravsehaj Singh and Karia, Rushang and Doshi, Savan and Sampat, Shailaja Keyur and Mishra, Siddhartha and Reddy A, Sujan and Patro, Sumanta and Dixit, Tanay and Shen, Xudong", editor = "Goldberg, Yoav and Kozareva, Zornitsa and Zhang, Yue", booktitle = "Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing", month = dec, year = "2022", address = "Abu Dhabi, United Arab Emirates", publisher = "Association for Computational Linguistics", url = "https://aclanthology.org/2022.emnlp-main.340", doi = "10.18653/v1/2022.emnlp-main.340", pages = "5085--5109", abstract = "How well can NLP models generalize to a variety of unseen tasks when provided with task instructions? To address this question, we first introduce Super-NaturalInstructions, a benchmark of 1,616 diverse NLP tasks and their expert-written instructions. Our collection covers 76 distinct task types, including but not limited to classification, extraction, infilling, sequence tagging, text rewriting, and text composition. This large and diverse collection of tasks enables rigorous benchmarking of cross-task generalization under instructions{---}training models to follow instructions on a subset of tasks and evaluating them on the remaining unseen ones. Furthermore, we build Tk-Instruct, a transformer model trained to follow a variety of in-context instructions (plain language task definitions or k-shot examples). Our experiments show that Tk-Instruct outperforms existing instruction-following models such as InstructGPT by over 9{%} on our benchmark despite being an order of magnitude smaller. We further analyze generalization as a function of various scaling parameters, such as the number of observed tasks, the number of instances per task, and model sizes. We hope our dataset and model facilitate future progress towards more general-purpose NLP models.", }