zlab-princeton/i1-captions
收藏资源简介:
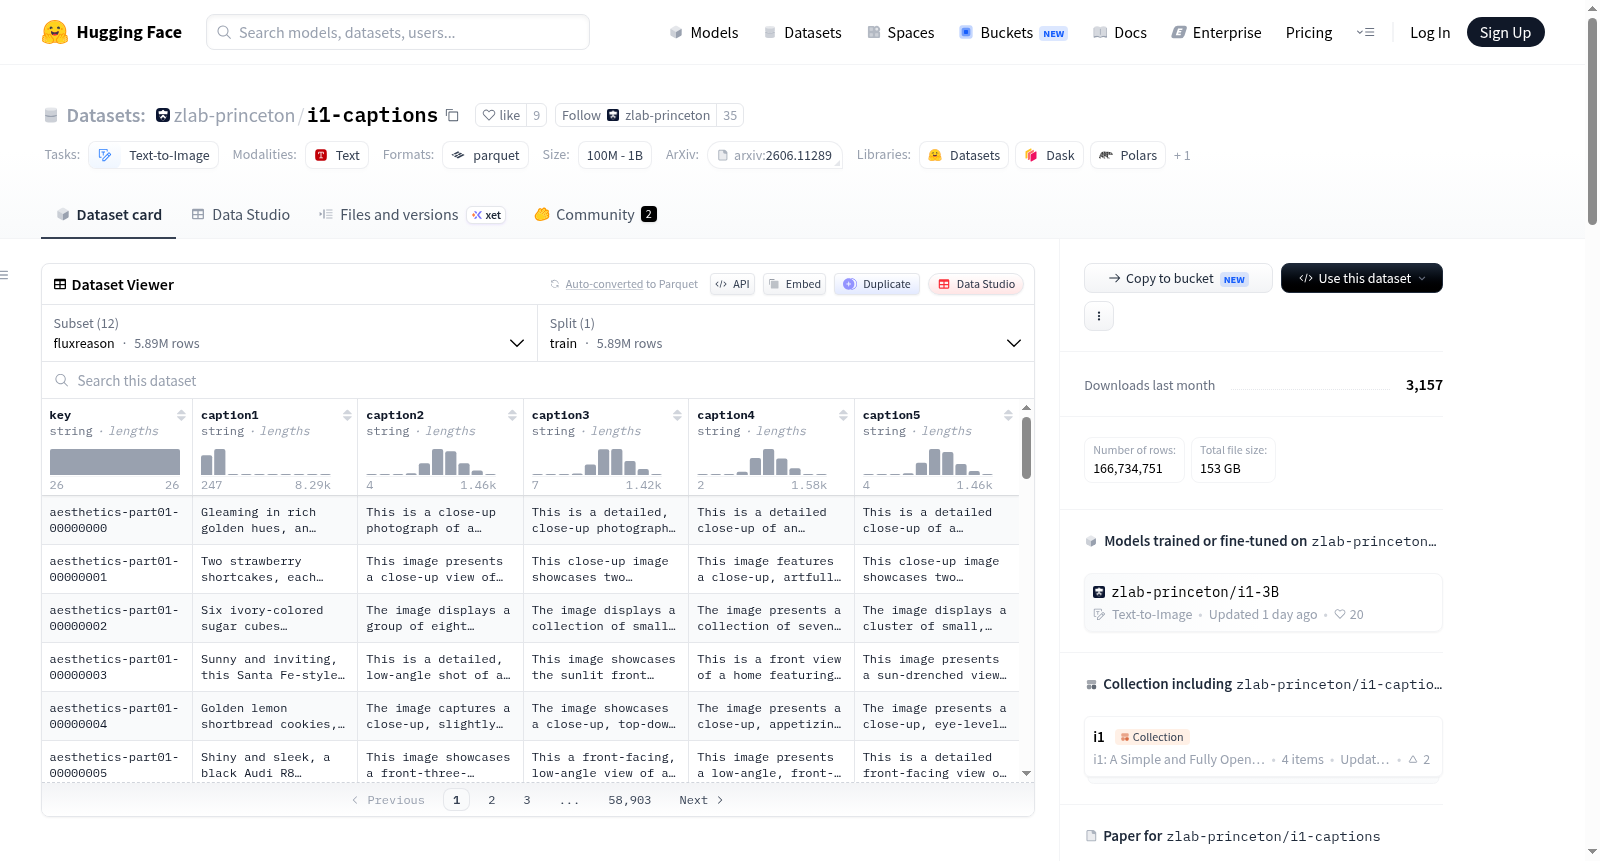
该数据集是一个用于文本到图像模型训练的数据集,包含用于i1模型受控实验和最终训练的所有标题。数据集由12个精选图像子集组成(如fluxreason、gptedit、imagenet22k等),每个子集提供大量图像-标题对,标题通过视觉语言模型(如Qwen3-VL-30B-A3B)合成生成,包括长标题、短标题以及基于不同预处理图像的变体。这些标题用于支持文本到图像模型的训练和消融研究,例如评估不同VLMs作为合成标题生成器的效果、标题长度的影响以及图像预处理方法。数据集以Parquet格式存储,可通过Hugging Face的datasets库加载。
This dataset contains all captions used in the controlled experiments and final training of the i1 text-to-image model. It comprises 12 curated image subsets (e.g., fluxreason, gptedit, imagenet22k), each providing a large number of image-caption pairs. The captions are synthetically generated by vision-language models (e.g., Qwen3-VL-30B-A3B), including long captions, short captions, and variants based on differently preprocessed images. These captions are used to support text-to-image model training and ablation studies, such as evaluating different VLMs as synthetic captioners, the impact of caption length, and image preprocessing methods. The dataset is stored in Parquet format and can be loaded via the Hugging Face datasets library.