SINAI/ALIA-es-cultural-heritage-pairs
收藏资源简介:
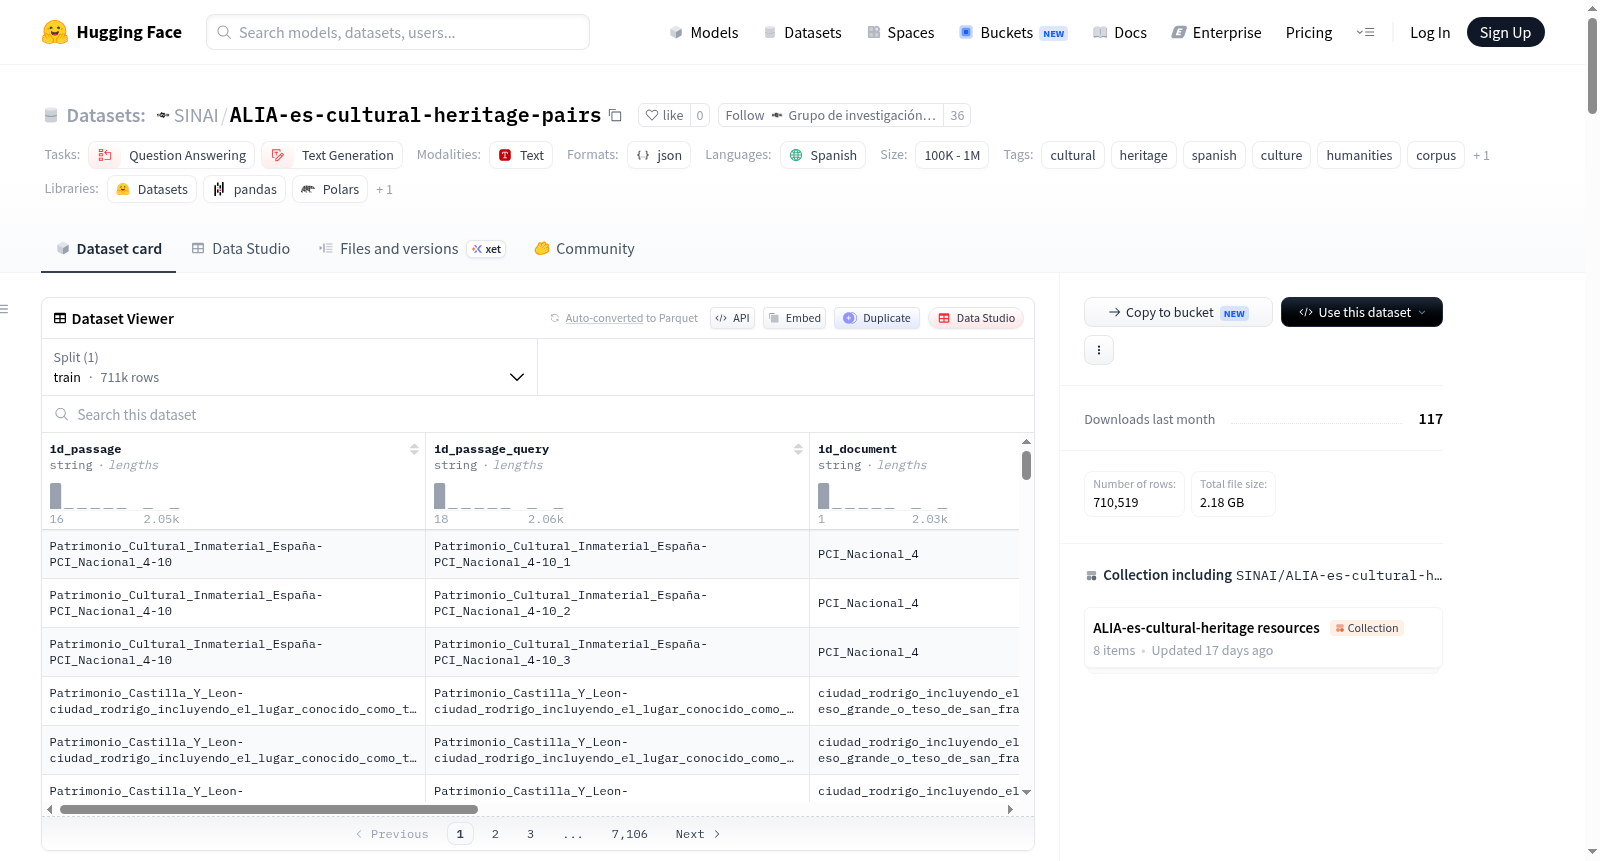
ALIA西班牙文化与遗产检索对语料库包含表格实例,旨在使用基于段落的查询数据训练和评估检索导向模型(如密集检索器/嵌入编码器),这些数据是通过集成在ALIA编码器管道中的Qwen风格提示工作流生成的。它保留了原始文档和段落的来源,同时暴露了问题类型和难度(范围从高中到博士水平)等控制参数。数据格式为每行一个基于段落的训练/评估实例;方法是通过Qwen风格LLM提示从段落生成查询;难度等级分为高中、大学和博士三个级别;范围聚焦于特定领域的文化遗产和人文文本,并与跟踪文档/块来源的文档分割工作流兼容。
The ALIA Spanish Cultural and Heritage Retrieval Pairs Corpus contains tabular instances designed to train and evaluate retrieval-oriented models (e.g., dense retrievers / embedding encoders) using passage-grounded query data produced with a Qwen-style prompting workflow integrated in the ALIA encoders pipeline. It preserves provenance to the original document and passage while exposing controls such as question type and difficulty (ranging from high_school to phd level). Data format: One row per passage-based training/evaluation instance. Method: query is generated from passage using a Qwen-style LLM prompting approach defined in the project scripts. Difficulty scale: difficulty is a categorical label with three levels: high_school, university, or phd. Scope: Focused on domain-specific cultural heritage and humanities text, and compatible with document segmentation workflows that track document/chunk provenance.