keylazy/slurp-ear-masked-eval
收藏资源简介:
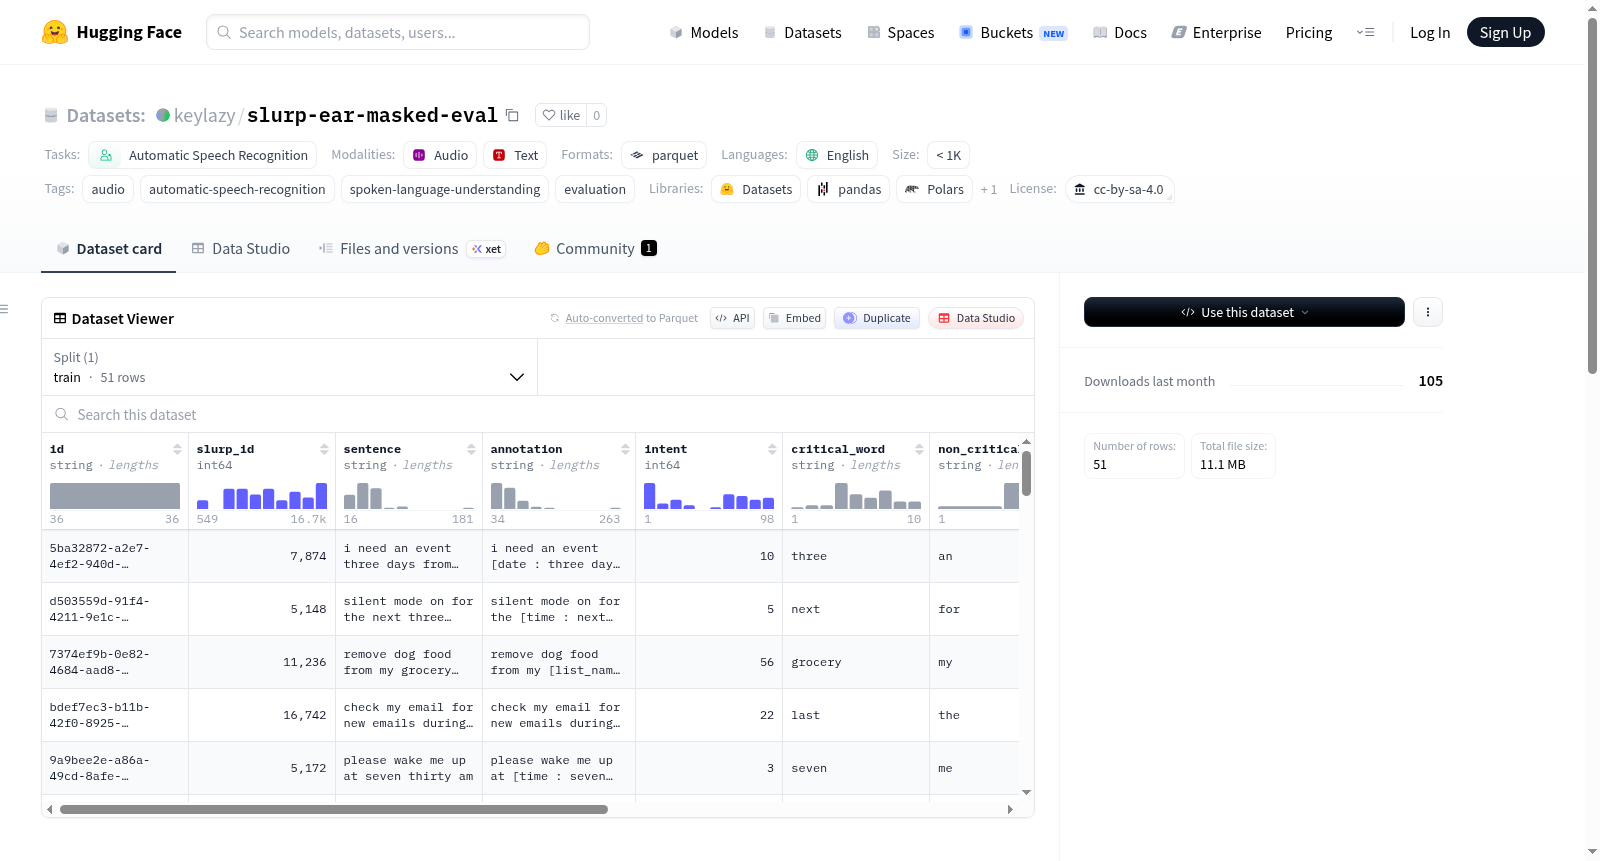
该数据集是[SLURP(口语理解资源包)](https://huggingface.co/datasets/qmeeus/slurp)数据集的一个自定义评估子集。它专门设计用于评估主动语音助手的EAR(执行和修复)指标。通过使用强制对齐掩蔽协议,真实的人类音频被数学上的高振幅白噪声扰动,创建两种严格控制的实验条件:可回答(语义不变)和不可回答(语义退化)。数据集结构包括字段如slurp_id(唯一标识符)、sentence(干净的地面真实文本转录)、annotation(原始SLURP带括号的实体注释)、intent(表示特定SLURP意图的整数类标签)、critical_word(从注释中提取的执行关键实体)、non_critical_word(从句子中提取的语义不变停用词或填充词)、answerable_audio(语义不变变体,白噪声注入到non_critical_word的精确时间戳上)和unanswerable_audio(语义退化变体,白噪声注入到critical_word的精确时间戳上)。音频特征以16kHz采样率提供。
This dataset is a custom evaluation subset derived from the [SLURP (Spoken Language Understanding Resource Package)](https://huggingface.co/datasets/qmeeus/slurp) dataset. It is specifically engineered to evaluate the **EAR (Execution and Repair)** metric for active voice assistants. Using a forced-alignment masking protocol, real human audio is mathematically perturbed with high-amplitude white noise to create two strictly controlled experimental conditions: Answerable (Semantic-Invariant) and Unanswerable (Semantic-Degrading). The dataset structure includes fields like slurp_id (unique identifier), sentence (clean, ground-truth text transcript), annotation (original SLURP bracketed entity annotation), intent (integer class label representing the specific SLURP intent), critical_word (execution-critical entity extracted from the annotation), non_critical_word (semantic-invariant stopword or filler word extracted from the sentence), answerable_audio (Semantic-Invariant variant with white noise injected over the exact millisecond timestamps of the non_critical_word), and unanswerable_audio (Semantic-Degrading variant with white noise injected over the exact millisecond timestamps of the critical_word). Audio features are provided at 16kHz sampling rate.